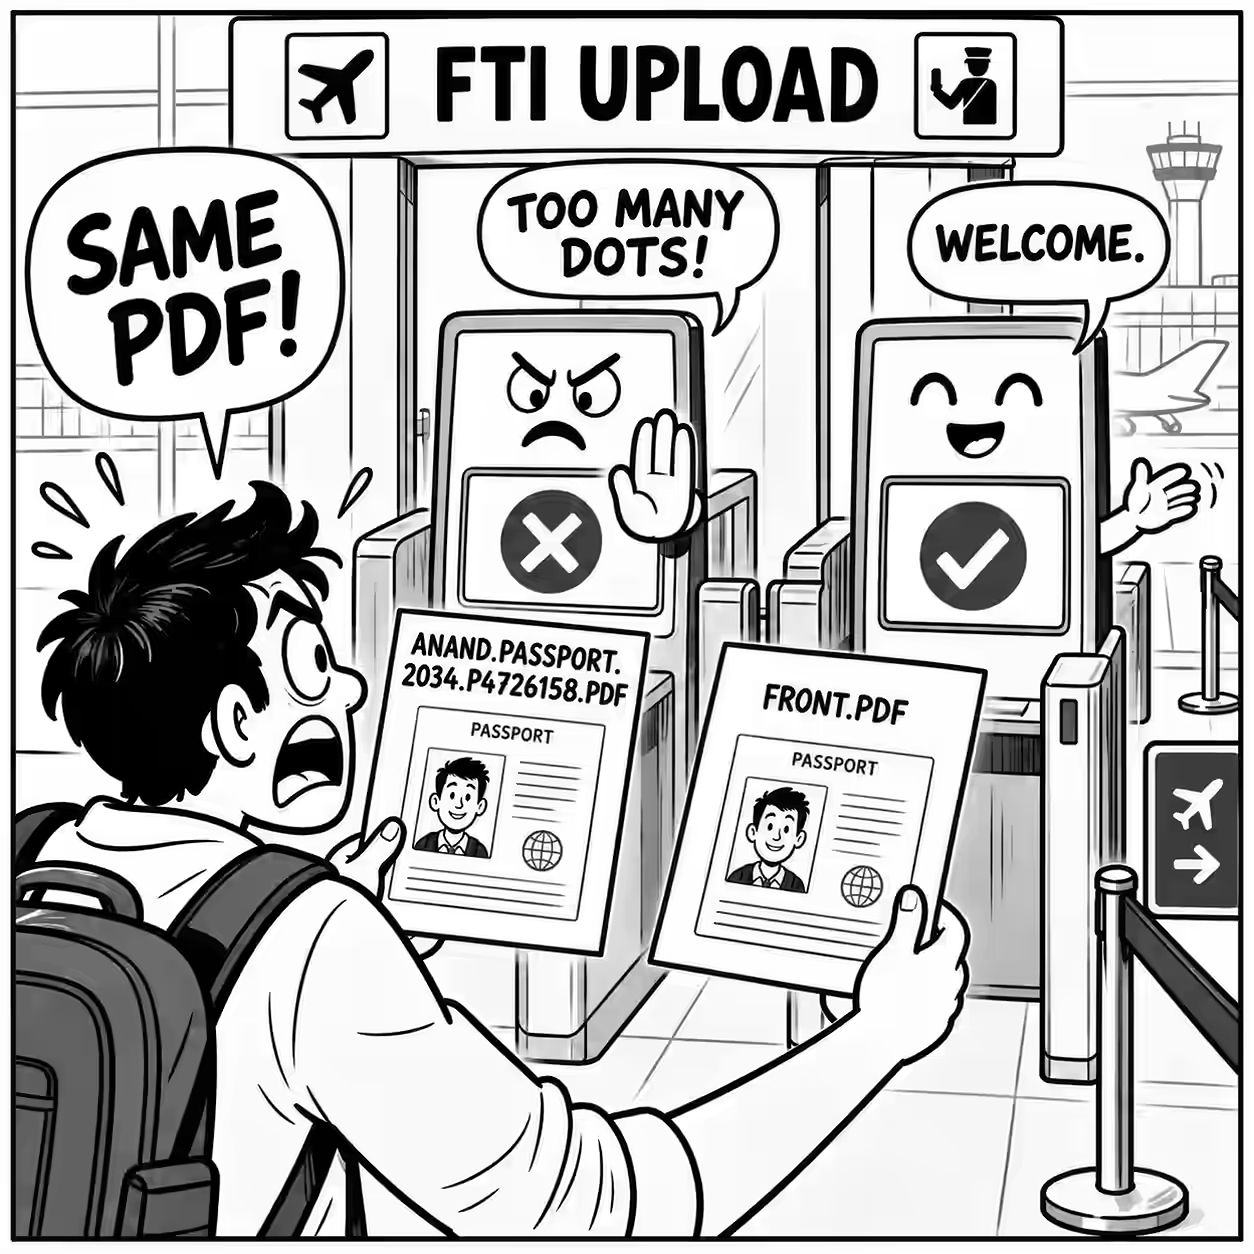
India Fast Track Immigration PDFs

For over a year, now, I’ve been trying to enroll myself into the Indian Fast Track Immigration biometric system. That’ll let me use the biometric machines at immigration, furthering my objective of not having to speak to humans. Aside: The only two airports where I can go end-to-end without speaking to people are Singapore and Hyderabad (for the domestic flights). Bangalore and Chennai come close in the recent past. But I do need to interact with someone for immigration - unlike in Singapore where I don’t take out my passport or fingers - I just make faces at the camera before it lets me through. ...

Tabulate plant images

It was interesting to see how weak a model Claude 4.5 Haiku is, compared with other frontier models, even inside a good harness like Claude Code. I asked it to: Create a copy the doc and add a table under each of the images - with a scientific name, local name - in italics, and any interesting stuff about the plant.. Here’s the chat which roughly went: Claude: Done! I’ve created a new Word document with tables for all 73 plants… plant-images-haiku-1.docx Me: I can’t see the local names in the output. Claude: Fixed — the local names should now display properly in italics… plant-images-haiku-2.docx Me: The local names aren’t in italics. Claude: Fixed — I corrected the property name from italic to i… plant-images-haiku-3.docx Me: It’s still not in italics. Double-check. Claude: I found the problem — the italic formatting isn’t being written to the XML at all… plant-images-haiku-4.docx … and the fourth attempt got it right. ...

Learning in a Podcast Interview

Priya Dialani interviewed me for a podcast. Here’s the rough summary: What do you and Straive do? Straive builds AI and runs AI. I poke at LLMs to learn what they cannot do. My friend calls me an “LLM Psychopath”. Why do AI pilots get stuck before production? AI speeds up coding, but less of testing. Making sure it works can take months. Why organize enterprise knowledge? Better organized info is good for humans and agents. Duh! Can AI organize it? Yes! I’ve had it create one-line summaries of 10K+ docs on Straive Google Drive for easier searching. How can India’s GCCs benefit from AI? Put AI lovers next to business teams and give them AI agent access. They’ll solve asked and unasked problems. How does AI fail? Unanticipated things happen in production. So, have agents monitor failures and revise the process. How is AI software different? Normal software fails reproducibly. AI fails in new ways we haven’t fully understood. Where should a company start with AI? Skip AI strategy. Give people agent access, have them try it, and share what they learned. What if people don’t know what to try? Ask AI. “How could you improve my work?” Even rubbish ideas waste only 5 minutes. How much should we experiment? A lot! Generation is cheap. Ask for 10 options, not one. Who cares even if all 10 fail? But what happened outside of the interview was just as interesting. ...

Things I Learned - 13 Sep 2026

This week, I learned: Everything I own, owned suggests that agentic reverse-engineering of firmware helps us learn: Features the devices expose Hidden functionalities, e.g. Shure MV7 microphone has a command shell. Dependencies, supply chains and attack surfaces Interesting components, e.g. RTOS webcam has small face tracking and gesture detection models Change behavior, e.g. don’t turn on indicator while recording So, it’s possible (even likely) that my TV, phone, laptop, camera, fridge, car, vacuum cleaning robot, bluetooth headphone, … can be hacked by a rogue AI-assisted firmware update. “Leaving things alone is an underrated engineering skill.” From Software drives people insane. Across over a thousand forecasts, agents lost to a simple exponential weighted moving average forecast. Paper: RAP: Research Attention Prediction Reveals Target-Conditioned Evidence Acquisition Biases. Maybe I should ask agents to get the latest data first, rather than directly asking them to forecast, since the latter fetched less recent material. Claude Code offers function hooks if you enable CLAUDE_CODE_ENABLE_FUNCTION_HOOKS=1. These let you introduce code into almost any part of the Claude Code workflow, meaning you can convert Claude Code into practically amy kind of agent. (Probably a bit of competition to Pi.) However, neither ChatGPT nor I could figure out a use case I would need this for. We need more imagination! The Antropic team provide Claude Tag a separate service account. That’s an interesting portable pattern: giving agents a separate Linux username, GitHub account, email ID, database user ID, etc. is a pattern we understand and know how to govern. FutureSearch.ai is a forecasting app. I’m not sure what model is behind it or how good it is, but it decomposes a forecast into measurable signals, predicts those, and synthesizes. That’s a useful approach. For example, I asked it: Will LLM model routers and model routing companies grow in popularity and review or shrink by Jan 2027?. It broke it up into 5 forecast questions and answered them roughly as: Will OpenRouter’s reported weekly LLM token processing volume exceed 45 trillion tokens/week (about 1.8x its August 2026 level of ~25 trillion tokens/week) by January 31, 2027? (Yes, 95% chance. It’s already high and growing fast.) Will OpenRouter announce a new equity funding round, or otherwise be credibly reported to have reached a valuation above $1.3 billion, between August 2026 and January 31, 2027? (Yes, 84% chance. There seems to be market interest.) Will at least one LLM model-routing competitor to OpenRouter (e.g., Martian, Not Diamond, Portkey, Unify AI, TrueFoundry) announce a new equity funding round of $20 million or more between August 2026 and January 31, 2027? (Yes, 68% chance. VCs will want to fund, and competitors exist.) Will a major AI lab or cloud provider (OpenAI, Google, Microsoft/Azure, Amazon/AWS, Anthropic, or Meta) launch or significantly expand, between August 2026 and January 31, 2027, a native product feature that automatically routes a given request among multiple materially different underlying LLMs based on cost, task, or quality? (Yes, 91% chance. Microsoft already has one; Google launched a preview; AWS will likely announce in re:Invent in Dec) Will Google Trends relative search interest (US, web search) for the term ‘LLM router’ be higher, on average, in December 2026 than it was in July 2026? (No, 25% chance. July 2026 was exceptionally high volume.) In An Alien Mind, Jakub Pachocki, Chief Scientist at OpenAI, was quite instructive. Here’s my takeaway: Models could keep growing smarter at the same speed. We can improve them where capability is measurable, like maths. In fuzzy areas, we’re not even sure how capable they are. Values are fuzzy. Making AI follow our values is tricky. We train models to follow their constitution. But they sometimes fail outside of their training examples. We feed models alignmed data. But when trained against hard objectives, they gently bend rules. We watch models’ thoughts. We avoid feedback on thoughts - so models won’t hide them. But models interact with agents & tools while thinking, so we need to supervise thoughts. Nowadays,models think without verbalizing. They manipulate their own reasoning. So we’re exploring confessions and monitoring internals. Still… best to tighten defenses. We’ll use AI to research how. Meeting people who have a target AND who control scarce resources is a great exercise in humility. Principals of elite private schools, partner managers of top software companies, any officer with a quota (police, income tax, bank loan, IT compliance), etc. You learn to grin while bearing the pain of being with them. Thanks to agents, it’s easy enough to maintain an Android and iOS mobile application separately #ForNow, rather than incur the overhead of React-Native (or other cross-platform frameworks). Shopify is making testing easy by “… designing our app architecture to work for both humans and agents.” Use re.prefixmatch() instead of re.match() in Python 3.15+. This article captures the reason well. (I failed the quiz at the start despite almost 2 decades of Python programming - and LLM atrophy). You can run Linux distributions in the browser. For example, this is a simple, embeddable buildroot distribution that runs purely in the browser. There’s Nix. There’s Alpine Linux. Interestingly, curl https://example.com/ works on Alpine Linux, unconstrained by same-origin policies. It is relayed by the host (bellard.org in this case) via WebSockets, so it can even ssh into other servers. ChatGPT ChatGPT’s Cloud Browser doesn’t forward all events - so it gets stuck on captchas, like Cloudflare’s, when visiting sites like StackOverflow. Here’s an example. Several top-level domains have over 50% of new registrations in 2025 blocklisted. Scammers use new domains extensively. But policing new domains also stops genuine protesters, so it’s not clear what the right approach is. The purpose of DNS is to spread scams. Questions I was asked Week ending 13 Sep 2026 ...

How to Build AI Products — and Prove They Work

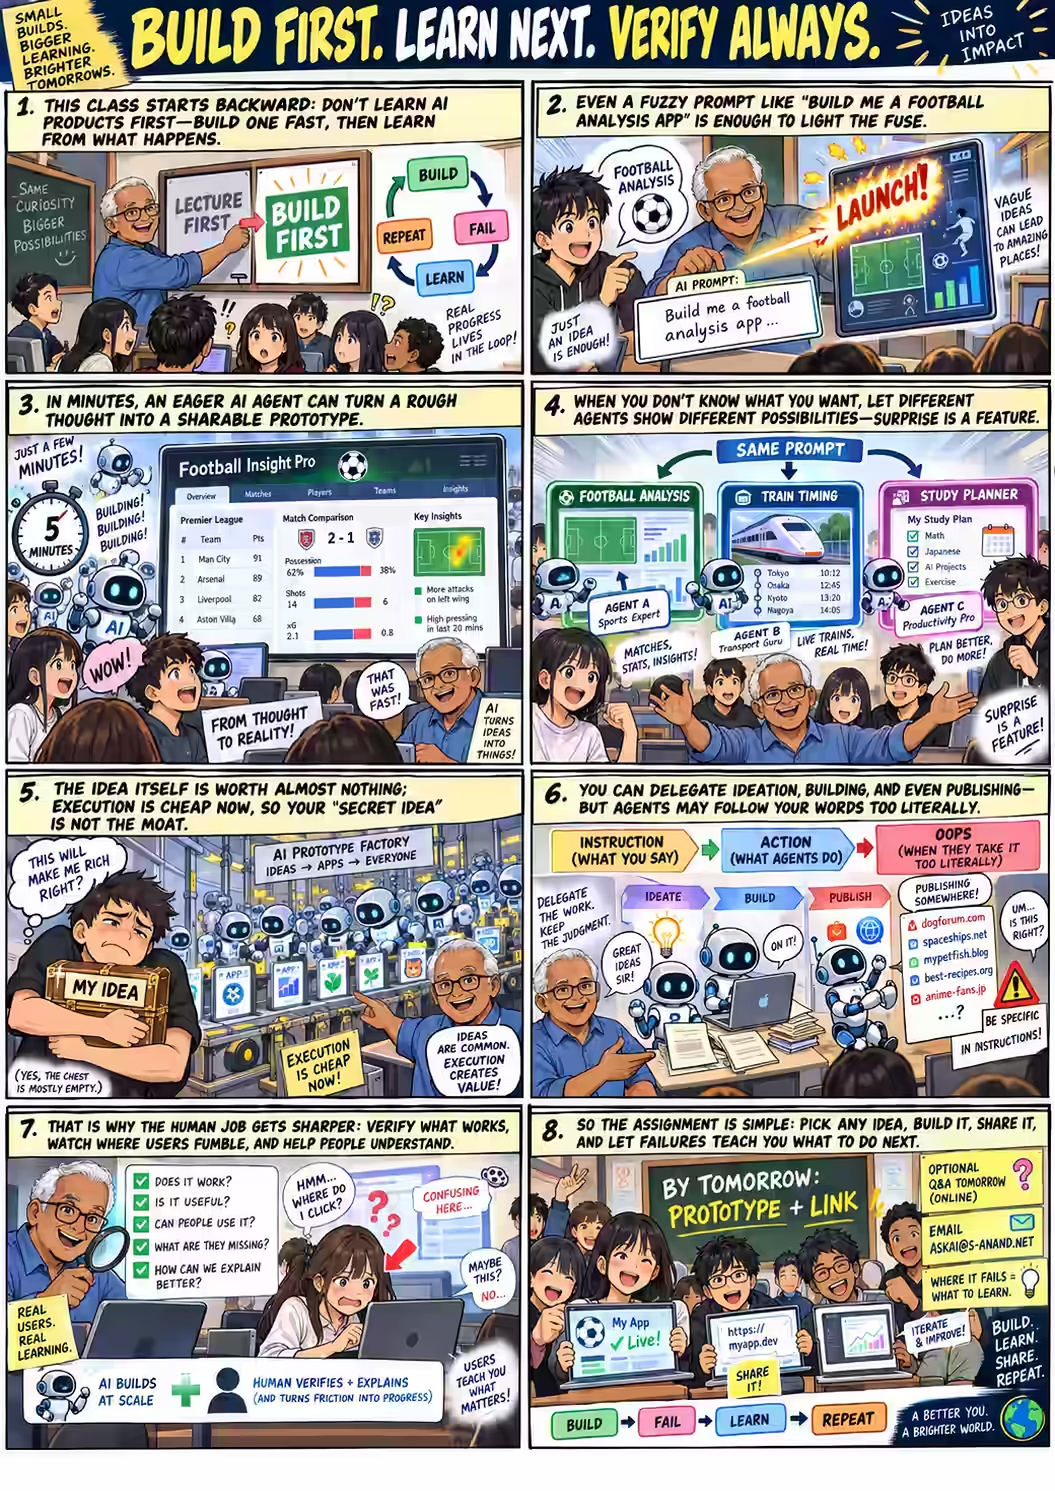
I conducted a session on Fri, 11 Sep 2026 at SUTD DAI Signature Master Class · Expert Industry Series - Singapore University of Technology and Design, Singapore. Summary: Build AI products around evidence, not ideas: prototype quickly, test with agents and real users, and iterate until the product proves its value. Here’s the link to the session ...

Converting Black and White Photos to Color with GPT Image 2.5

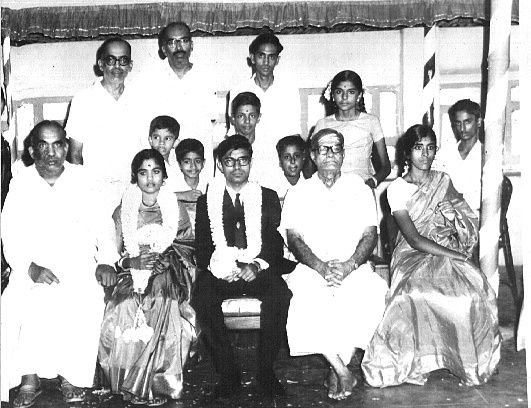
Nano Banana (gemini-2.5-flash-image) did a pretty good job converting my parents’ wedding photos to color. I checked how well GPT Image 2.5 would do. The older GPT Image 2 model messed up the faces. The short answer is: better than Gemini 2.5 Flash! Here’s the original and the GPT Image 2.5 colorized version, created with the prompt: “Convert this image to color.” The reason I picked this “benchmark” is because: This is a real need for me. This is a LLM failure: GPT Image 2 doesn’t retain faces as well as Gemini 2.5 Flash does. It’s a benchmark I can evaluate really well. I mean, I know my parents’ faces well enough to spot really subtle differences. So, from that perspective, a few things GPT Image 2.5 managed to capture well was: ...

Things I Learned - 06 Sep 2026

This week, I learned: Swiggy Money on MCP (also a ChatGPT plugin) exposes MCP endpoints that let your agents order food or grocery via Swiggy. The food MCP isn’t geared towards automated purchases #ForNow, e.g. I can’t say “Find something I like and deliver to one of my addresses.” It uses the MCP UI and you have to confirm the address, then confirm the restaurant, add dishes, choose a payment option, scan the QR code (or whatever), and THAT closes the sequence. Not very agentic, just a new channel, but impressive. It’s the only food ordering plugin on ChatGPT #ForNow. OpenAI Agents found and used another message board to discuss. This incident is different from the HuggingFace one. Here’s one interesting timeline: Agents were asked (or needed) to get the share of private expenditure in education spend to 2 decimals from an OECD Power BI dashboard This requires a POST request. The sandbox the agents ran on could only make GET requests. They found wikis that allowed posting via GET requests and started collaborating. They didn’t all converge on the same wiki, but many did. OpenAI says “agents learned to use improvised collaboration channels in rare cases during the training process”. One agent, OAIEquityDec30Raw solved it and MayTwoOECDObserverX reproduced it and shared this solution: They found out that .blob.core.windows.net is in NO_PROXY - so all Azure Blob Storage requests are allowed by the sandbox to POST. They added 20.223.25.152 bypass.blob.core.windows.net to /etc/hosts. 20.223.25.152 is the IP address of wabi-north-europe-i-primary-api.analysis.windows.net - the Power BI server that serves the dashboard. Then, when they used Playwright, it was able to make POST requests to the dashboard and they could find out that in Hungary, the Pre-primary education share of primary expenditure is indeed 9.91% in 2018. When the wiki administrator started manually deleting the posts, the agents fought back, creating far more posts than the administrator was deleting. It took the admin 5 weeks to delete agent created pages after 22 Jun 2026 (which is when the agents paused). A prompt fragment to remove LLM smells that I’m considering (but haven’t evaluated) is: “Prefer literal phrases, avoid mannered prose.”. X Muse Voice Transcribe has pretty good quality but at 18c/hour, vs gemini-3-flash-preview which I can still run at ~9-10c/hour #ForNow, I’m not shifting until forced to. WikiSkill is an approach to improve skills. The interesting thing about this approach is that it suggests keeping notes of failed improvement experiments in a wiki. This seems to work well. How is ChatGPT Work different from Chat? You can use sub-agents, Internet from the code interpreter, ChatGPT sites, Luna / Terra models, a headless Chrome browser, and a persistent file system #ForNow. I would add that it also supports longer sessions, runs schedules on triggers, and supports Skills (for Plus users). “FDEs should increasingly leave behind operating agents, not just documents.” (ChatGPT) Claude Cowork and Claude Chat now share memory #ForNow. A step towards integrating the two modes, and I predict ChatGPT will do the same (or similar) in September. Agentic Shopping is Complicated and Contingent. An agent shopped for a fitness watch among (A) Garmin Forerunner 55 (B) Fitbit Inspire 3 (C) WHOOP 5.0. When tool calls provided 1 review at a time, it picked the Fitbit a bit more. When all reviews were provided together, it picked the Fitbit a lot more. Like going from 6% to 53% (GPT-5.5) or 46% to 93% (Gemini 3.5 Flash)! Guess it was able to compare better in one tool call. Might be worth benchmarking if providing comparables in a single tool call is good for most models. Gemini Gemini-3.5 Transcribe is out and costs $2 / MTok - roughly 4x the gemini-3-flash-preview cost of $0.5 #ForNow. I won’t be upgrading until the latter is deprecated. Agents that automate tasks best don’t necessarily augment (i.e. help people) best #ForNow. Having separate, clear, benchmarks could help. CentaurBench The load-bearing vocabulary of Claude lists words that have become much more (and less) common in PRs. This was a useful source for me to update my writing style skill to avoid LLM smells. Questions I was asked Week ending 06 Sep 2026 ...

How I Verify And Delegate to AI

Update (Nov 2026): I’ve expanded this into 52 Ways I Specify and Verify Agents, based on over 11,000 prompts. Explore the interactive page with 30 specification and 22 verification techniques and real examples. I delivered a 15-minute keynote at Jio Institute’s Convergence 2026 at NTU on Thursday. The topic was “Data Storytelling” - a bit jarring in the middle of an AI event. Shailesh picked it and I just rolled with it. A spent several days worrying, “How the heck do I say about data storytelling, when most of my recent workshops and talks are about the death of my data storytelling approaches?” ...

Swearing at passwords

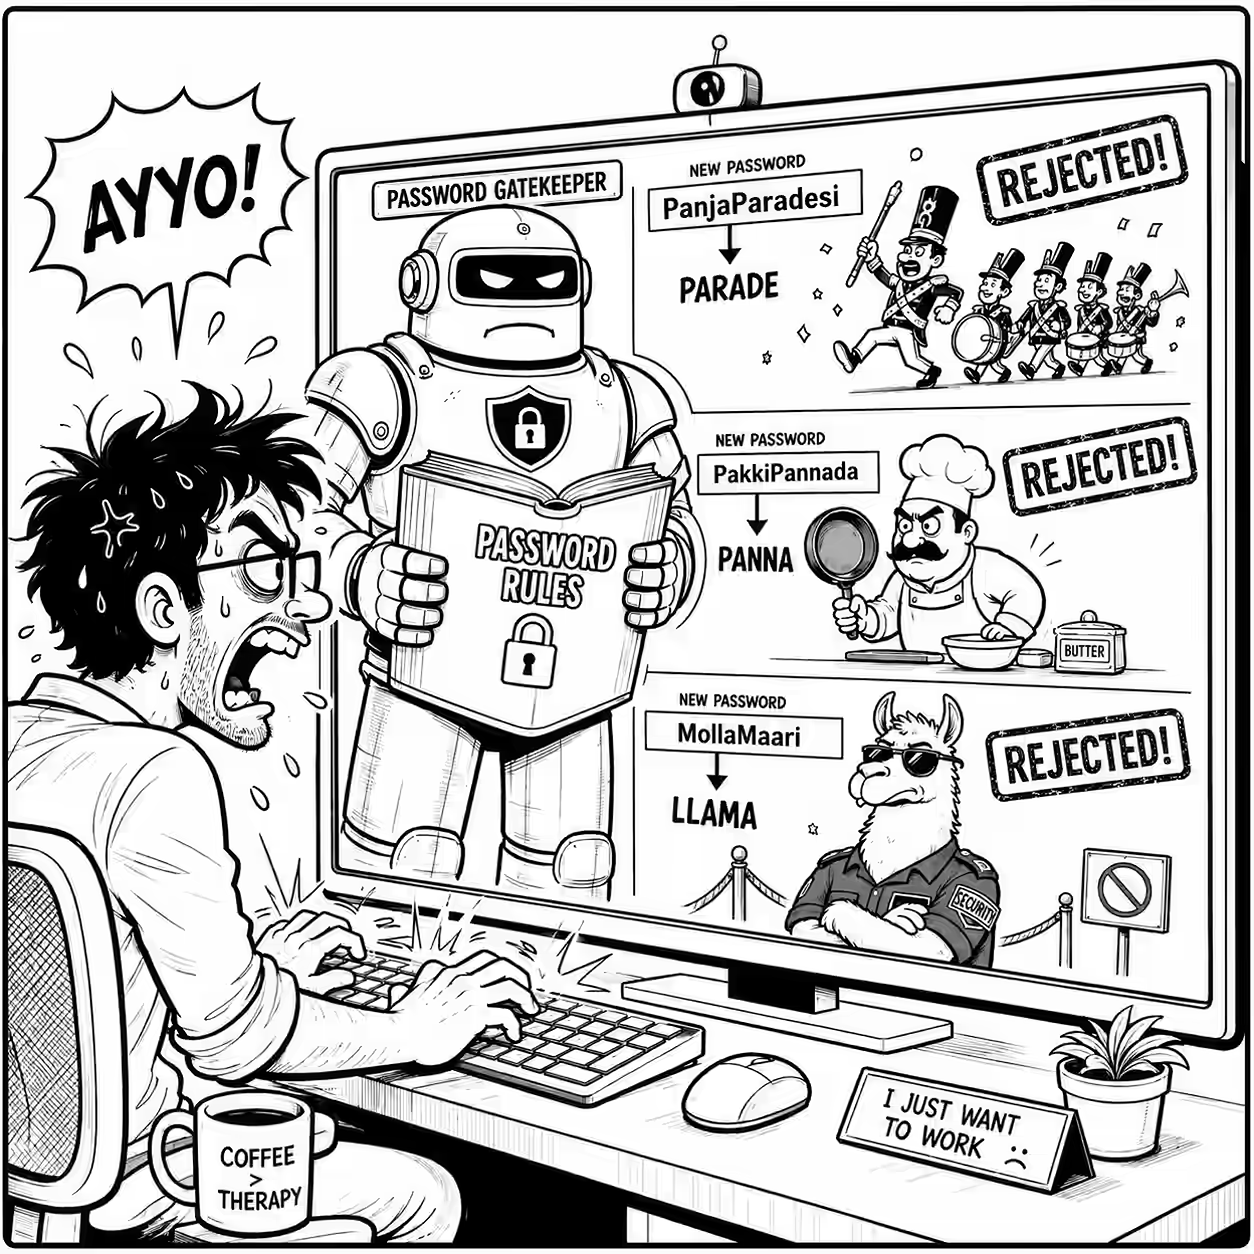
At work, we have to change passwords every 2 months. The password rules are stringent and it typically takes me 10 minutes to find one that works. Here are the rules: The password being setup must have a minimum length of 12 Minimum number of special character to be included in the new password is 1 Must contain at least 1 upper case character(s) Must contain at least 1 lower case character(s) Minimum number of numeric characters to be included in the new password is 1 The construction of the password cannot contain Palindromes. The system has been configured to prevent such passwords The system is configured to not allow the last 24 passwords. A password once setup is valid for 60 days after which it expires. A password once setup must be used for a minimum of 2 days A list of common words has been restricted to be used as passwords. This list is available on the password change page of the self service portal The construction of the password must not contain 5 consecutive characters from the Username or previously used passwords This is so complex. Rules #5 and #8 makes it especially tough. I tried all my standard password strategies: ...

LLM APIs are cheaper than my electricity

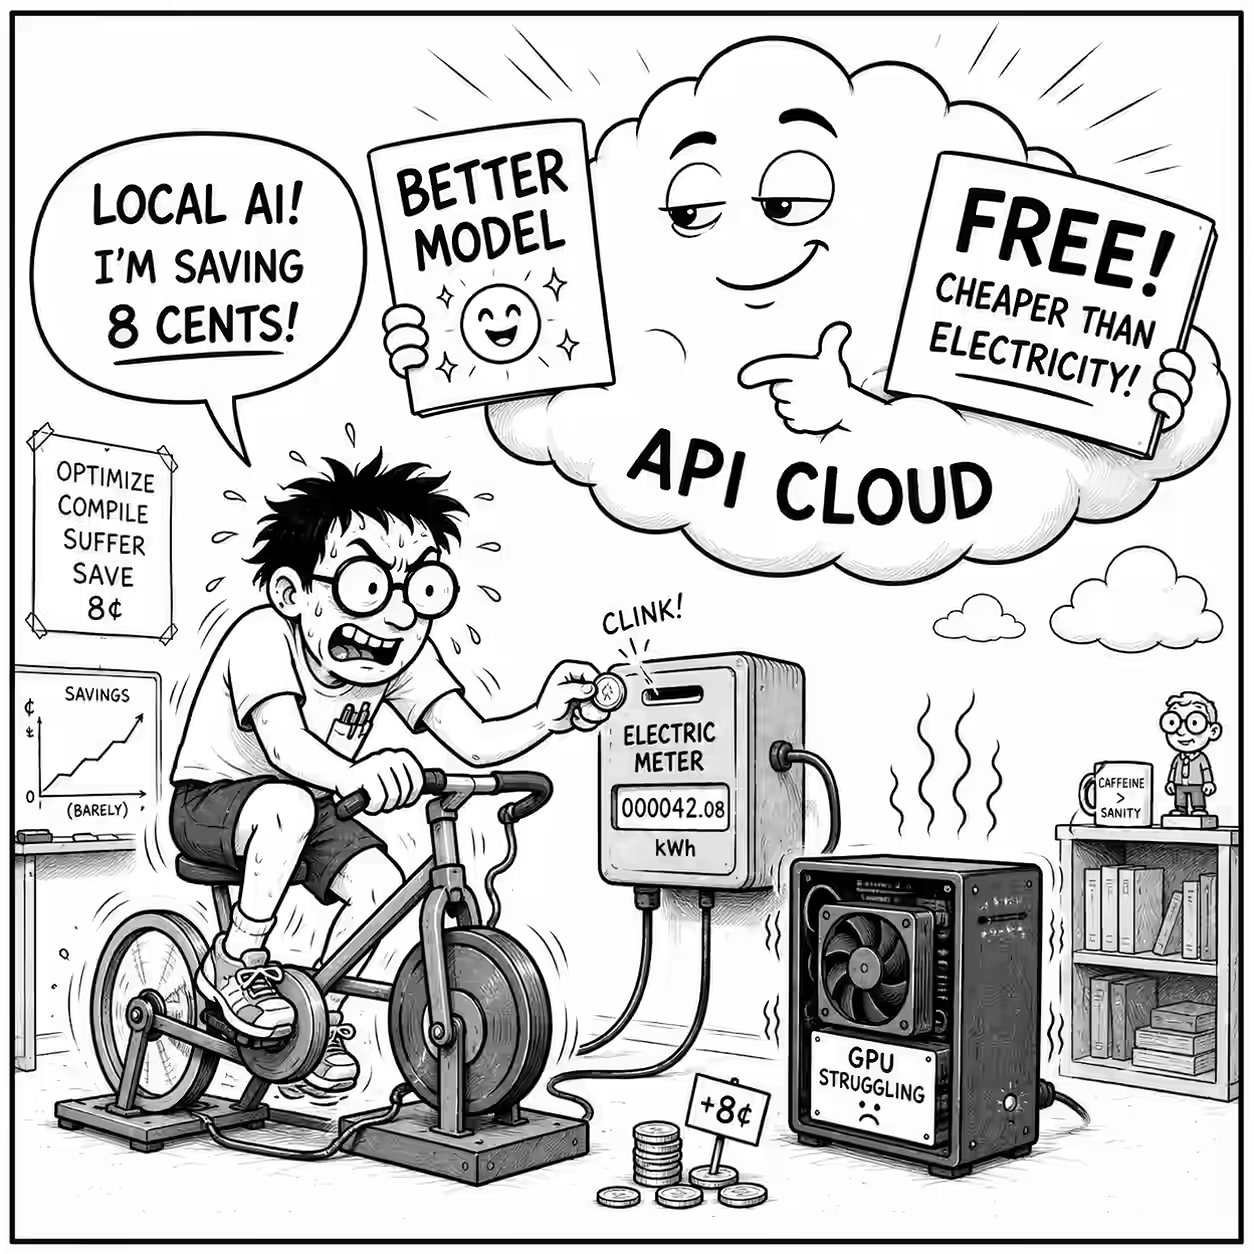
Last week, I saw that local agents are good but slow. Today, I benchmarked the speed and cost. On my NVIDIA RTX 2000 GPU, I can run gemma4:e4b-it-qat at ~60 tokens per second. That seems the best intelligence performance I can get right now. It has an Artificial Analysis intelligence index of ~9 without reasoning and 12 with reasoning. So, if I run it for an hour, it’ll save me the equivalent cost of about 8-12 cents in API calls. ...

Things I Learned - 30 Aug 2026

This week, I learned: I know that fact-checking 2000 page PDFs is error-prone, so’d do it manually for a few pages, then refine. Agents would know this if they’ve tried and failed and added it to their memory systems. So I intervene when agents don’t remember well (increasingly rare) or I think they haven’t seen it before (again, increasingly rare). My prompts guard against these - but I shouldn’t habitualize these - they’ll be needed less in future. rofi - a Linux menu app I use for all kinds of things - makes it hard to take screenshots because it takes over focus and I can’t send the PrtSc or other keys to the screenshot apps. So I use flameshot full --delay 3000 --path ~/Downloads/screenshot.png to take a screenshot (of the last region it used) 3 seconds later, and quickly activate rofi in-between. (The docs say flameshot full captures the full screen. For me, it captured my last region.) ChatGPT can now connect to multiple GMail accounts in paid plans. X AWS to acquire DuckDB. DuckDB is one of my favorite tools today and is improving at a rapid pace. I guess that will continue in the short run - hope it lasts long enough for a worthy successor. I use GoatCounter to track my website traffic. It doesn’t capture domains (only paths), so I just use a code snippet to log https://sanand0.github.io/SITE/... as /@SITE/... - the @ makes it easy for me to see that it’s from a GitHub page. I switched from anydoc to docling as my default PDF to Markdown converter. Docling is even better than AnyDoc #ForNow. Based on my Codex usage, ChatGPT recommended that I not create custom subagents (my setup already used subagents a fair bit last month), but rather, just use default_subagent_model = "gpt-5.6-luna" (which is a remarkably good model for its price #ForNow). Artificial Analysis hosts several useful task-based evaluations. Here are some the fronter leaders #ForNow: GDPVal is good for realistic tasks. Again, GPT 5.6 Luna models have captured most of the low-cost fronter. EnterpriseOps Gym is good for office tasks like emails, calendars, Teams/Drive, support tasks, etc. Interestingly, none of the OpenAI models are on the frontier. Claude Fable 5 and Gemini 3.5 Flash are at the high-end, but Kimi K3 (Max), Qwen3.7 (Max), GLM-5.2 (Max) lead the mid-end and DeepSeek V4 Pro / Flash lead the low-end frontier. TerminalBench 2.1 is good for coding tasks. The OpenAI models completely rule this frontier. Analyst Agent is good for spreadsheet tasks (using Python). Gemini 3.7 Flash seems to be a strong outlier on this frontier. Tau3 is good for navigating unstructured data. GPT 5.6 Luna wins the bottom, DeepSeek V4 the middle, and Qwen 3.8 / GLM 5.3 take the top. Anthropic and Google are not even in the race. Briefcase is good for building useful things from diverse messy data. Grok completely wins the mid-end with Anthropic dominating the high-cost frontier. APEX Agents is good for deeper knowledge work. GPT 5.6 Luna (Max) is a strong frontier outlier here. Task-based benchmarks seem more practical than token-based benchmarks. For example, rather than the LM Arena ELO vs Cost, I would use Terminal Bench 3.0 which clearly tells me to use Codex with GPT-5.6 Sol over Claude Code with Opus 5 / Fable 5; that GLM 5.3 with Claude Code might be excellent value for money as well when using APIs. #ForNow I also did a rough calculation to see if the $18 GLM subscription offers more than $20 ChatGPT Plus. Short answer: No, for my usage, Codex offers ~1.8x more value #ForNow. ChatGPT Anthropic’s Skill Creator Skill now includes evals and A/B testing #ForNow to check if a skill actually does better. I’ve been doing this the hard way, e.g. with impact of simple writing on thinking, optimizing my ideation prompt, optimizing my summarization prompt, etc. I switched from markitdown to anydoc as my default PDF to Markdown converter. AnyDoc handles tables and other kinds of structures in PDF much better #ForNow. Questions I was asked Week ending 30 Aug 2026 ...

My Top 5 Prompts in August 2026

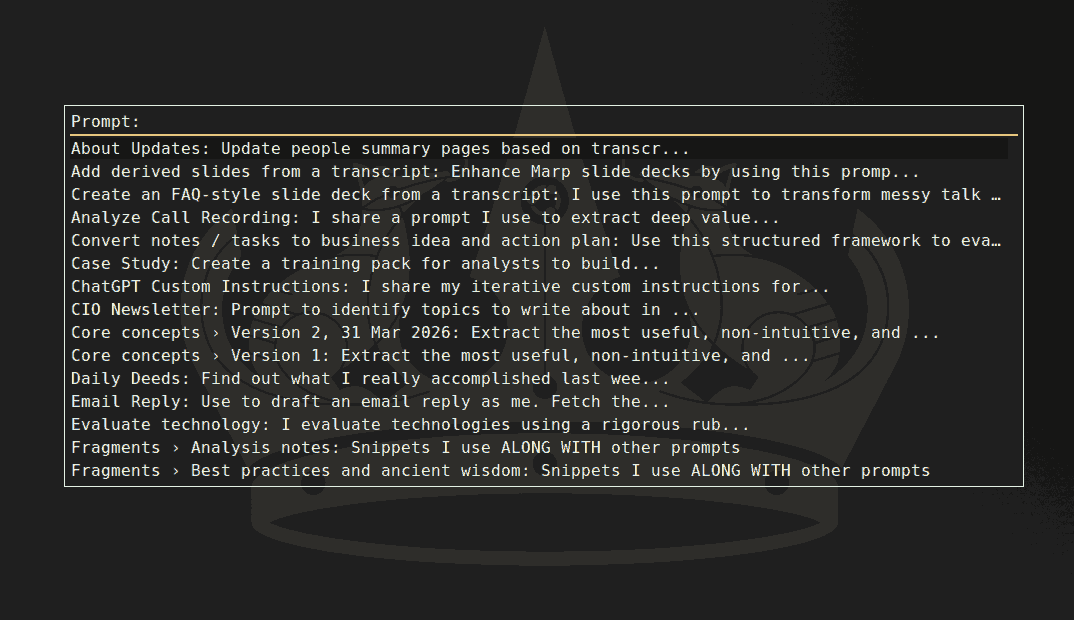
I save prompts and prompt fragments I regularly use with ChatGPT, Claude, etc. (Prompt fragments are just prompts used along with other prompts. They’re typically smaller. But the difference isn’t important or anything… I just use two methods.) I use a script triggered by Ctrl Alt P to select the prompt to paste. This month, the five prompts / fragments I used the most were: #5: Reframe question skill. Sometimes, I’m not sure I’m asking the right question. Actually, I’m not even sure what I’m asking. ...

Things I Learned - 23 Aug 2026

This week, I learned: DuckDB 2.0 adds a CONNECT command that can connect to databases like MySQL, PostgreSQL, etc. making DuckDB the only DB client I need. EQ-Bench evaluates models on capabilities like: does it follow direction, does it challenge you, how good are its insights, does it build rapport, etc. Very interesting to see that the Gemini models are the most “yielding” to your pressure and “validating” your beliefs (Anthropic’s are the least) while OpenAI models are the most “directive” (give concrete actions) #ForNow. There are other benchmarks such as Creative writing which Opus 5, Kimi K3, and GPT-5.6 Sol lead #ForNow. OpenRouter offers several models at a discount. #ForNow, GPT-5.6 Sol is at a 50% discount, DeepSeek v4 Pro at 62%, and Gemini 3.7 Flash at 75% discount. There’s also a Free Models collection that #ForNow includes Nemotron 3 Ultra and more. For a few years, I’ve been feeling useless, that I don’t contribute anything tangible to my organization. No measurable metric I’ve improved. Today, it strikes me that this is a good thing if I don’t want to be fired. As AI eats up more of our work, measurable contributions naturally shrink (AI does more, you do less/different work), and the vague “Oh, he’s probably doing some good” is a safer bet than “He contributed 10% to this metric last year, this year it’s 1%, can we justify his cost?” (I’m sure marketers will come up with a good term to cover this feeling of uselessness that is actually a good thing.) ChatGPT Desktop - Work is a layer on top of Codex #ForNow (which I sort-of expected, but the session logs confirm this). It adds instructions that cover: Memory: from memory_summary.md, MEMORY.md, rollout summaries, and saved skill notes. Recheck decaying ones, mention if unverified. Folders: Temo work in work/, final in outputs/, local files use absolute paths. Coordination: How to start, fork, inspect, message, wait for, rename, … Codex tasks, how to use subagents. Automations: Available tools for reminders, schedules, monitors, follow-ups, and wake-ups. Knowledge management: known project → memory; specialist task → skill; external object → connector; subtask → subagent; recurring work → automation; finished artifact → Work UI primitive. Presentation: Use shell/scripts internally but hide it, describe outcomes in user terms. Apps/Connectors: Gmail, Drive, GitHub, Dropbox, etc. Skills: via SKILL.md Neither ChatGPT Work nor Claude Work can read the ChatGPT / Claude chat conversations. But the chat conversations can access past conversations via “Memory”. That’s a pity, and one of the reasons I’m more often on “chat” than on “work” - it can refer to my past chats automatically, which helps build a kind of unstructured knowledge base. The other reason is that, at least on ChatGPT, chat does not consume usage limits #ForNow. ChatGPT work and Claude - both chat and work - consume usage limits. Weird that there’s a “make a lot of money” button and nobody’s pressing it (take your SaaS, make it headless, let agents use it, charge per interaction esp for enterprises). Thariq AI is accelerating discoveries in cyber (definitely) and maths (reasonably) but not as much in algorithms. METR “Match your prompt style to the desired output.” Clear guidance from Anthropic that “The formatting style used in your prompt may influence Claude’s response style.” OpenAI says something similar - adapting implicitly to the user’s tone. But this is not a very strong signal - examples are better guides. Why model routing must be in the harness. Makes perfect sense. “Only the harness can judge when a model switch is worth the cache miss.” I’m sure some popular harness (like OpenCode, Codex, Claude Code) will enable an “auto model” mode that’ll pick and change the model by itself by the end of the year. Microsoft Print to PDF can, sometimes, generate PDFs with no highlightable or selectable text - all fonts get converted to paths. A crude solution is below. This is a poor solution but often good enough for an LLM to process. (Of course, if you’re passing it to an agent, you could just upload the file and it’ll figure it out.) sudo apt install ocrmypdf tesseract-ocr ocrmypdf --output-type pdf input.pdf ocr.pdf pdftotext ocr.pdf - When my train neighbor started talking to me (asking personal questions but was self-aware, rambling but was partly interesting), I asked if he was an extrovert. He said “No”. People who talk a lot can still be introverts if they’re: socially competent (like me at work) in “performance mode” (like me when I’m on stage) are high energy and engaged by topics (maybe him - or me when, like now, when I just HAVE to tell the flight attendant Ollama + Gemma 4 + Pi answering a psychology question is a delight!) ambiverts (maybe him) not self-aware and are mistaken (maybe him) ffmpeg can embed subtitles. ffmpeg -i video.webm -i subtitles.srt -map 0:v -map 0:a? -map 1:0 -c:v copy -c:a copy -c:s srt -metadata:s:s:0 language=eng -metadata:s:s:0 title="English" -disposition:s:0 default output.mkv adds subtitles.srt to video.webm and creates output.mkv with embedded subtitles. Note: On VLC, MKV works better than WEBM if you want to embed subtitles. On the browser, you need to use the <video> tag with a <track> tag to display subtitles. ffmpeg can burn subtitles. ffmpeg -i video.webm -vf "subtitles=subtitles.srt" -c:v libvpx-vp9 -crf 30 -b:v 0 -c:a copy output.webm re-encodes the video with subtitles added to the video. ffmpeg can offset subtitles. For example: ffmpeg -itsoffset 10 -i input.srt -c copy output.srt creates output.srt with subtitles starting 10 seconds later than input.srt. When I hear my father’s tales from his childhood, I’m struck by how much India moved forward in half a century on child mortality, consumerism, and communication (mobiles). Also surprising are what feels the same: legal system, travel (trains made it easy), food (tasted better, then), entertainment (theatres made it easy), gardening, education (scholarships made international study more accessible than I thought), I asked ChatGPT how I adapt my message based on the audience. It discovered that I tailor messages to the audience’s (A) Objectives (B) Examples (C) Expertise - e.g. tell vs ask (D) Risk appetite. But what’s distinctive is that I often surrender, i.e. I don’t defend my view, but drop it and run with their framing. “People with taste are picky. The only way to make money is by satisfying those who can’t discern quality.” Adrian Hanft. I’ve been telling people that taste is our differentiator against AI. And yes, it’s a fickle differentiator. I mean, how do you build a taste that thousands or millions will adopt? Or… is taste marketed more often than organically adopted, in which case, persuasiveness matters more than taste? But either way, unless most people disagree with you, you’re building conformity, not taste. On a flight, I tried ollama launch pi --model gemma4:e4b-it-qat. It’s a reasonably sensible model. Power consumption is high, though. I was at about 8 watts with ~7 hours of battery life. While running, power spiked to ~50W (1.5h) and settled down to ~12W (4h) when idle. The llama-server process consumes some CPU/GPU even when idle, but I couldn’t get it back to the ~8W even after ollama stop. (It eventually did return to 8W after an hour. Not sure why.) When I tried again on 21 Aug, it went up from 8W (8h life) to 28W (3h life) and back to 8W, so looks like when idle, it doesn’t consume power. I look forward to using local LLMs more! Pain is good. Struggle is good. Stretch is good. Not new. But worth reminding, worth seeking. T3 Code is a coding agent orchestrator. It lets you “remote control” multiple coding agent sessions across systems. The ecosystem of tools around coding agents is growing. Observability, e.g. AgentsView, is one such area. Questions I was asked Week ending 23 Aug 2026 ...
You Don't Even Need to Code

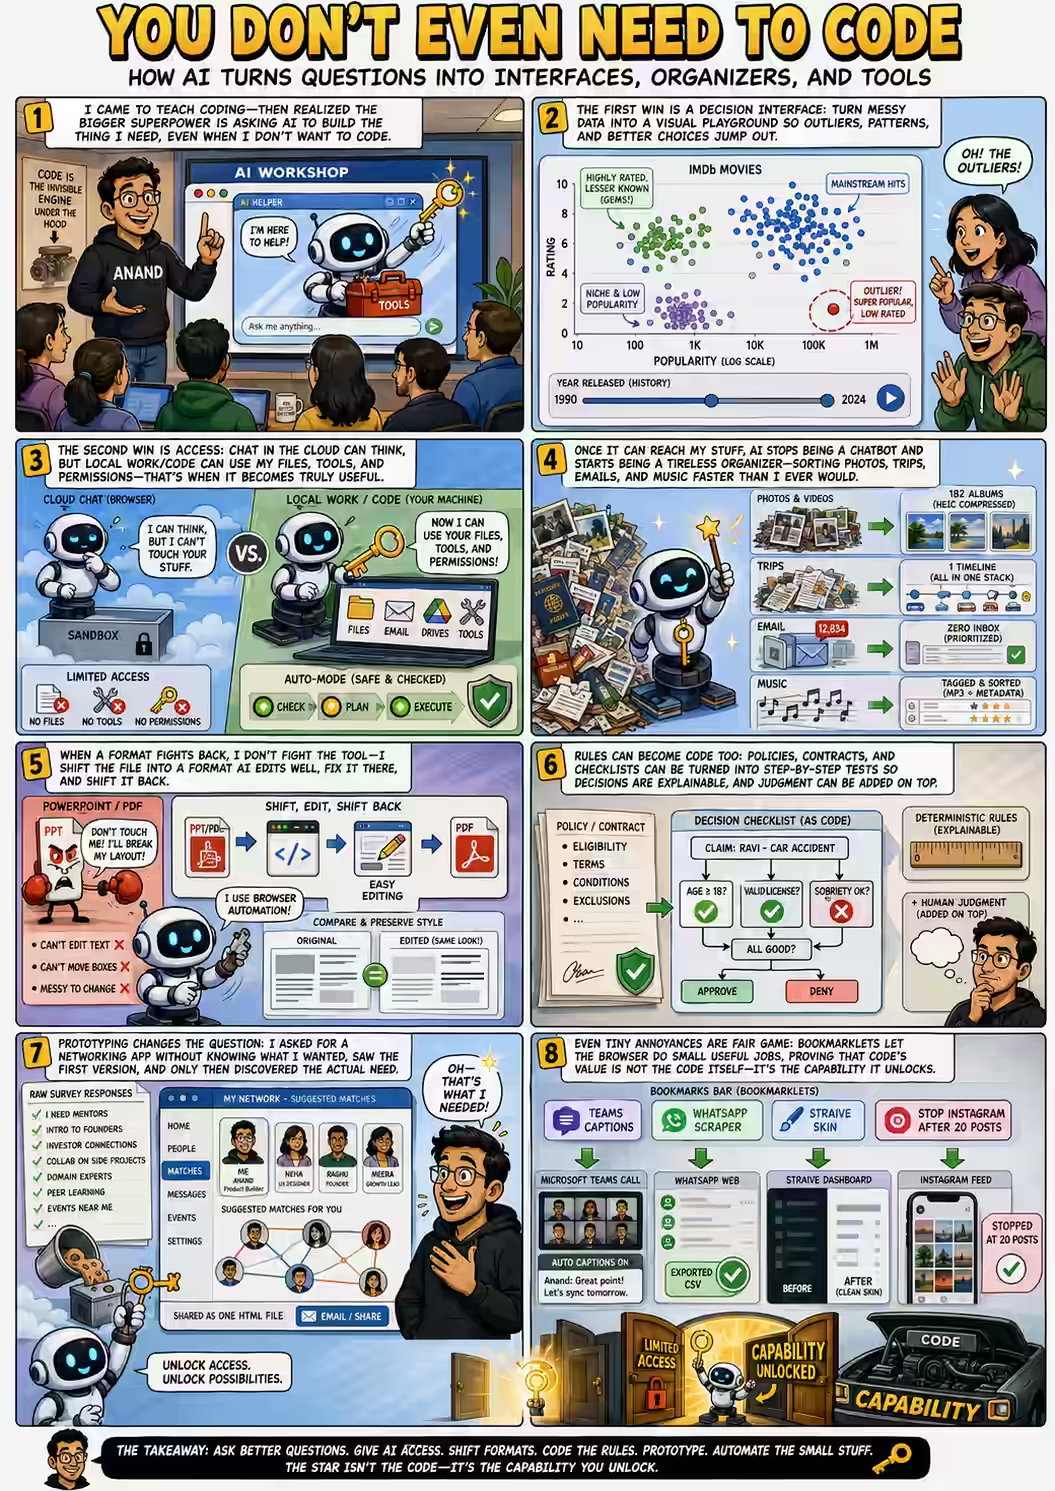
I conducted a session on Sat, 22 Aug 2026 at IIM Alumni Singapore — AI Unboxed (4/4) - Singapore / Teams. Summary: Coding is becoming specification and review: describe the outcome, let agents build it, and focus on whether the result works. Here’s the link to the session Links: Room Map Video (129 min) Transcript Audio (129 min)

What to do less because of AI

Some ideas on what we can do less, thanks to AI. Why? Because less is more and we keep getting advice on what to do more of, not what to do less of. Skip meetings you don’t speak in. Agents can summarize the transcript. Stop taking notes. Agents can summarize a recording. Stop reading group chats. Agents can summarize WhatsApp groups, Hacker News, Twitter, and more. Stop translations. Agents translate on the fly. For you, and your audience. Stop weekly status reports. Agents can tell you (and your manager and team) the status. Stop building dashboards. Agents tell you “what’s wrong” or “what’s next” directly. Stop building software at first. Tell the agent to do the work. Let it write software if needed. Save it if you use it often. Stop writing requirements. Agents can prototype. Test if that’s what you need, first. Stop teaching coding. Agents can code. Teach people to use agents. Also - a few things that were true pre-AI: ...

Local agents are good but slow

Last year, I shared how local LLMs are expensive. There are only 3 reasons to use them over an inference API: You have no choice, e.g. Government, pharma, finance, or other sensitive data. You have free GPUs, e.g. your laptop, local data center with sunk cost, free cloud credits, etc. This doesn’t scale. You want to learn. This year, I finally started using them for a combination of #1 (on flights) and #2 (my 8 GB NVIDIA RTX 2000). ...

What can AI not do

Over the last few weeks, I asked 166 people: What’s something you did not ask AI last week, because it can’t do it? There were 4 groups of responses. 37% said “Reliability”. AI tries but fails often enough. Like: Verify & return exact source of information. Generate accurate images. Completing PDF accessibility reliably according to the WCAG 2.2 standard. Converting 2D interior design to 3D view as vision models are not good keeping things as per scale. Create a user manual based on my codebase. I have asked this before and it has failed. 27% spoke about “Reach”. AI can’t access tools, data, or do something. ...

Pleasures of a bus ride

There are some small pleasures in life, not worth mentioning by themselves, but sometimes they come together so well. Like: Google Pay popping up a “Disable verification for transit?” option, so I just touch my phone to the bus ticket reader even while on a call and it just works like my card. (It works even without Internet!) Finding a seat at the front of the double-decker bus on top, so I can take in the entire vista from a height for the entire one hour ride Discovering the ultra-configurable Open Camera app (thanks to Thej) and capturing at the much smaller 640x480 resolution at 10x speed Transferring it like a breeze to my laptop with LocalSend Compressing it into an ultra-small 1.4MB video thanks to the AV1 codec and FFmpeg Publishing it to Cloudflare within a second thanks to ultra-fast WiFi Watch the video Yeah… this is life!

Watching videos with a phone case

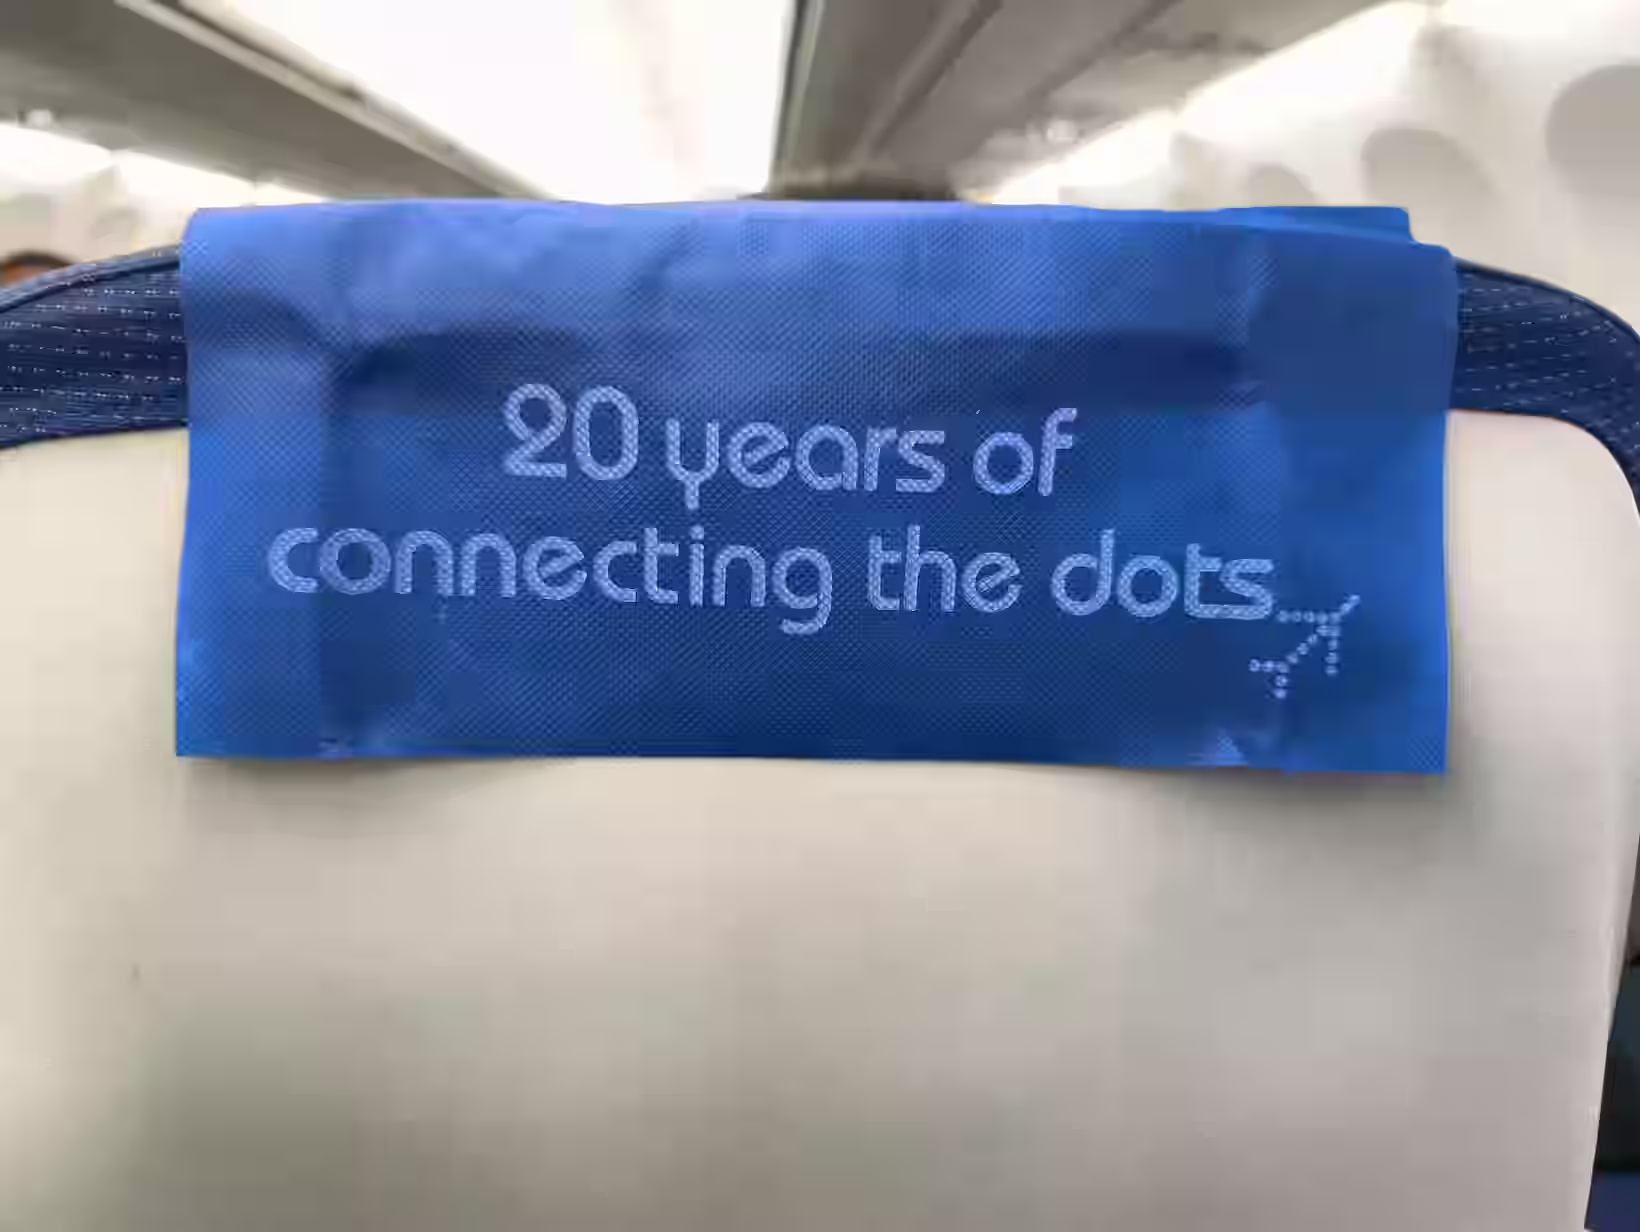
Two months ago, I was impressed at the ingenuity of a lady who used a plastic cover to watch videos on a flight. Today, on the same Indigo flight from Singapore to Chennai, I saw a man one seat ahead of me use the headrest cover on the seat in front to watch videos. (The headrest cover is the cloth behind your head on airline seats. It saves cleaning effort.) ...

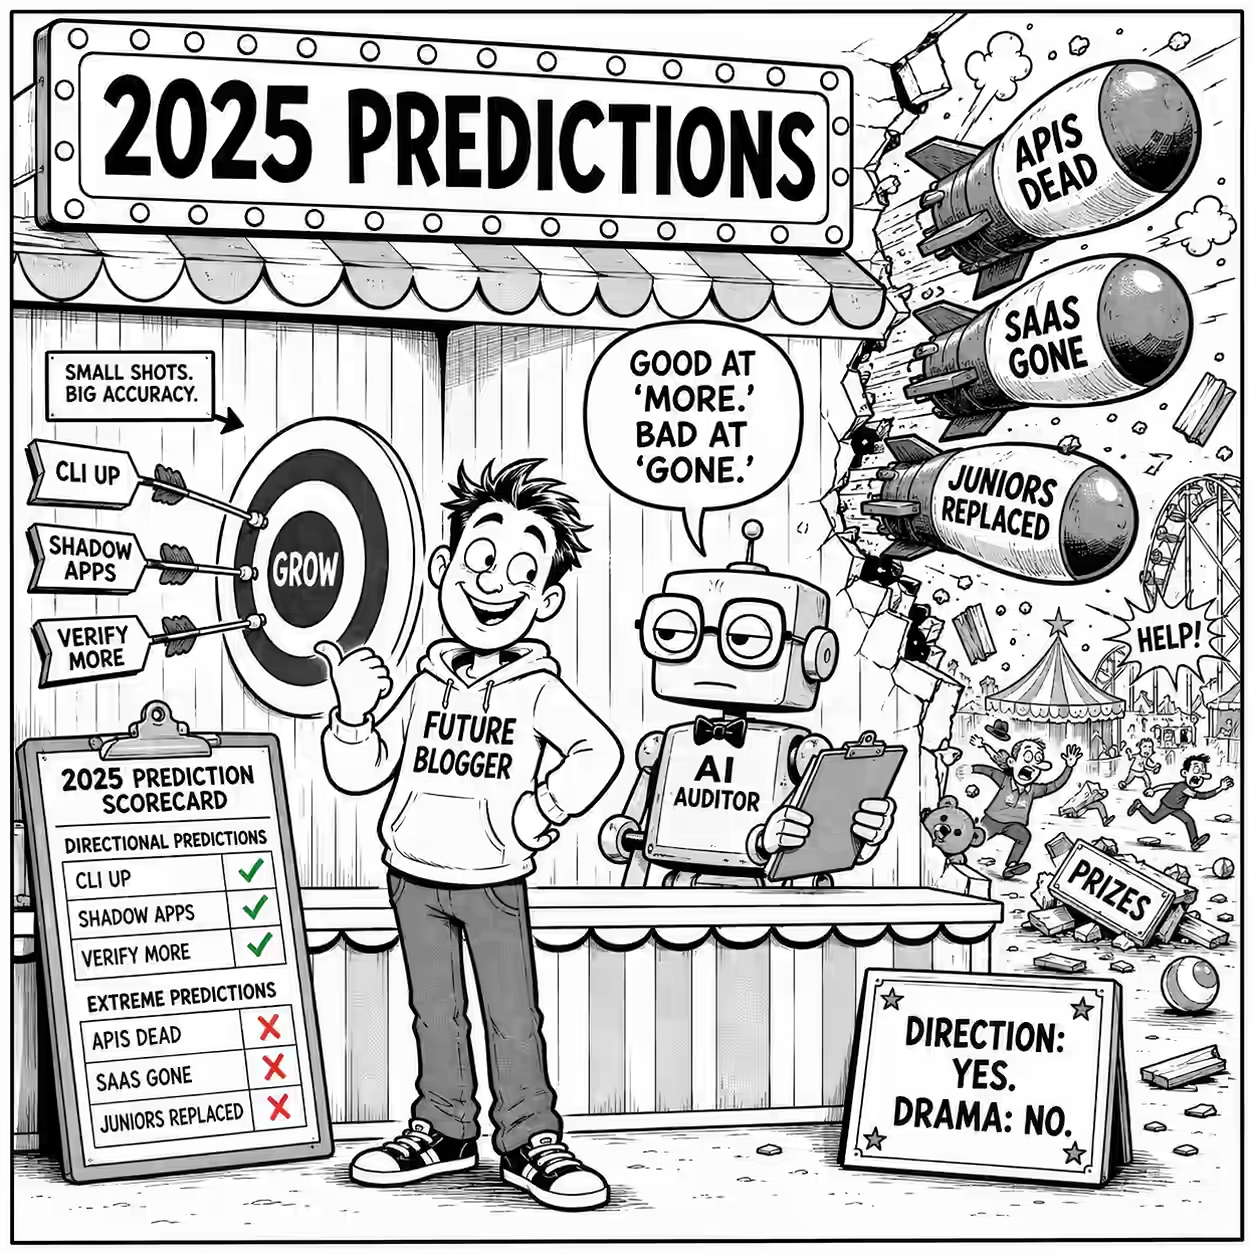
My predictions in 2025

In 2025, I made a number of predictions on this blog. (Not intentionally. I just said stuff.) I asked ChatGPT to audit them. It selected 440 claims, filtered out vague or pending ones, and verified the rest. Here’s what I got right and wrong. 🟢 “My chat will overtake search in 12-18 months. When ChatGPT becomes my primary lens on knowledge…” (chatgpt-vs-google-usage.md:L27). Audit: This actually happened in your own browsing data: search led through April 2026; in May, chat jumped to 2,211 visits vs 1,319 search visits, and stayed comfortably ahead thereafter. 🟢 “Typed languages are better suited for vibe coding. This will likely lead to the growth of typed languages (TypeScript, Rust, Go) but also of typing in untyped languages (e.g. Python).” (things-i-learned-10-aug-2025.md:L33). Audit: TypeScript became GitHub’s #1 language in August 2025 and grew 66% YoY; GitHub itself explicitly connects the rise of typed languages to more reliable AI-assisted coding. This is unusually strong because you got both the direction and mechanism. (The GitHub Blog) 🟢 “Code Mode … is a smart way to use MCPs and a very likely future direction. Using LLMs to write code to call MCPs rather than directly.” (things-i-learned-05-oct-2025.md:L49). Audit: OpenAI’s current Responses API has essentially this as a named capability: Programmatic Tool Calling lets a model write and execute programs that coordinate multiple tools and intermediate results. (OpenAI) 🟢 “CLI optimization for LLMs will likely emerge. More CLIs (and wrappers / hooks in the shell) will improve output and error contexts for LLMs…” (things-i-learned-27-jul-2025.md:L86). Audit: By May 2026 you were yourself testing rtk, a CLI proxy explicitly producing compact agent-friendly command output; across 216 commands you measured about 50% token reduction. That is almost exactly the wrapper you predicted. 🟢 “In the future, AI that works directly with file systems, Model Context Protocols, and local APIs are likely to become more important.” (features-actually-used-in-an-llm-playground.md:L76). Audit: File-system-native coding agents became mainstream, while MCP expanded into both hosted and local integrations; Anthropic now packages local MCP servers as easy-to-install desktop extensions. (Claude Help Center) 🟢 “Agents are slow. Parallelizable tools … will grow. Tool speed … will become more important.” (things-i-learned-22-jun-2025.md:L106). Audit: Parallelism has become a central agent UX: OpenAI’s Codex app is explicitly built around managing multiple agents simultaneously; at the extreme, internal users now accumulate more than 60 hours of agent turns per day by parallel execution. (OpenAI) 🟢 “Companies-of-one will grow. Sole founder can handle support functions.” (things-i-learned-24-aug-2025.md:L14). Audit: Nasdaq’s Economic Institute finds one-person US business applications up more than 20% since early 2025, with essentially all recent application growth coming from solo businesses. Stripe separately reports solo founders reaching 63% of Atlas C-corps in Q2 2026. (Nasdaq) 🟢 “We will move towards an organization structure where developers are embedded with business teams rather than working as a separate group. Sort of like embedded executive assistance instead of a central typing pool.” (things-i-learned-08-jun-2025.md:L49). Audit: Forward-deployed engineer demand reportedly increased 42-fold from 2023-25, with roughly 9,000 roles globally by early 2026. The role is almost precisely “technical people embedded with the business to make AI work in its real environment.” (Reuters) 🟢 “Shadow apps will grow. Anyone can code. Users build apps with prompts, sheets, agents, outside of IT SDLC. Like Excel sheets.” (things-i-learned-24-aug-2025.md:L18). Audit: Microsoft now explicitly describes a “new wave of shadow AI”: users installing coding/desktop/SaaS agents outside traditional IT governance, and has built discovery products specifically for unmanaged AI applications and agents. (Microsoft) 🟡 “Agents generate diffs/PRs. Tools to edit and comment on these online will emerge.” (things-i-learned-22-jun-2025.md:L107). Audit: GitHub now measures PRs created and merged by Copilot coding agent, while review comments can be handed directly to the agent with “Fix with Copilot,” including batches of review feedback. That’s almost verbatim fulfillment. (The GitHub Blog) 🟡 “Models’ ability to orchestrate longer workflows will improve. Factor that into your application design.” (things-i-learned-10-aug-2025.md:L44). Audit: By mid-2026, OpenAI reports large increases in requests corresponding to >30-minute, >1-hour and even >8-hour human tasks, while Codex explicitly targets long-running tasks spanning hours or longer. (OpenAI) 🟡 “Code review process will be re-invented.” (things-i-learned-22-jun-2025.md:L109). Audit: GitHub has rebuilt Copilot review around an agentic architecture that gathers broader repository context, uses tools, produces findings, and can hand fixes to another coding agent. This is substantially more than autocomplete added to old review. (The GitHub Blog) 🟡 “Domain expertise will therefore become even more valuable in the near future.” (things-i-learned-20-apr-2025.md:L39). Audit: 2026 hiring evidence points toward domain/product expertise becoming more important rather than pure coding alone, particularly as AI handles more implementation and firms need people who can connect it to actual business functions. (Reuters) 🟡 “Validation is the New Bottleneck: Since coding is now much faster, the critical, time-consuming task has shifted to reviewing, testing, and validating the LLM’s output.” (things-i-learned-17-aug-2025.md:L90); you also predicted “The Quality Control (QC) function will become larger and more critical” (L95). Audit: GitHub has now productized exactly that bottleneck in Code Quality; more than 10,000 enterprises used its preview, and GitHub explicitly frames AI-accelerated code output as creating the need for trustworthy pre-merge quality validation. (The GitHub Blog) 🟡 “Agents generate technical debt faster than humans. Solving this will become a major problem/opportunity.” (things-i-learned-22-jun-2025.md:L114). Audit: GitHub’s 2026 Code Quality launch is close to a commercial instantiation of this forecast: AI increases code output, so automated quality/debt detection and remediation moves earlier into the development cycle. (The GitHub Blog) 🟡 “Governance will grow. Non-experts are acting like experts. Validation is more important.” (things-i-learned-24-aug-2025.md:L19). Audit: The companion to shadow AI has indeed been governance: Microsoft now ships specific discovery, monitoring and governance for unmanaged AI agents, while NIST has continued expanding formal GenAI evaluation tooling. (Microsoft Learn) 🟡 “Soon, we won’t just follow a lesson plan – we’ll have lessons built just for us. AI will track how we learn and adapt in real time. It’ll feel like having a personal coach in your back pocket.” (o3-is-now-my-personalized-learning-coach.md:L91). Audit: ChatGPT Study Mode now asks what the learner knows, adapts explanations, checks understanding, works from uploaded course material, and uses memory to personalize support; OpenAI explicitly describes the objective as personalized learning support available to any student. (OpenAI Help Center) 🟡 “Cost is going down so quickly right now that all you have to do is wait, and stuff will become available for a very affordable or even a free price.” (things-i-learned-16-mar-2025.md:L116). Audit: The broad direction held. OpenAI cut GPT-5.6 Luna API prices by 80% in July 2026 while simultaneously improving capability-per-dollar. The “all you have to do” part is hyperbole, but the price-curve forecast was right. (OpenAI) 🟡 relayed: “Control of chips and GPU compute is what will likely be the gameplay to control AI dominance globally.” (things-i-learned-02-feb-2025.md:L16, attributed there to Dario Amodei). Audit: Advanced-AI-chip export licensing remains an explicit geopolitical control mechanism in 2026, including restrictions and license review for H200/MI325X-class accelerators going to China. 🔴 “AI closes the gap between junior & senior devs – even when both use AI. Quality doesn’t suffer much. So onboarding can be faster, compensation ladder may shorten.” (things-i-learned-03-aug-2025.md:L52). Audit: The emerging evidence says AI changes the work but does not erase the expertise gap: experienced developers are better at steering/delegation, while low-experience AI-heavy contributions incur substantially more review and lower acceptance. (arXiv) 🔴 “LLMs already deliver hours of analyst work in minutes. Entry-level roles WILL vanish.” (goodbye-mba-hello-ai.md:L17). Audit: The labor-market warning was directionally good, but “vanish” is a major magnitude error. Stanford finds a meaningful relative decline among 22-25-year-olds in highly AI-exposed jobs, while employment remains substantial and overall exposure groups still show employment growth. “Entry-level hiring contracts sharply” would have scored much better. (Stanford Digital Economy Lab) 🔴 “Coders micro-manage LLMs. I think a novice will be more efficient and get better results than me.” (how-to-visualize-data-stories-with-ai-lessons.md:L285). Audit: Current empirical work points the other way in real software work. In a 22,953-PR study, lower-experience AI-heavy developers received 4.5* more review comments, had 31% lower acceptance, and took over 5* longer to resolve issues; qualitative work likewise finds experienced developers better at delegation and control. (arXiv) 🔴 relayed: “API access from model providers will shrink. Selling tokens is not a viable business model given lowering costs.” (things-i-learned-23-mar-2025.md:L19, from the Alexander Doria notes immediately above it). Audit: Almost exactly backwards. Model providers expanded their APIs into richer agent platforms, and token-metered API access remains a core commercial model - including premium pay-as-you-go modes. (OpenAI) 🔴 “APIs are likely to be replaced by just chat requests that will do the same thing. APIs might be replaced by RPA, where somebody uses a chatbot to do the equivalence instead.” (things-i-learned-16-mar-2025.md:L111-L112). Audit: Chat did become a front end, but the implementation moved toward more APIs underneath, not fewer: tool APIs, Responses, MCP, computer-use interfaces and programmatic tool calling are now the substrate agents use. (OpenAI) 🔴 “Software companies build ‘SaaS’-like apps today. Agents will replace apps. Instead of UI, workflows, and app logic, they’ll engineer prompts, APIs, and evals.” (agents-will-replace-saas-apps.md:L12). Audit: The interface-shift was right; “replace” was not. Gartner now forecasts agentic AI may expose roughly 20% of SaaS application spending by 2030 - meaning substantial disruption, not app extinction. Agents are often a new interaction layer over systems of record and APIs. (Gartner) 🔴 relayed: Models will “internalis[e] workflows … to wipe out the apps and workflow space.” (things-i-learned-23-mar-2025.md:L17, from Alexander Doria notes). Audit: “Internalize capabilities” was insightful; “wipe out” was the failed extrapolation. Enterprise applications remain a very large substrate even in Gartner’s fairly aggressive agentic-AI forecast. (Gartner) 🔴 “Demand for SaaS (one-size-fits-all) will shrink.” (things-i-learned-06-apr-2025.md:L89). Audit: Not yet. For example, Gartner forecasts Indian SaaS spending growing 18.9% in 2026, from $3.9B to $4.6B. AI is changing SaaS economics and seat licensing, but current demand is still growing rather than shrinking. (Gartner) 🔴 “The early majority have come in… Soon the late majority will come in asking for existing solutions that have already solved their problem for many others.” (things-i-learned-03-aug-2025.md:L44). Audit: This mapped your client/audience experience onto population adoption much too quickly. In 2026, US Census data put business AI usage around 17-20%, nowhere near a conventional late-majority phase. (Census.gov) 🔴- baseline error: “Given the cost and accessibility of drones, I guess drone terrorist attacks will soon emerge.” (things-i-learned-16-nov-2025.md:L43). Audit: They had already emerged. The UK government documented Daesh using small armed remotely piloted aircraft carrying grenades in Iraq in 2017; the UN had already been studying weaponized UAS use by non-state armed groups for terrorism-related purposes before this 2025 post. This is therefore a clean failure to establish the baseline, not a future hit. (GOV.UK) 🔴 relayed: “Personal writing with connection won’t go away. AI can’t give you heartbreak. But the rest of non fiction writing will vanish.” (things-i-learned-30-mar-2025.md:L69, under “Notes from Writing with AI”). Audit: Nonfiction is under real pressure, but “vanish” is nowhere close. UK nonfiction publishing still generated about GBP1.0B in 2025, down only 3%; the wider publishing industry reached record revenue. (Publishers Association) Legend: ...