Hire a Data Scientist for $100

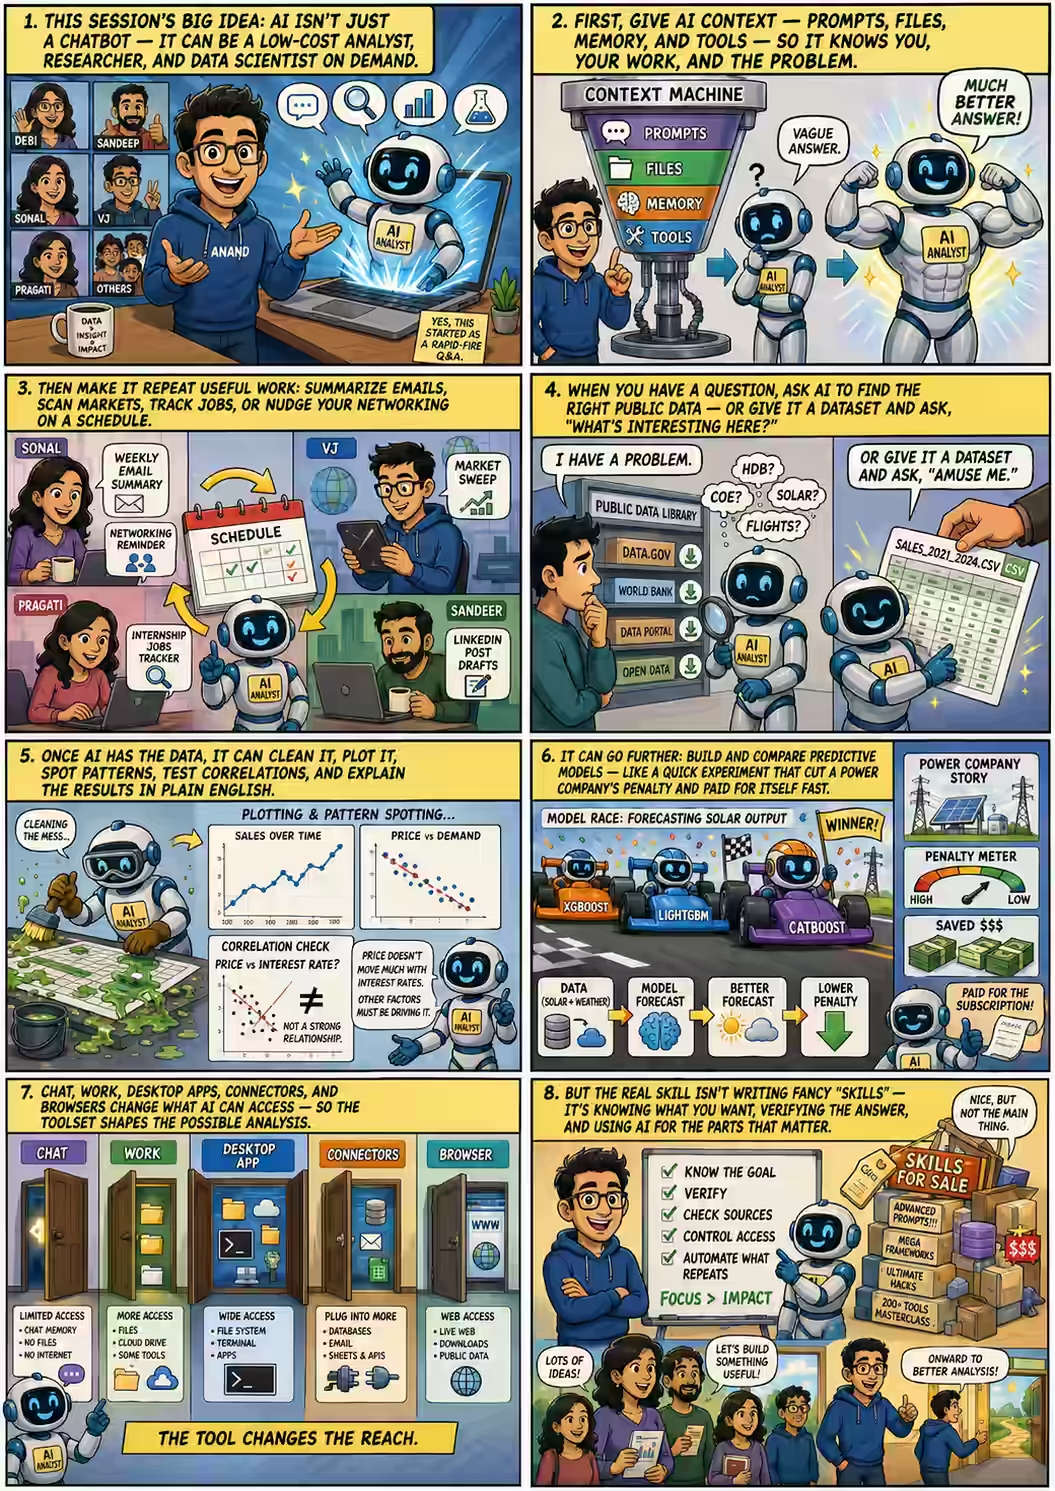
I conducted a session on Sat, 25 Jul 2026 at IIM Alumni Singapore — AI Unboxed (3/4). Summary: Agentic tools can perform much of a data scientist’s research and analysis cheaply. The leverage comes from framing the question and checking the result. Here’s the link to the session Links: Video (138 min) Transcript Audio (138 min)

Data Science for Sustainable Development Goals Book

One of my goals this year is to publish 2 books. One got published. Sort of. Data Science for Sustainable Development Goals: India Case Studies is an open-access anthology and I’m the designated author of Chapter 10: Using Data Analytics to Improve Students’ Performance is about how Gramener worked with NCERT to analyze the National Achievement Survey data, discovering stuff like TV hurts maths but not reading scores, playing helps maths but not reading scores, fathers of West Bengal (not mothers) and mothers of Punjab (not fathers) influence their children’s scores the strongest, and so on. ...

When Data is for Agents - Workshop Summary

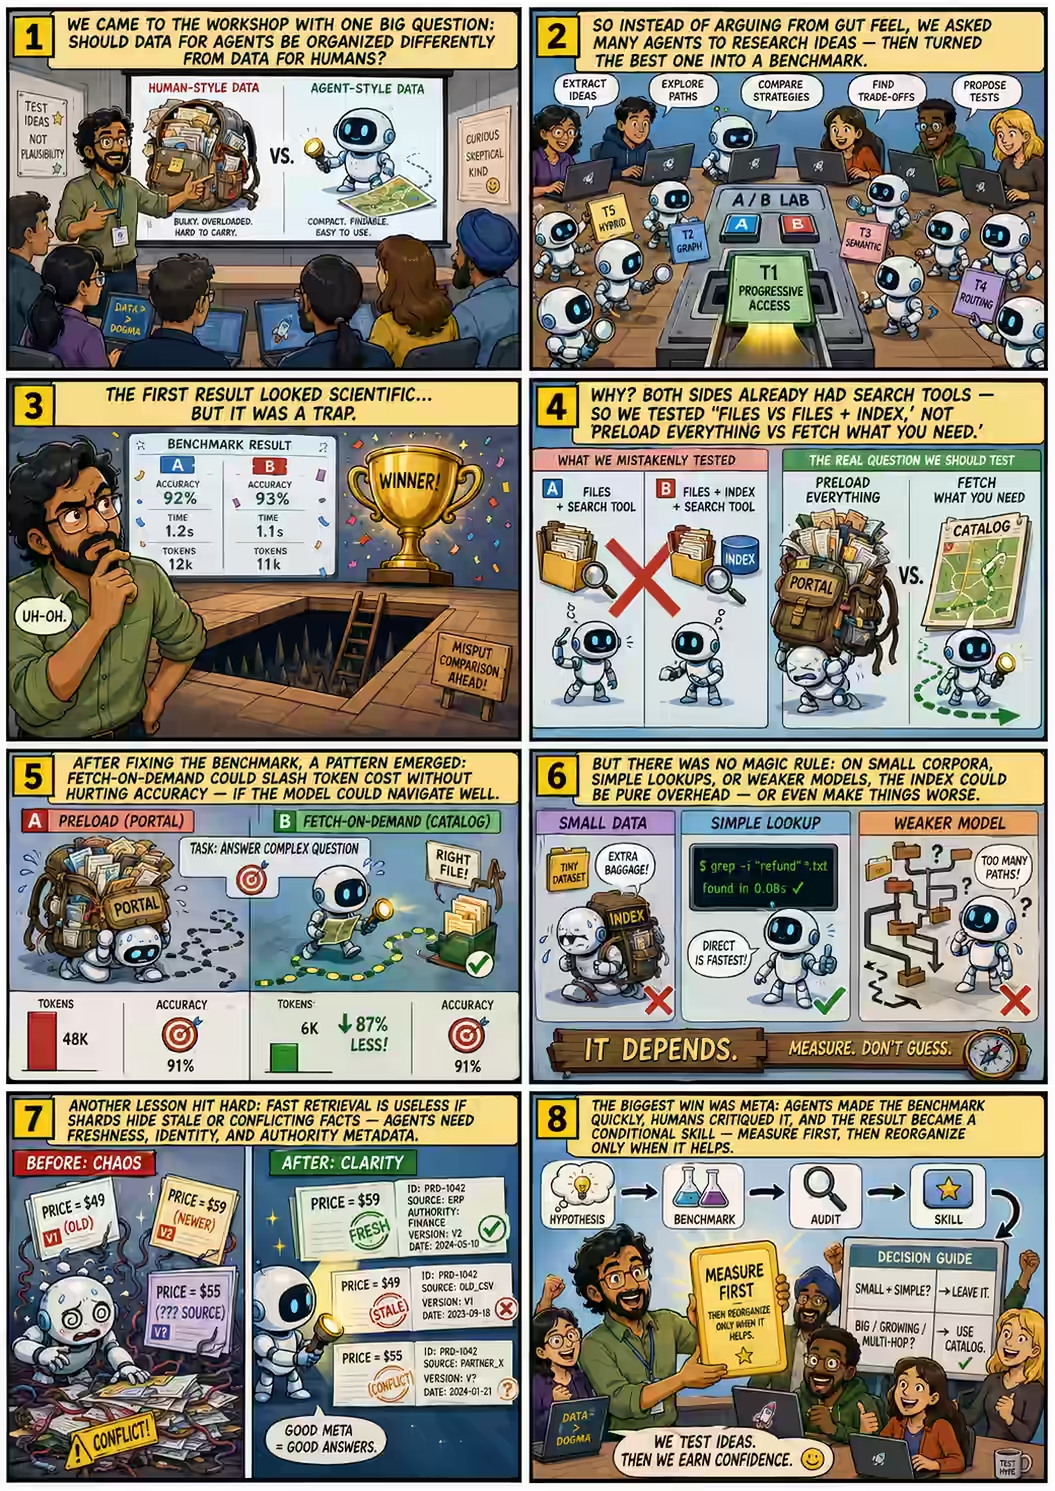
Here’s roughly what I said in my When Data is for Agents workshop for Fifth Elephant on 7 Jul 2026. Or you can read the detailed AI-generated version if you prefer - it has all the prompts, links, results, etc. I think agents prefer data in a different form than humans. But I don’t know. So, everyone, open ChatGPT (or Claude or whatever), research and ask it! Now, let’s collate them and see the result. Aha! Looks like: ...

Free Methods, Priced Judgment

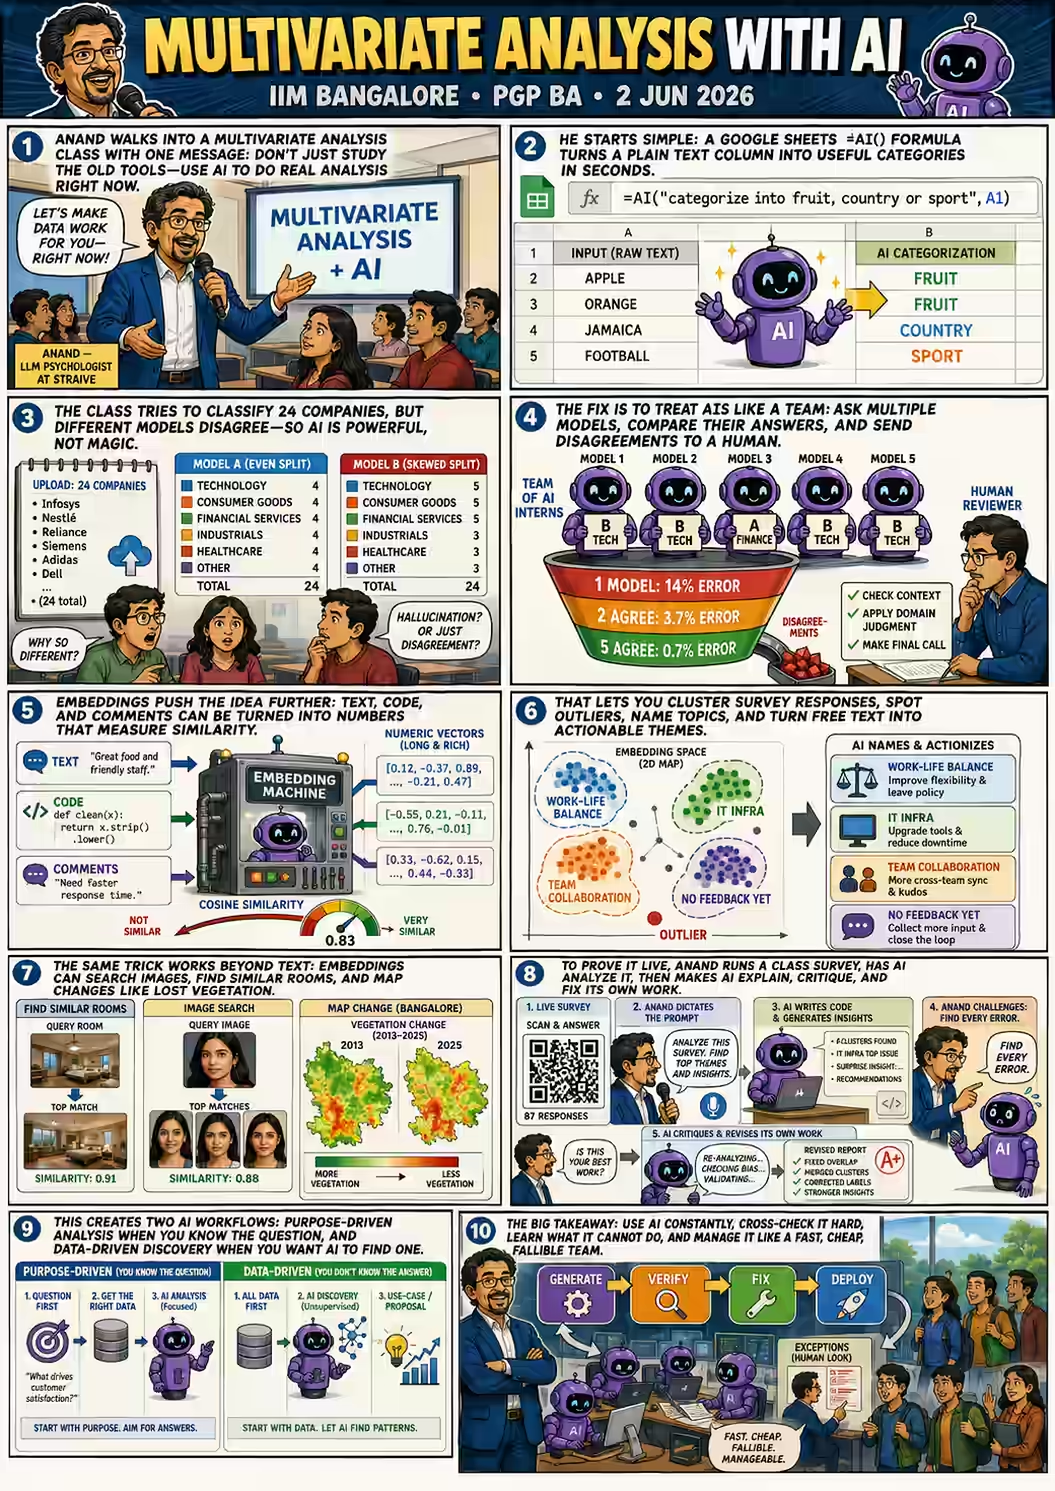
I conducted a session on Thu, 02 Jul 2026 at PGP-BA Multivariate Data Analysis — Term 4 - IIM Bangalore. Summary: AI makes sophisticated analytical methods cheap and accessible. The scarce skill becomes choosing the right analysis, questioning assumptions, and judging whether results matter. Here’s the link to the session Links: Transcript Audio (185 min)

Rainy seasons on schedule

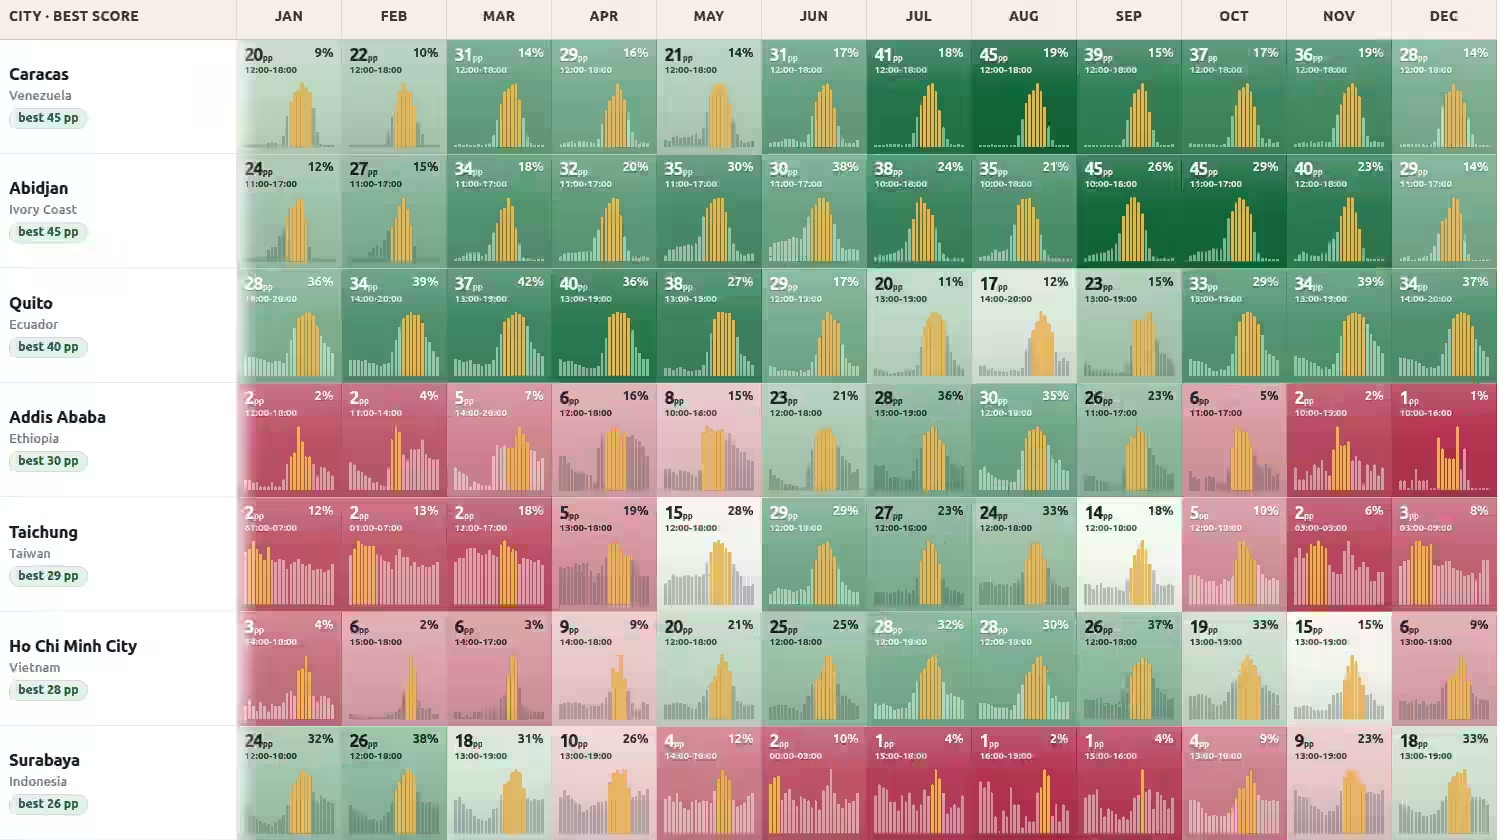
Karthik Sashidhar shared his AI-generated Bangalore weather blog, which is generated by Hermes listening on Telegram. “The data analysis and stuff is still fairly YOLO but … skill based on my 10 years of experience,” as he put it. That includes critique too. Arjun asked it: Does it rain at specific hours in the day during monsoons? In a few minutes, Pre-monsoon rain is an evening creature emerged. In short, it rains in the evenings: 5 - 6 pm is the peak. ...

How IMF mis-forecasts GDP growth

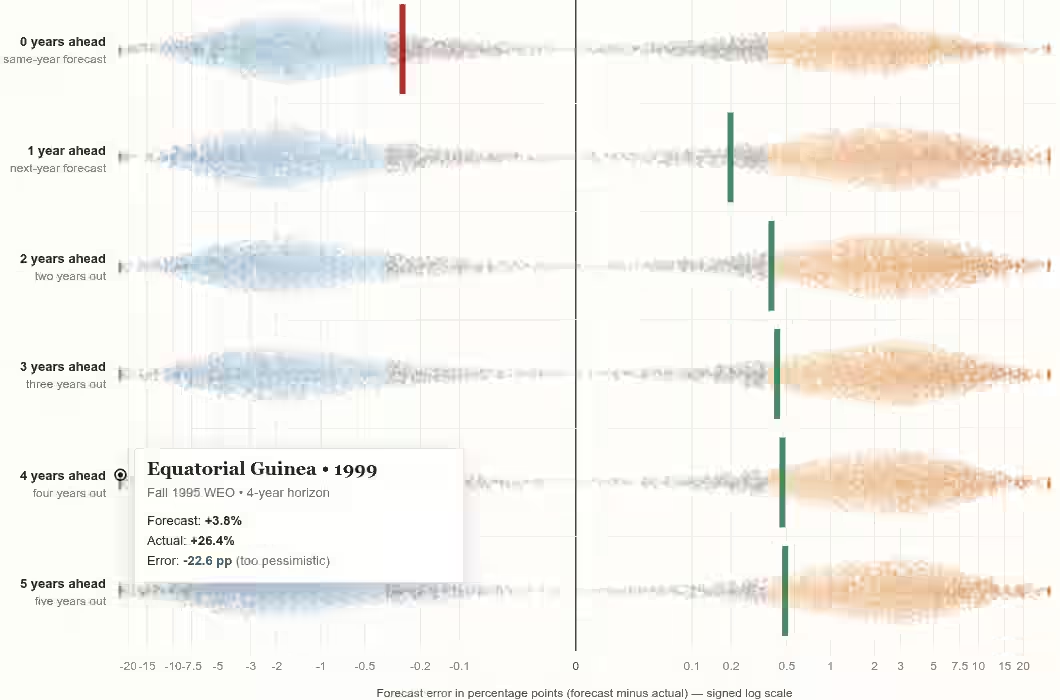
The IMF forecasts GDP growth every year. Their forecasts for the current year are slightly low. Their forecasts for the next year are slightly high. After that, it remains high. Some forecasts, like China, Singapore, UAE, Equatorial Guinea are consistently low. Other forecasts, like Japan, Congo, Mexico, Pakistan are consistently high. The interesting meta-pattern is how this sort of past-forecast analysis can be done for any topic. This emerged from an Ethan Mollick post and then I asked: ...

Wikipidia Citation Impact

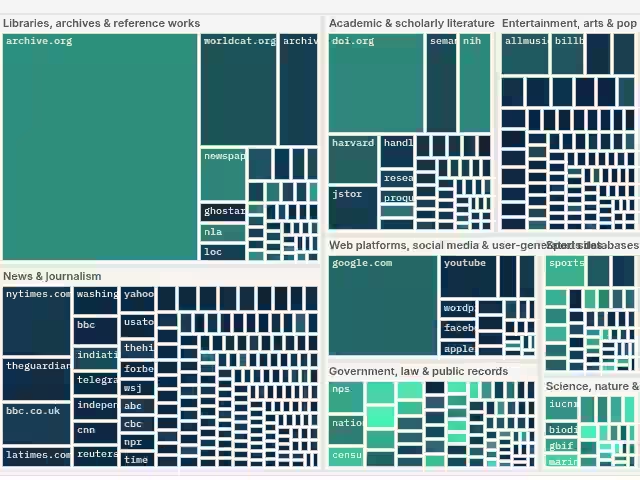
Imagine you’re an information anarchist. You undermine Wikipedia pages by nuking references. A genie has granted you a wish: you can nuke one entire domain. Just one. As a data-driven decision maker (who is also an information anarchist 🤷), which would you pick? A common choice is The Internet Archive. 2.9 million Wikipedia pages reference it. But, you’re sneakier than that. A page isn’t undermined just because some references are gone. It’s undermined when all the references are gone. ...

Longest repeated paragraph on Wikipedia

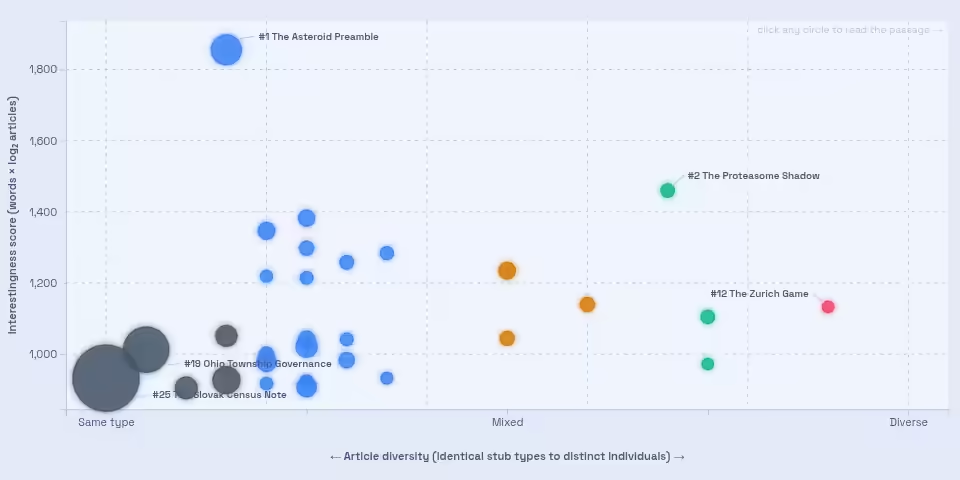
What is the most frequently occurring sentence in Wikipedia? ANS: A 213-word paragraph about how minor planets are named, which appears in 418 Wikipedia articles, word-for-word! There are ~380,000 asteroids. Wikipedia has 418 pages for these - including one for each thousand-range of asteroids. Every single one of these pages includes the phrase: As minor planet discoveries are confirmed, they are given a permanent number by the IAU’s Minor Planet Center (MPC), and the discoverers can then submit names for them, following the IAU’s naming conventions. The list below concerns those minor planets in the specified number-range that have received names, and explains the meanings of those names. ...

Sambar Styles

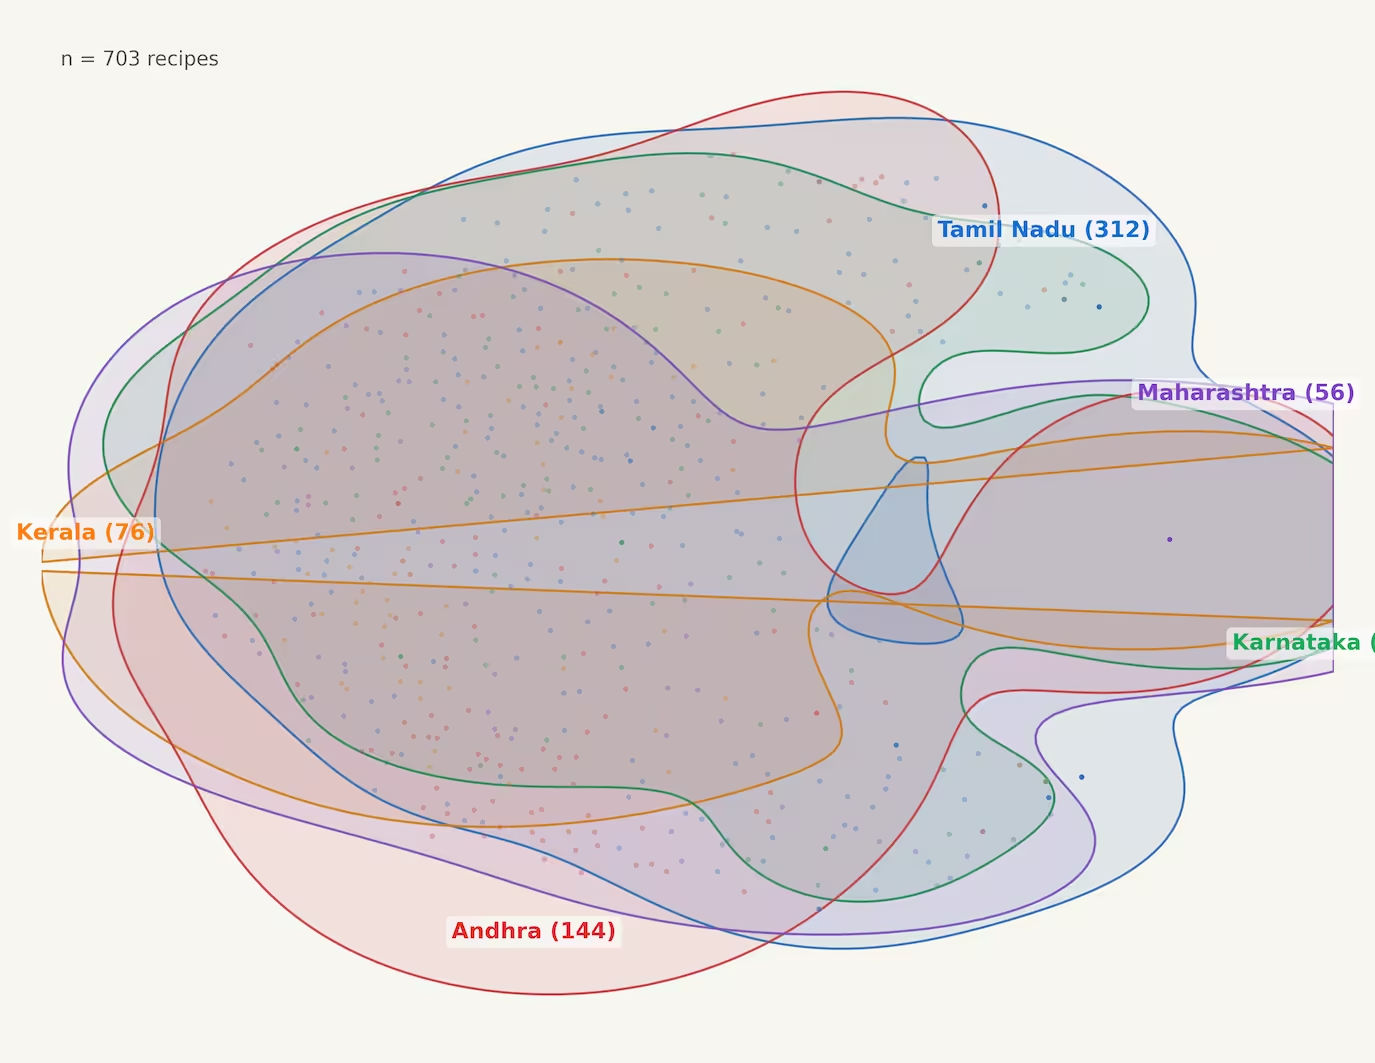
My wife’s sambar tastes different from my mother’s. And mine, too. When I cooked as a bachelor, my neighbour would pop by, taste the sambar, and exclaim, “Rasam super!” Surbhi’s Day 5 of the 30-day challenge was about Sambar which inspired me to take her dataset and create a decision tree for which state a sambar recipe is from based on its ingredients. ChatGPT started with 68 recipes and built a tree at 41% accuracy. As we added more recipes: ...

Tools in Data Science - Jan 2026

My Tools in Data Science course is available publicly, with a few changes from last year. First, I removed all the content! Last year, Claude generated teaching material using my prompts. But what’s the point? I might as well give students the prompts directly. They can tweak it to their needs. This time, TDS shares the questions needed to learn a topic. Any AI will give you good answers. Second, it focuses on what AI does NOT do well. Coding syntax? Who cares. Basic analysis? ChatGPT can do that. In fact, each question now has an “Ask AI” button that dumps the question into your favorite AI tool. Just paste the answer and move on. ...

The Jamnagar Chokepoint - Data Story

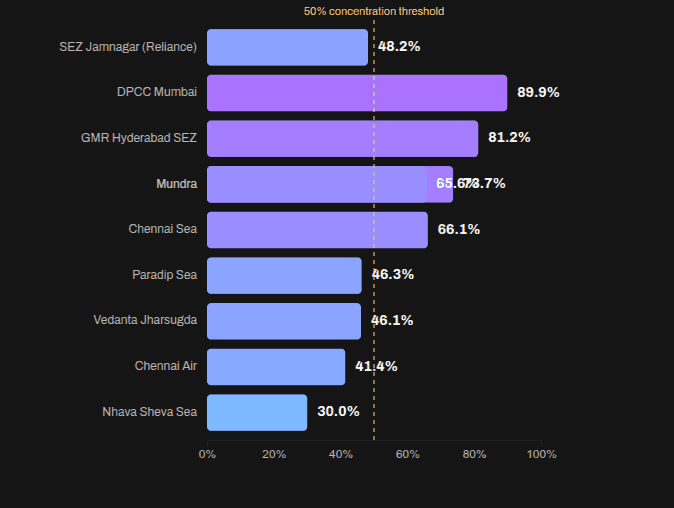
Vivek published an Indian commodity export/import dataset on 31 Dec 2025. Codex and Claude increased their rate limits for the holiday season, so I had: Codex analyze the data (OpenAI models are a bit more rigorous) and create an ANALYSIS.md file. Claude create a visual story based on the analysis. (Claude narrates and visualizes better). Here is the data story. Here are the prompts used. Analyze I downloaded export-import.parquet from https://github.com/Vonter/india-export-import which has data sourced from the Indian [Foreign Trade Data Dissemination Portal](https://ftddp.dgciskol.gov.in/dgcis/principalcommditysearch.html) Each row in the dataset represents a trade entry for a single commodity, country, port, year, month, and type (import or export). - `Commodity` string: Name of the commodity - `Country` string: Name of the foreign country - `Port` string: Name of the port in India - `Year` int32: Year for the import/export activity - `Month` int32: Month for the import/export activity - `Type` category: Type of trade (Import or Export) - `Quantity` int64: Quantity of the commodity - `Unit` string: Unit for the quantity - `INR Value` int64: Value of the commodity in INR - `USD Value` int64: Value of the commodity in USD Analyze data like an investigative journalist hunting for stories that make smart readers lean forward and say "wait, really?" - Understand the Data: Identify dimensions & measures, types, granularity, ranges, completeness, distribution, trends. Map extractable features, derived metrics, and what sophisticated analyses might serve the story (statistical, geospatial, network, NLP, time series, cohort analysis, etc.). - Define What Matters: List audiences and their key questions. What problems matter? What's actually actionable? What would contradict conventional wisdom or reveal hidden patterns? - Hunt for Signal: Analyze extreme/unexpected distributions, breaks in patterns, surprising correlations. Look for stories that either confirm something suspected but never proven, or overturn something everyone assumes is true. Connect dots that seem unrelated at first glance. - Segment & Discover: Cluster/classify/segment to find unusual, extreme, high-variance groups. Where are the hidden populations? What patterns emerge when you slice the data differently? - Find Leverage Points: Hypothesize small changes yielding big effects. Look for underutilization, phase transitions, tipping points. What actions would move the needle? - Verify & Stress-Test: - **Cross-check externally**: Find evidence from the outside world that supports, refines, or contradicts your findings - **Test robustness**: Alternative model specs, thresholds, sub-samples, placebo tests - **Check for errors/bias**: Examine provenance, definitions, methodology; control for confounders, base rates, uncertainty (The Data Detective lens) - **Check for fallacies**: Correlation vs. causation, selection/survivorship Bias (what is missing?), incentives & Goodhart’s Law (is the metric gamed?), Simpson's paradox (segmentation flips trend), Occam’s Razor (simpler is more likely), inversion (try to disprove) regression to mean (extreme values naturally revert), second-order effects (beyond immediate impact), ... - **Consider limitations**: Data coverage, biases, ambiguities, and what cannot be concluded - Prioritize & Package: Select insights that are: - **High-impact** (not incremental) - meaningful effect sizes vs. base rates - **Actionable** (not impractical) - specific, implementable - **Surprising** (not obvious) - challenges assumptions, reveals hidden patterns - **Defensible** (statistically sound) - robust under scrutiny Save your findings in ANALYSIS.md with supporting datasets and code. This will be taken up by another coding agent to create reports, data stories, visualizations, dashboards, presentations, articles, blog posts, etc. Ensure that ANALYSIS.md is documented well enough so that all assets are clear, the approach, intent and implications are understandable. Visualize I downloaded export-import.parquet from https://github.com/Vonter/india-export-import which has data sourced from the Indian [Foreign Trade Data Dissemination Portal](https://ftddp.dgciskol.gov.in/dgcis/principalcommditysearch.html) Each row in the dataset represents a trade entry for a single commodity, country, port, year, month, and type (import or export). - `Commodity` string: Name of the commodity - `Country` string: Name of the foreign country - `Port` string: Name of the port in India - `Year` int32: Year for the import/export activity - `Month` int32: Month for the import/export activity - `Type` category: Type of trade (Import or Export) - `Quantity` int64: Quantity of the commodity - `Unit` string: Unit for the quantity - `INR Value` int64: Value of the commodity in INR - `USD Value` int64: Value of the commodity in USD Then I had Codex analyze it. The analysis is in ANALYSIS.md. Find the most intesting insights from ANALYSIS.md and create a data story with supporting visualizations. Write as a **Narrative-driven Data Story**. Write like Malcolm Gladwell. Think like a detective who must defend findings under scrutiny. - **Compelling hook**: Start with a human angle, tension, or mystery that draws readers in - **Story arc**: Build the narrative through discovery, revealing insights progressively - **Integrated visualizations**: Beautiful, interactive charts/maps that are revelatory and advance the story (not decorative) - **Concrete examples**: Make abstract patterns tangible through specific cases - **Evidence woven in**: Data points, statistics, and supporting details flow naturally within the prose - **"Wait, really?" moments**: Position surprising findings for maximum impact - **So what?**: Clear implications and actions embedded in the narrative - **Honest caveats**: Acknowledge limitations without undermining the story Visualize like The New York Times Interactives. Ensure that all visualizations interactive and provide revelatory insights as well as some kind of delightful experience. Follow the typography, color & theme, backgrounds, interaction patterns, and animation principles of The Verge's frontends. Generate a single page index.html + script.js.
Mining Digital Exhaust Workshop 2025

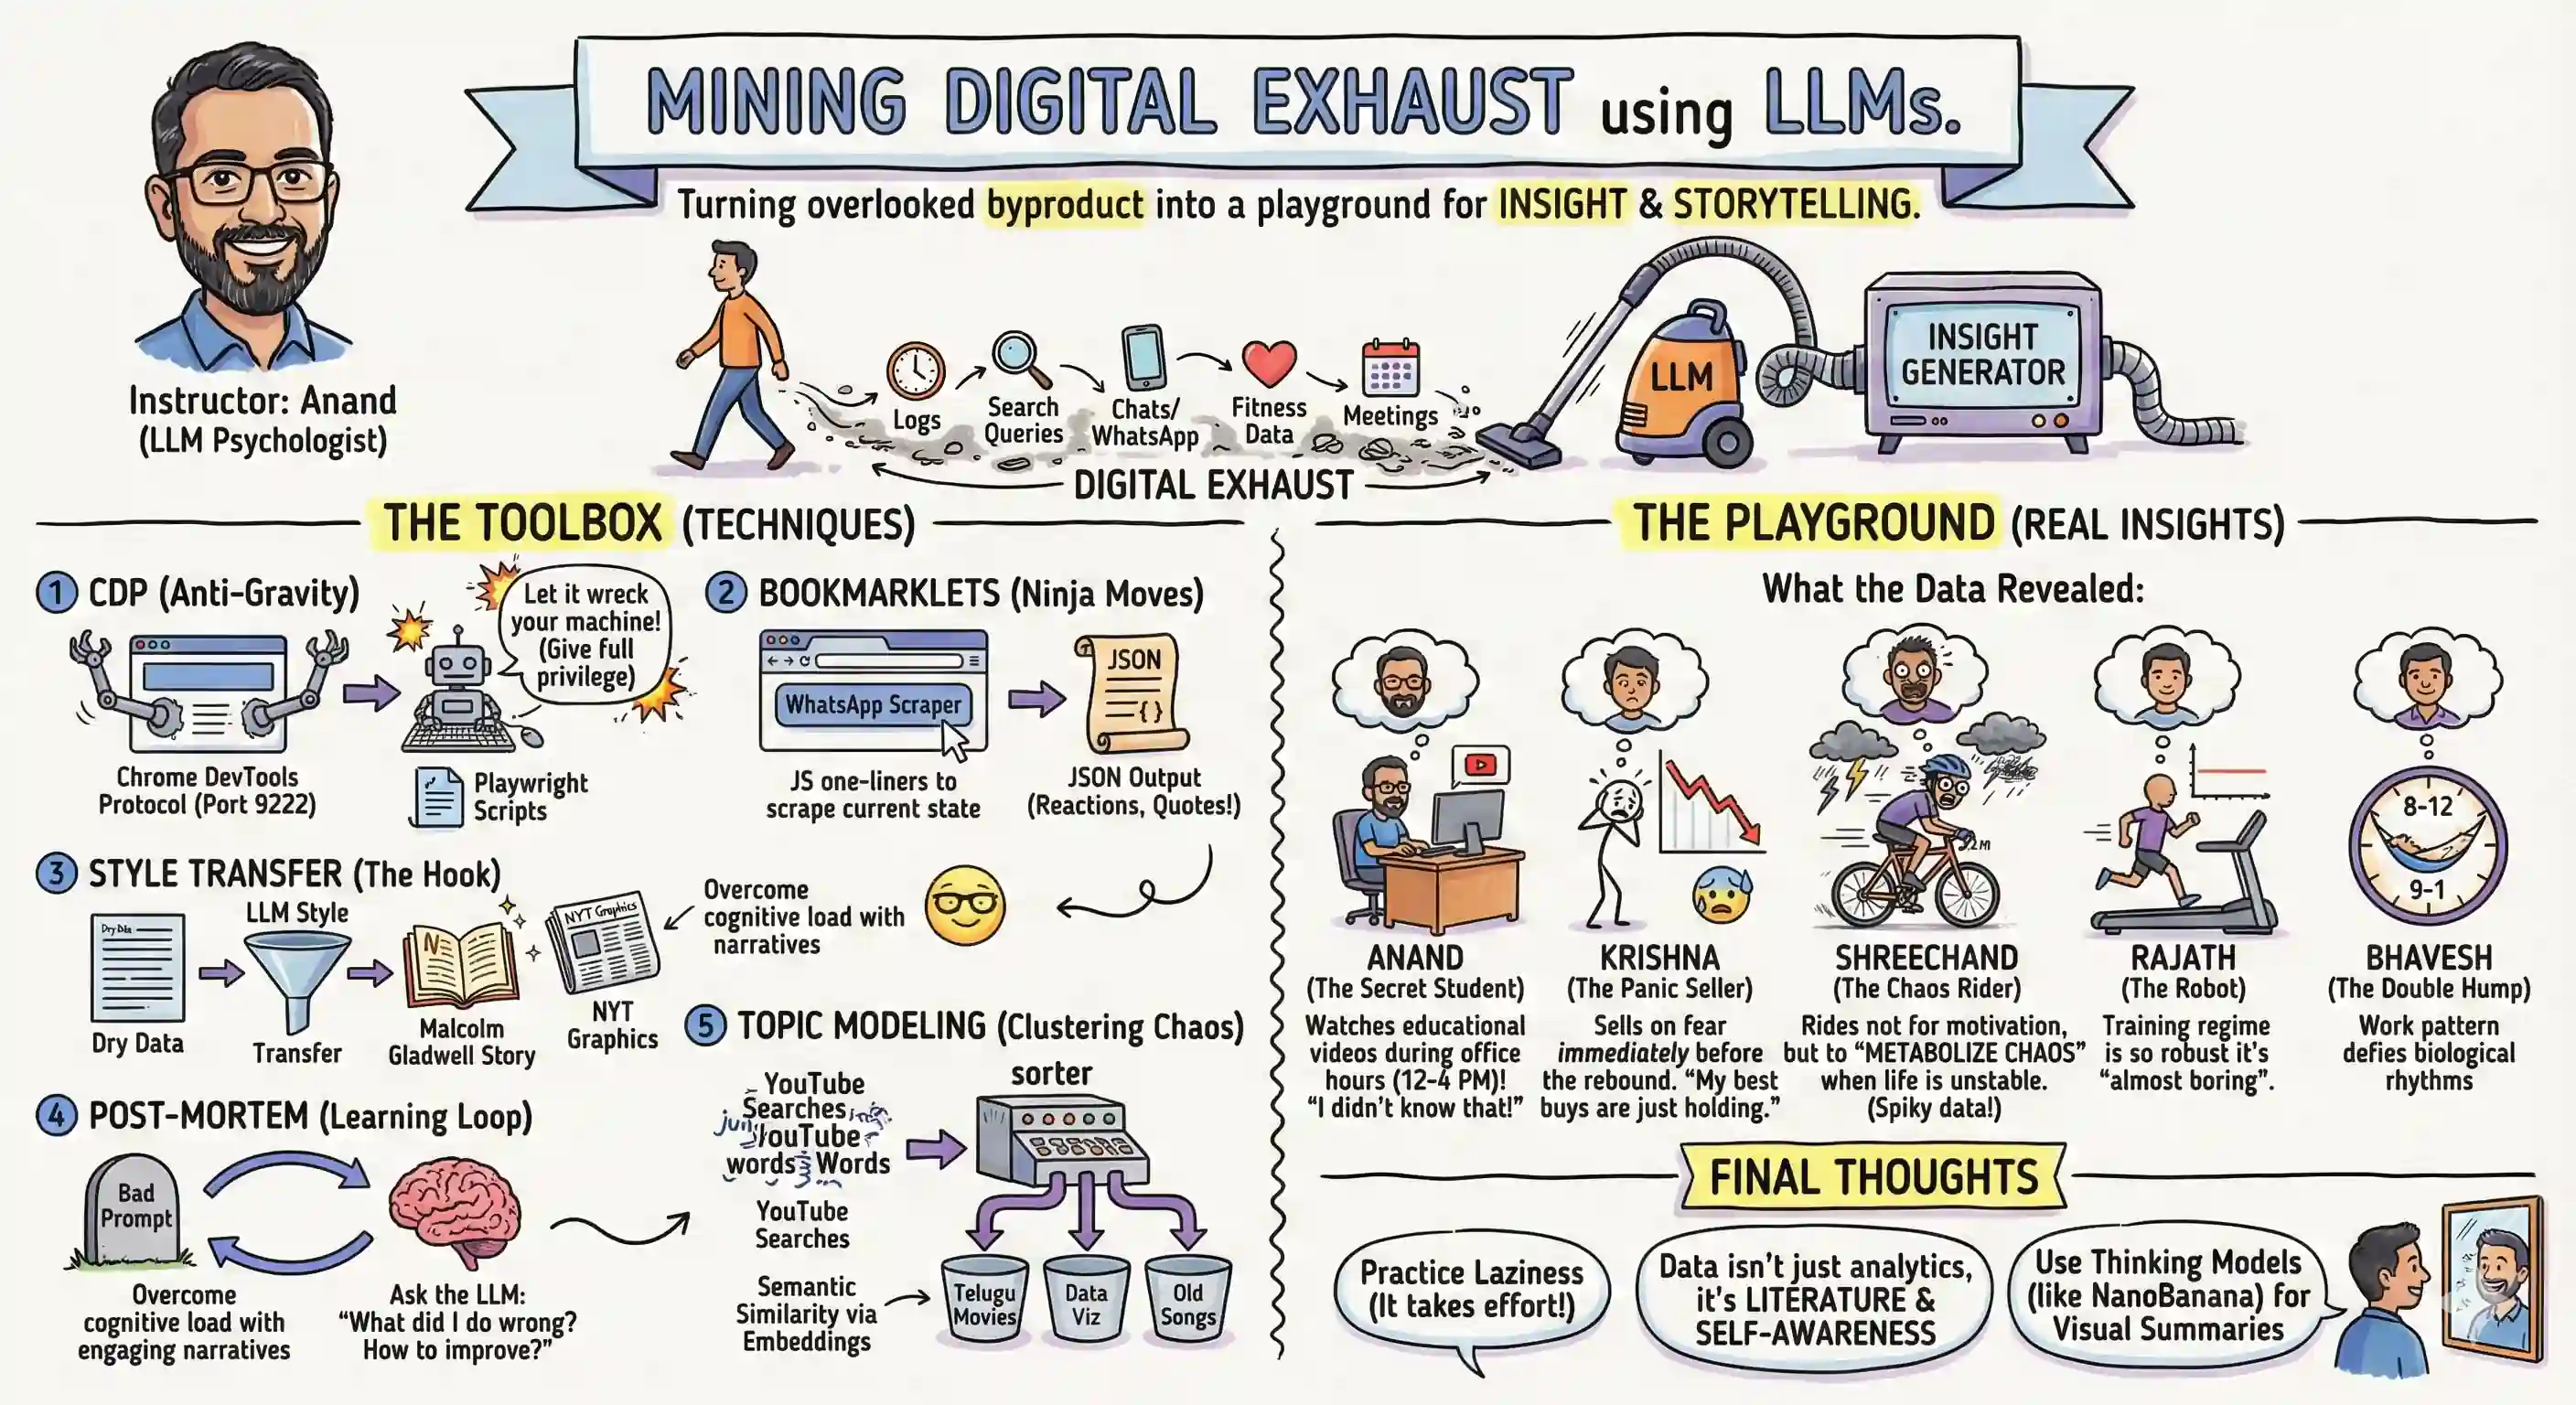
In my Mining Digital Exhaust workshop on Saturday, One discovered that they cycle when life is unstable, not for fitness. Another found that their buys are good but sells are bad trades. I learnt that I watch YouTube most at office (12-4 pm), not at home. How? A fairly straight-forward process: Export your personal data. (Use Chrome Devtools Protocol to scrape.) Upload to ChatGPT, Gemini, Claude, … and have them analyze with code. Have them narrate in the style of your favorite author. Models are super smart, but everyone has equal access to them. Your personal data is unique. Combine them to get something powerful. ...

Data to Decisions with AI

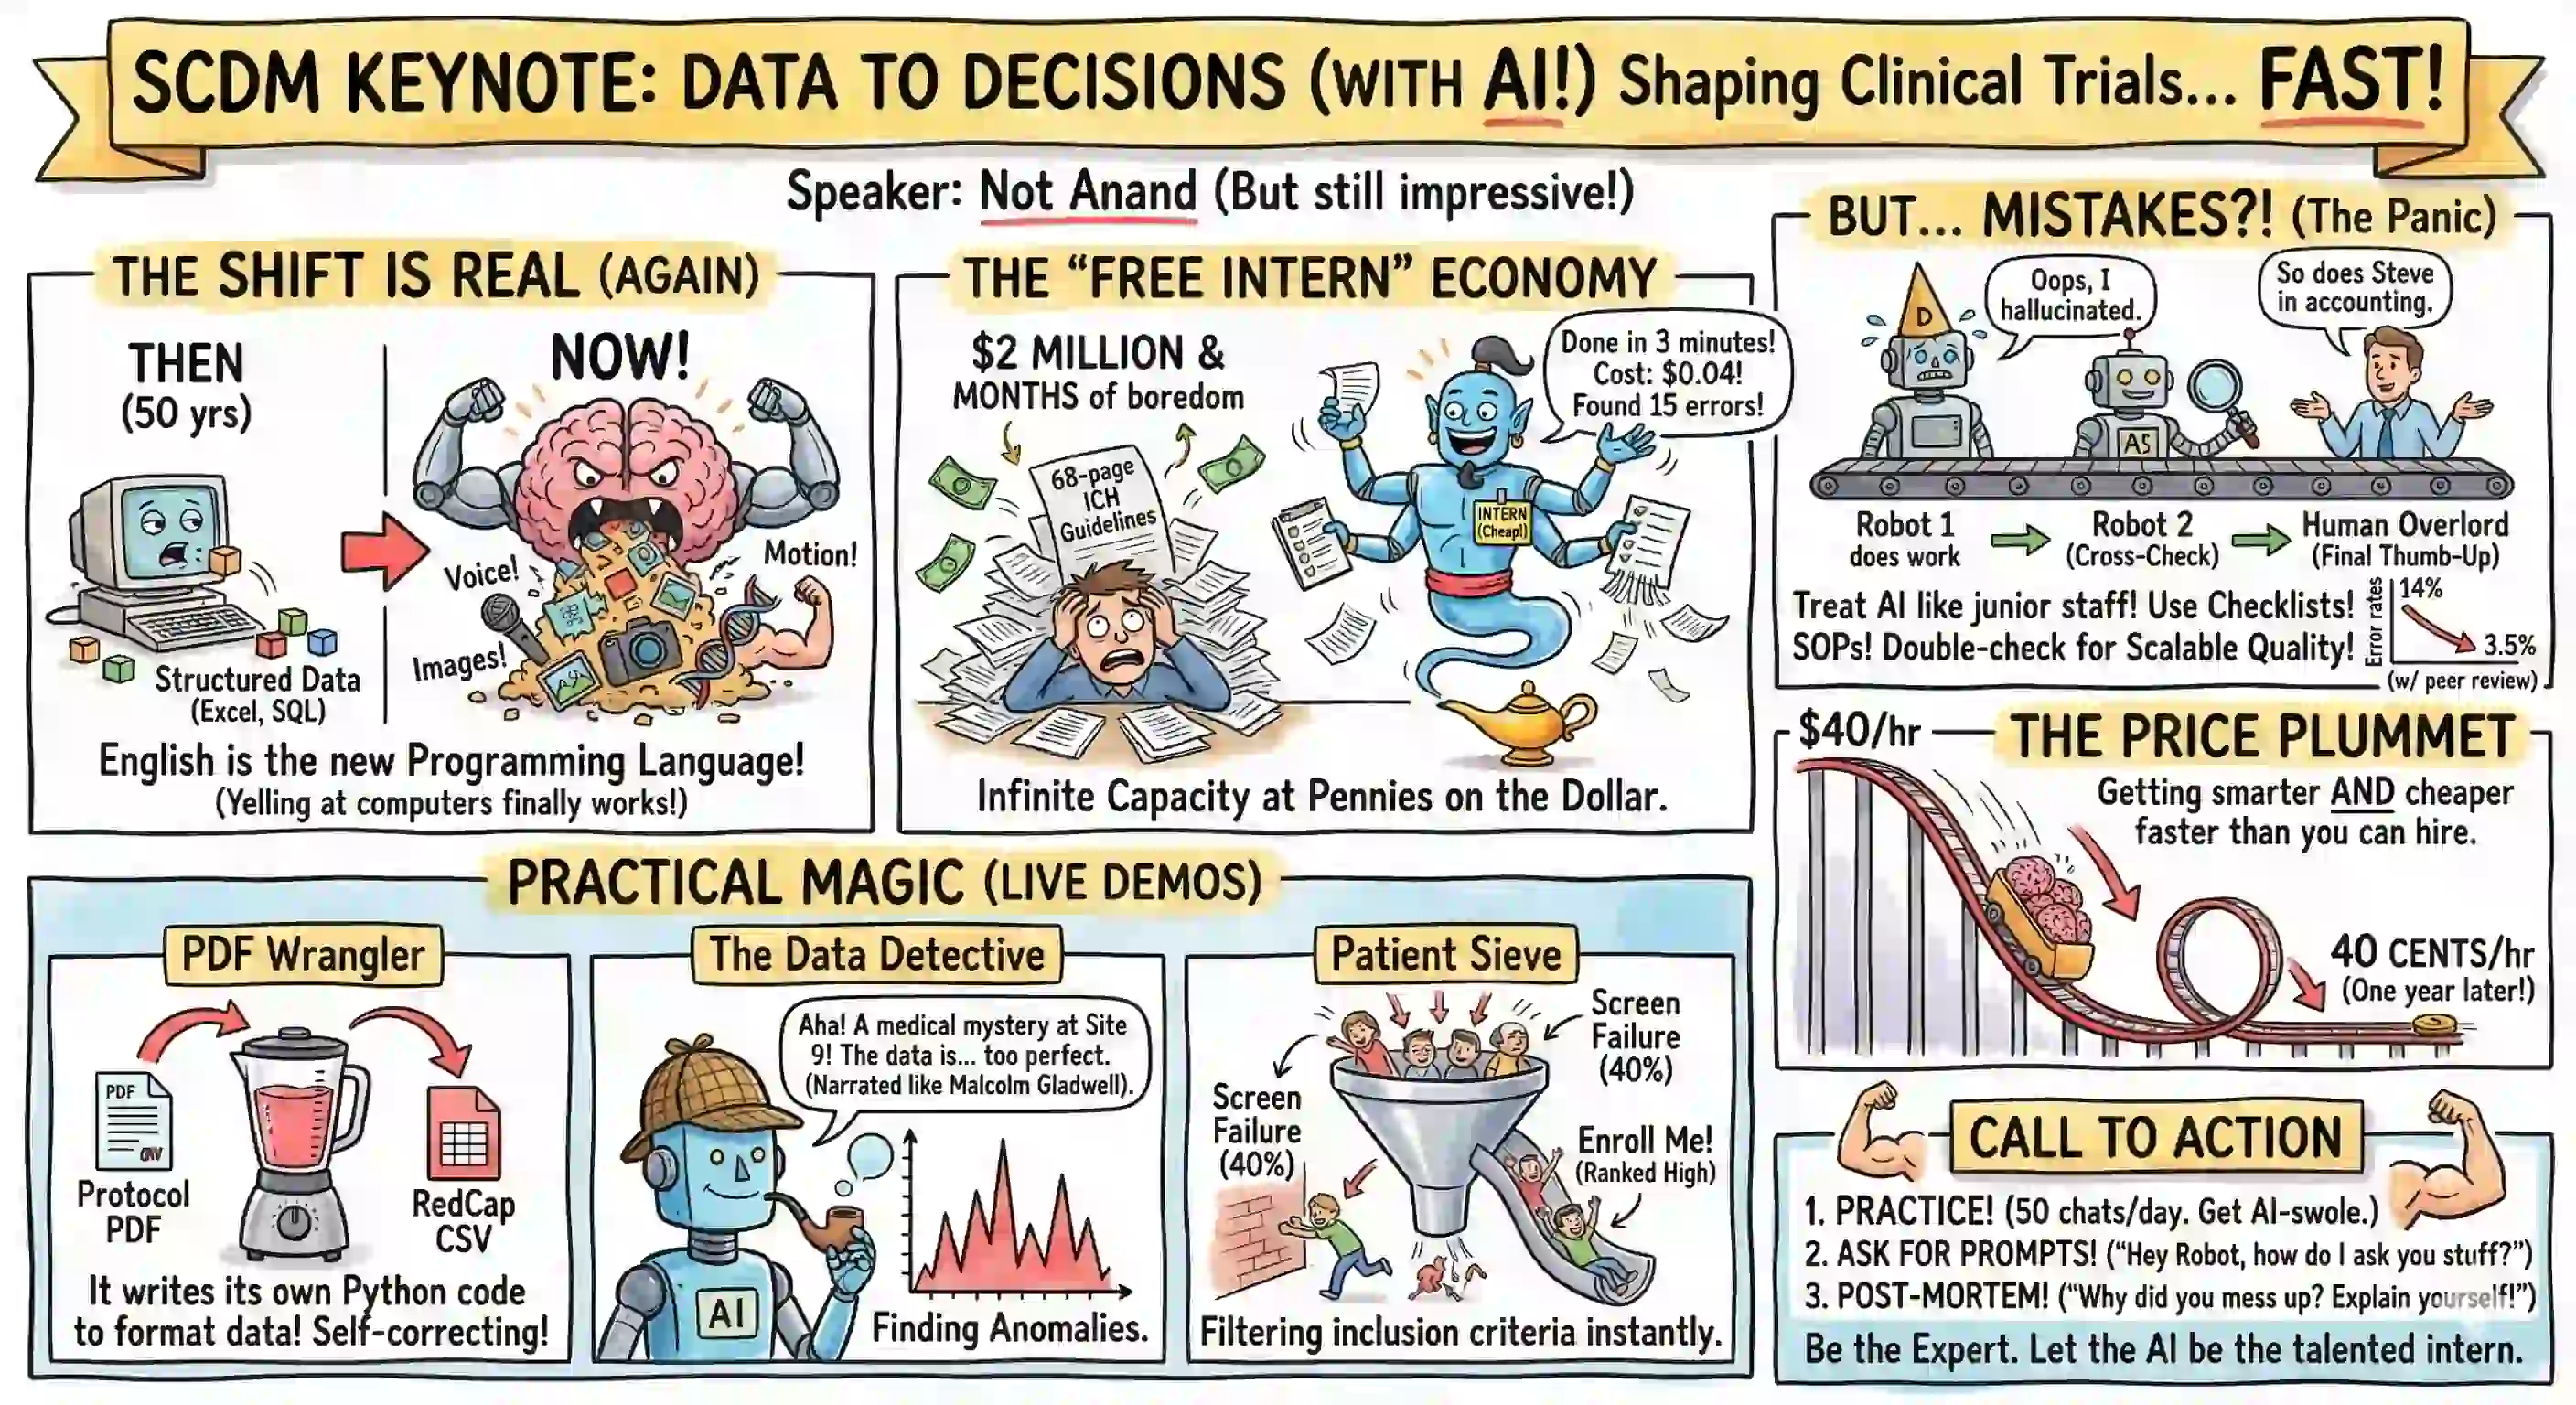
I conducted a session on Fri, 05 Dec 2025 at SCDM India Conference 2025 - Hyderabad, India. Summary: LLMs can automate expensive clinical-data work from protocol checks to anomaly detection and enrollment analysis, provided verification is designed into the workflow. Here’s the link to the session Links: Story Transcript Audio (30 min)

Vibe Analytics

I conducted a session on Wed, 03 Dec 2025 at IIM Alumni Singapore - Remote. Summary: Vibe analysis lets AI handle code and analytical mechanics while you focus on useful questions, surprising insights, verification, and what action follows. Here’s the link to the session Links: Story Transcript Audio (107 min)

Vibe Analysis

I conducted a session on Thu, 16 Oct 2025 at Landmark Group - Remote. Summary: Vibe analysis delegates the analytical process to agents and focuses humans on business outcomes. Explore broadly, verify key claims, and automate successful analyses afterward. Here’s the link to the session Links: Video (123 min) Transcript

Vibe Analysis Fifth Elephant Workshop

Tomorrow, we’ll be vibe-analyzing data at a Hasgeek Fifth Elephant workshop. It’s a follow-up to my DataHack Summit talk “RIP Data Scientists”. I showed how it’s possible to automate many data science tasks. In this workshop, the audience will be doing that. Slides: https://talks.s-anand.net/2025-09-16-vibe-analysis/ (minimal because… well, it’s “vibe analysis”. We’ll code as we go.) Here are datasets I’ll suggest to the audience: India Census 2011: https://www.kaggle.com/datasets/danofer/india-census MovieLens movies: https://grouplens.org/datasets/movielens/32m/ IMDb movies: https://datasets.imdbws.com/ Occupational Employment and Wage Statistics (OEWS): https://www.bls.gov/oes/tables.htm Global AI Job Market & Salary Trends 2025: https://www.kaggle.com/datasets/bismasajjad/global-ai-job-market-and-salary-trends-2025 Flight Delay Dataset: https://www.kaggle.com/datasets/shubhamsingh42/flight-delay-dataset-2018-2024 London House Price Data: https://www.kaggle.com/datasets/jakewright/house-price-data Exchange Rates to USD: https://www.kaggle.com/datasets/robikscube/exhange-rates-to-usd-from-imforg-updated-daily Thailand Road Accidents (2019-202): https://www.kaggle.com/datasets/thaweewatboy/thailand-road-accident-2019-2022 … but if you’d like stories from any interesting recent datasets (10K - 10M rows, easy-to-download), please suggest in the comments. 🙏 ...

DuckDB is the new Pandas

I conducted a session on Sat, 13 Sep 2025 at PyCon India 2025 - Bangalore, India. Summary: DuckDB offers a simpler, faster analytical default than Pandas for many workloads: SQL, low memory use, remote files, rich functions, and embedded deployment. Here’s the link to the session Links: Video (28 min)

Rip Data Scientists

Slides for my DataHack Summit talk (controversially) titled RIP Data Scientists are at https://talks.s-anand.net/2025-08-21-rip-data-scientists/ Summary: as data scientists we explore, clean, model, explain, deploy, and anonymize datasets. I live-vibe-coded each step with DGCA data in 35 minutes using ChatGPT. Of course, it’s the tasks that are dying, not the role. Data scientists will leverage AI, differentiate on other skills, and move on. But the highlight was an audience comment: “I’m no data scientist. I’m a domain person. I’ll tell you all this: If you don’t follow these practices, you won’t have a job with me!” ...

Social Code Analysis

I conducted a session on Mon, 11 Aug 2025 at PyConSG Education Summit 2025 - Singapore. Summary: Code can be analyzed socially, not just technically: repository behavior, collaboration patterns, and AI-based evaluation reveal how people build software and where process breaks. Here’s the link to the session Links: Video (15 min) Transcript

Solving Industrial Problems with Live Coding

I conducted a session on Wed, 23 Jul 2025 at AWS Innovation Day — Manufacturing, Industrial and Supply Chain - Singapore. Summary: LLMs can turn messy industrial and IoT data into working analyses live, collapsing the gap between domain question, code, model, and decision. Here’s the link to the session Links: Transcript Audio (11 min)