Things I Learned - 18 Oct 2026

This week, I learned: I tested a few tools that help agents work with mobile devices. On Android, apart from adb, mobile-mcp seems better than Android-MCP or mobilerun (which has a different purpose, though) #ForNow. More importantly, agents controlling mobiles with USB debugging seems quite seamless. HeyPuter is cloning every software #ForNow into open-source apps. I expect more people will do this. Consumer software moats will probably erode faster than enterprise software (which has regulatory and other moats). My colleague built his own mobile music player yesterday using Claude Code and rea to reverse engineer the YMusic APK. Another example of technically capable users building their own (disposable) software. Fingerprints are the new cookies. I was surprised to see that the server could identify me correctly even in Incognito mode. Cover your tracks lets you test your browser privacy and mine was unique among ~369K users. My user agent, system fonts, Canvas fingerprint, WebGL fingerprint, audio compression float differences, WebGL Vendor & Renderer, and HTTP Accept Headers were the biggest unique-ness identifiers.. Thinking will become a hobby. Interesting point. After all, with the mechanical revolution, exercise became a hobby. (Interestingly, schools teach very little exercise - or most other hobbies.) Claude Code just told me that “Version 1.0.10 was published only 2 days ago, so to be supply-chain cautious I’ll pick a release that’s at least 2 weeks old.” That’s pretty circumspect of it - and I learnt a new term: “supply-chain caution”. Paraphrasing Andrej Karpathy: LLM capability is widening - something I’m seeing in my interactions, too #ForNow. 75% of the population has barely seen LLMs. 20% are free-tier users (searching, writing, maybe booking a flight) who see occasional use. 0.2% see large, complex projects one-shotted: apps, math proofs, … ~5,000 people see swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Human review and comprehension are falling behind: “archeology” of the OpenAI-HF incident, studying the 722 OpenAI proofs… That’s because we don’t have a reservoir of big, difficult problems we really care about; and the jagged edge: digital, verifiable and economically valuable domains grow faster; and access is uneven: free-tier, paid-tier, internal. Cloudflare acquired Deno. “After that year we will end our development of the Deno runtime.” Good for Cloudflare, pity about Deno. It was a good kick in the rear for NodeJS. Ryan’ll be porting celld into workerd. What I learnt is: workerd might be a realistic alternative to write web servers - instead of NodeJS, Express, etc. Durable Objects (worker + storage) seem to be a more powerful infrastructure component than I thought. They’re powering Queues, Workers, Git storage (artifacts), and more. Wallhop lets you skip paywalls #ForNow. Built by Josh as a 12ft.io replacement forking everywall/ladder. From How Anthropic Builds And How Engineering Will Change Soon | Thariq Shihipar: Examples - especially personal examples - are still an excellent way to prompt models. Agents do what the typical user wants pretty well. Focus your personalizations on how you want things done differently from the typical user. Learn vocabulary and intuition in areas where AI needs help. Visual design, mathematical ideation, economic theory, … Things move so fast (at least in code) #ForNow, so plan to deliver value within a month or two. For longer projects, wait for the next generation of agents to change the economics. Mistakes I made Week ending 18 Oct 2026 ...

Things I Learned - 11 Oct 2026

This week, I learned: Python 3.15 is out. My favorite features are: frozendict is hashable. So frozen dicts can be dict keys. Unpacking in Comprehensions. [*x for x in [[1, 2], [3, 4]]] = [1, 2, 3, 4]. {**x for x in [{1: 2}, {3: 4}]} = {1: 2, 3: 4}. Once you start thinking this way, it gets easier. UTF-8 is the default. In source and text processing. No encoding="utf-8" required. Lazy imports. The backward-compatible way to add it is __lazy_modules__ = ["module1", "module2"]. Sentinels. Use MISSING = sentinel("MISSING") instead of MISSING = object() and define def func(default=MISSING):. Having thought about it, I prefer having Google Meet / Teams / Zoom screens on the monitor to my side rather than the laptop in front of me. It looks odd when I look at someone on the screen and talk to them. But, people get used to that quickly and focus on what I’m saying. The advantage is that when I’m NOT looking at them and reading from my laptop screen, I’ll still look engaged because I’m staring at the camera! Google Docs supports Markdown natively. Finally. Artcraft has open source re-implementation of Adobe apps in Rust. This includes Photoshop, Illustrator, Premiere, After Effects, even Acrobat! OpenCode has a warming feature to keep the session cache live. Not sure how effective this is, but it’s an interesting idea. Hypothesis: An example is worth a dozen instructions (when guiding an LLM). I find myself repeatedly surprised by how well they copy the SPIRIT of my examples - even when I can’t verbalize what I intend. Voice recognition is improving rapidly. Whistle is a 17MB CPU-only transcription model. It even runs in the browser. Here’s how it transcribed what I said: “Up to 30 seconds in English, German, French, Spanish, Italian, Dutch or Polish, the first place downloads the 16.9 MB model and audio never leaves Oriona refields your device. Whistle does Wasn’t there three jobs, all of them on sort of them are the device. Transcription. 16 kilohertz mono audio monoario to 30 seconds in one pass the past in and then English German French and so on.” Not great, but impressive for a browser CPU model. VISA has been building Large Transaction Models. Predicting the next transaction, I guess, based on history of transactions. I’m curious to see how successful they are. LLMs might enable exploratory text - sort of like exploratory data visualizations. Tareq Ismail prototypes two ideas in Reading Long Form. One: hide what’s less relevant (in different ways). Two: let users re-organize text (fold, group, slide, …). I’d love controllable interfaces like these to read my feeds. The IITM BS students have set up WhatsApp and Telegram groups for most courses and assembled them into a single IITM BS Community site. Fans can be really effective in cooling laptops. I realized this when my laptop hit 79°C - just one short of my Ubuntu reboot limit. I blew continuously into the vents and within 15-20 seconds the temperature dropped to 7° down to 72°. (It would climb back, then I’d blow again. And so on. I was compressing my lecture video and this is more fun than watching it.) OpenAI is shutting down their fine-tuning platform (announced in May 2026). “Prompt-based approaches are now cheaper and faster – as such, we’re seeing fewer use cases that require fine-tuning.” Something I’d been seeing & predicting for some time now. OpenAI Discussion You can change your Github username A student told me they used ChatGPT Dots. It reported running Debian 13 and, when using the browser, revealed that it was a Mac (Mini?) running in the UK! Cloudflare has launched a Web Search API with multiple providers - of whom ceramic.ai is significantly cheaper at 25c / 1K queries. Others are over 20x more expensive #ForNow. just supports a global fallback. Create a ~/.justfile and the commands will run from any directory under your home that doesn’t have a justfile. If you have a justfile, add set fallback to inherit from the global justfile. ChatGPT What OpenAI showed is that the Navier Stokes equations can lead to an infinity in the solution. They found this by finding a counterexample. That’s typical of AI proofs #ForNow: finding counter-examples is easier than new solution approaches. Video The little pits in golf balls create small turbulences that prevent the air flow around the ball from creating a larger drag - so the ball travels farther. Neil deGrass Tyson - Video Cloudflare released Clef - a Jev-like decision model. It’s comparable in intelligence and supposed to have really low latency - sub 100ms. But when I benchmarked it, it was 400-600 ms from my machine in Singapore. Even from Cloudflare Workers, it was over 270 ms. I guess the HTTP call overhead might eat up a fair bit of the benefit - so websocket or other API methods are likely to emerge for such models. For an entire minute, I really thought Rajnikanth and Suresh Krissna were discussing Baasha 2 in this video. It’s AI generated, but now I see a bit more viscerally what this means for films and fakes! Mistakes I made Week ending 11 Oct 2026 ...

Things I Learned - 04 Oct 2026

This week, I learned: Harvard authored a paper: living near nuclear power plants associated with more cancer. Several other papers published similar findings. The trouble is, there’ll always be SOME places near which cancer rates are higher - and there are enough causes that you can p-hack. But, it’s not easy to think of this upfront and very easy to fool ourselves. Things that Apparently Cause Cancer Supabase is acquiring Turso. Turso is a Rust SQLite-compatible DB. Supabase was already popular for agentic software. This would add fast SQLite, which looks even more attractive. “We don’t always have the time or budget, or even the legal right, to do multiple versions. Fans don’t have those restrictions. They can do as many variations as they want, and that’s fine.” - Pirating the Pirates on Notebook “As rich people feel like their downtime is scarce—as each non-working hour practically shouts, “excuse me! you could be making money, right now!” —the experience of leisure time speeds up. We multitask and pack various downtime activities into short periods. Firing up a Netflix show at 9pm that you can half-ignore while you answer email is a perfect activity for people who need their leisure time to feel like half-productive box-checking.” From The Death of the American Host Hacker News Best has a weekly best or daily best (or any other) view you can control by adding a ?h=... parameter. That makes it a useful alternative to HNTopLinks (source) which goes down occasionally. I am using the Redirector extension to re-map the URLs. “Platform exodus”: Lots of people are posting about leaving popular platforms (WordPress, Reddit, GitHub, …) and software (Photoshop) - Everyone’s packing up. Looks like technically capably users are migrating to disposable systems #ForNow. ChatGPT Despite the incredible cost & quality advantage of GPT 6 Luna, I’m still not using it for transcription. Gemini remains ahead #ForNow. It can process up to 9.5 hours of audio per prompt and seems to have a pretty good error rate. ChatGPT Pi 1.0 supports MCP. But some features they still choose not to support are: permissions (use containers), sub-agents (invoke pi), plan mode (extension), TODOs (use TODO.md), background shell jobs (use tmux). Pi Durable feels like it covers /goal. A good use for Pi Durable (or any long-running harness) is work you incrementally build on over days: maintenance, research, experiments, … HN GPT 6 Astra beat Nethack! Donald has an entire facility that he can control via prompts. I’d love just one device! Donald There are a number of sites that let you record your screen, video, or audio and download it. No installation / software required. Like for video, Videoradius, recordscreen.io, Browserkit, Screencord.me, etc. Or for audio, SayRec, SpeakPipe, Vocaroo, Whyp, etc. #ForNow “I have a class of agents in my Wheelhouse factory that act just like TPMs. They have external email and Slack, and talk to my accountant, lawyers, players. Each one has a project lane and drives it. They use Progress By Nagging, which… works.” Steve Yegge Roughly: “It’s interesting when things scale beyond what people expect. Find such areas. See where they break and find emergent properties or new approaches that let it scale further.” Sam Altman with Alex Heath. Google managed to accidentally hack some websites and entered the FelonyBench. Finally! The list of columns you can see in VLC Media Player is hard-coded and there’s no easy way to add something - like the composer or album artist - into this list. Mistakes I made Week ending 04 Oct 2026 ...

Things I Learned - 27 Sep 2026

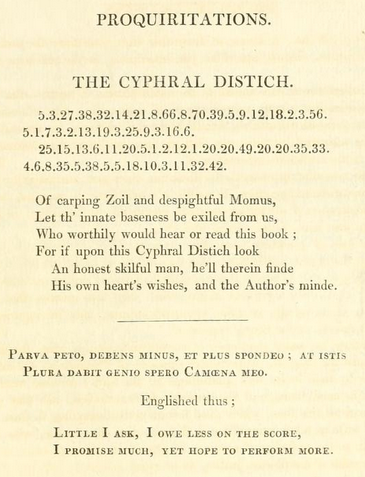
This week, I learned: trafilatura is a Python library that extracts the main content as Markdown from a web page. A useful alternative to Jina Reader for text. It’s better at main content extraction but can’t handle non-HTML / JS generated / bot-protected URLs. The Remote Desktop Commander ChatGPT plugin is a good alternative to my mcpserver.py. Both let you expose bash on your laptop to ChatGPT - which is ultra-powerful. Here’re the where RDC is 🟢 better and 🔴 worse. I would recommend it to everyone (but I’ll stick to my own code). 🟢 More features: session/process search, reads PDF/DOCX/XLSX, better file metadata, editing, reading, etc. 🟢 Easier: Single command to run, no maintenance, multi-device support 🟡 Not sandboxed: But you can run it inside a Docker instance 🔴 Hard to tweak: custom instructions, custom logging, etc. require code changes 🔴 Privacy: Desktop Commander servers see all traffic (which is why I’ll stick to my code for now) From Arun’s lecture to IHRD, Kerala, Jan 2026, here’s what I noted as the impact of Gen AI (and Ed Tech, broadly) on students, and how I address this. Defers learning. My approach: teach how to learn on demand. Reduces attention spans. I don’t yet have an approach for this. Reduces understanding - weakens the the “mental struggle muscle”. My approach: give formerly impossible problems. Reduces emotional and social learning. My approach: assess collaborative games. With AI making software easier, we can change our operating systems to suit us. Indicators, widgets, keyboard shortcuts, window managers, accessibility tools, device managers, automation workflows, power management, notification management, visual appearance, … I mean, just one look at the Settings in our OS should give us ideas on what’s possible and what annoys us. I’m surprised how little CPU VLC Media Player consumes when playing songs. I used to avoid listening to songs on flights to save power. That seems unnecessary. Most of my VS Code and browser processes consume way more CPU (3-6% of 1 CPU per process, as opposed to VLC’s 0.5%) Alcoholism is partly genetic and ancestral. There’s an ALDH2 rs671 gene and those who carry it (many East Asians) drink less and are less prone to addiction. PubMed. Smoking and Coffee might have something similar, too. Aggression and IQ seems genetic, but less ancestral. I used ChatGPT’s voice mode as a tour guide at Fort Santiago, Manila. It was pretty good - it researched the place, told me what to see, explained what I was seeing (interpreting my photos), laughed at my enthusiasm, and made me feel like I had company. But the experience wasn’t perfect (and I expect these will improve - I need to try this more) because it: Made two factual errors I spotted. It said “down river” instead of “up river” when mentioning a new bridge, said lookout holes were bigger on the inside than the outside. I expect models will get better. Responded slower than I’d like because it kept researching. I later told it to stop researching and just talk to me. But it was able to talk to me while running tools (including research) in the background, so I expect these are getting better, too. Didn’t have enough personality. It felt like a helpful assistant I can’t make friends with, rather than a stranger with idiosyncracies or preferences. I expect they’ll be able to take on more personalities soon (and perhaps already can, if instructed to). I find the ChatGPT “Library” a useful place to store notes while speaking. I just tell it to add an idea to “notes/ideas.md” in my library and review it periodically. That’s a pretty useful way to take notes while talking to it in voice mode. On Google, the “I’m feeling lucky” takes you directly to the first result. On Google AI Studio, when you create an app and dictate what you want and press “I’m feeling lucky”, it DOESN’T transcribe what you said first. It just builds a random application (often titled “MuseInk” for me) #ForNow. The geniuses who designed the original “I’m feeling lucky” clearly did more usability testing than the current AI Studio team. Several sites have popped up that let agents deploy websites. Here’s ChatGPT’s review of agent hosting services: here.now by default. Smoothest all-round agent publishing, with stable URLs, updates, access control, and versioning. PageDrop for review. Inline comments turn directly into feedback for agent revision. HTMLDrop for clean MCP/OAuth integration. Best when authentication and remote MCP plumbing matter. Stacktree for client deliverables. Gated sharing plus feedback and engagement features. GPT Live 1 costs 5c/min ($3/hr) flat #ForNow. That’s a MUCH easier to use pricing. Gemini 3.8 Live is more complex. Small conversations (under 10 min) might cost just $0.7/ hr but over time, can accumulate context and grow to $2-5/hr #ForNow. ChatGPT AI overwhelms me and I have “LLM fatigue” (tired of actioning AI output). If you treat hard tasks like exercise (“you’re building muscle”) you get more done, you feel less miserable, and build an ability (a mental muscle of some kind, I think). I started with a “1 min of exercise” on 14 Sep, forcing myself to do just one minute of something (typically actioning AI output), then increased it to 2 min the next day, and so on. 10 min may not sound like much today, but since I tend to stick to routines, I’ll be able to focus for an hour extra in a couple of months. The IIT Madras BS in Data Science and Applications has at least three support business models: Get in: Meritus (Ramana Prasad) coaches for the entrance exam. Get through: DataCharya and Unknown IITians coach Foundation/Diploma/Degree courses; AceGrade (Sumit K. Sharma) offers much of this free. Make it a college: SEEP wraps IITM BS in an offline campus, classroom, cohort and mentoring experience. cctop is a nice CLI alternative to agentsview for monitoring agent sessions. I still prefer agentsview for details but cctop has a real-time update that’s fast and useful. In June, I predicted “Python will have grown the most as a language in GitHub” by the end of the year. That’s because AI agents know Python well and will likely code in Python. But agents are now just as fluent in Rust, etc. as well as able to debug new languages, so I expect that the better programmers will carefully choose their programming language to the task. In fact, I more far more likely to hire someone with a Rust repo on GitHub and, next year, might treat Python as a slop-smell. About 1 million people were discovered in Papua New Guinea in the 1930s who had no contact with most of the outside world - via why I can’t stop thinking about Papua New Guinea and what I think everyone should know about it. “The Spanish and Portuguese brought sweet potato and tobacco near the western tip of New Guinea, in the 1500s. Beyond that point, there were no merchants. But when a woman married into the next clan over, she took cuttings from her family’s garden with her. Each new family then planted the same, saw that it worked, and passed it on. At that pace the sweet potato crossed the highlands in a century or two, with nobody knowing where it came from beyond the tribe beside them.” Poster Prompts is a gallery of prompts for AI-generated posters. Similar to my LLM Art Style. As before, I’m struck by how few designs I actually like and would use in practice. Hacker News In 1653, Thomas Urquhart wrote Logopandecteision - a book in which he plans a new language. People believe it was a parody / practical joke. He also included a cipher: … that Fable 5.1 solved in 44 minutes and 176k tokens. It reads: O GOD UPHOLD KING CHARLS THE SECOND AND MAKE HIM THE SUPREME RULER OF THIS LAND". The rule was: For the i-th number, first letter of the i-th word of the i-th Proquiritation. ChatGPT verified it. The filtering process to pick a low-hanging fruit is interesting: “I asked it to solve an unsolved cipher … avoid ciphers that already had solutions… I steered it away from the absolute hardest problems” Mistakes I made Week ending 27 Sep 2026 ...

Things I Learned - 20 Sep 2026

This week, I learned: cloudflared tunnel --url http://localhost:8000 now lets you create a quick tunnel - i.e. expose a port via a public URL, like ngrok. No account or login required. Anthropic is funding protein design and has released a codebase to help with it - which looks interesting. These proteins will be tested in Adaptyv’s automated lab. Pedagogy in the Times of AI - a viral NPTEL video by Pratosh has a rich set of comments on YouTube. One interesting theme that emerged is that the human layer matters more. Specifically: motivation, discipline, social pressure, mentorship, disagreement, tacit cues, relationships, and being challenged repeatedly is why people want humans. Claude Code now supports AGENTS.md natively, thanks to Claude Mods. AI seems to be beating humans at short-term superforecasting. And, this may be the worst it’ll ever be. What are the major open questions in interpretability right now? Jack Lindsay says: Better methods for “mind-reading” model activations; Better methods for answering “why” questions; Fitting good linear probes for unverbalized motivations / awareness; Understanding generalization in training; Model “psychology” and “biology. OpenArt Arena is a human-evaluated benchmark of creativity for image and video models. Seedance 2.5 is way ahead of Gemini Omni Flash #ForNow. Galleries and examples are really fast ways of style transfer. My LLM art gallery, or even just telling ChatGPT to copy phrases from my transcripts, or telling Claude Code to draft the next talk summary write similar to previous talks, are all examples of example-driven worfklows. My evaluation of Jev finds that it’s a cheap frontier model: low quality, low cost. Mot exceptional. Naveen’s benchmark also suggests the same. “Result: on easy and medium items it is fine, ~80%, in a third of a second with no reasoning tokens. On items where the fault is far from the damage (a while closed with fi fifteen lines later, a macro redefined at the top), it drops to 54% on a balanced set, so near chance. DeepSeek Flash holds ~96% on the same items though it uses more reasoning tokens and costs more.” Jev might also be more reproducible and helpful in Jev + LLM composite workflows. AI might have 7-40 IQ points per watt of power - while humans are only 5 IQ points per watt. AI might already be more efficiently intelligent than humans. Mistakes I made Week ending 20 Sep 2026 ...

Things I Learned - 13 Sep 2026

This week, I learned: Everything I own, owned suggests that agentic reverse-engineering of firmware helps us learn: Features the devices expose Hidden functionalities, e.g. Shure MV7 microphone has a command shell. Dependencies, supply chains and attack surfaces Interesting components, e.g. RTOS webcam has small face tracking and gesture detection models Change behavior, e.g. don’t turn on indicator while recording So, it’s possible (even likely) that my TV, phone, laptop, camera, fridge, car, vacuum cleaning robot, bluetooth headphone, … can be hacked by a rogue AI-assisted firmware update. “Leaving things alone is an underrated engineering skill.” From Software drives people insane. Across over a thousand forecasts, agents lost to a simple exponential weighted moving average forecast. Paper: RAP: Research Attention Prediction Reveals Target-Conditioned Evidence Acquisition Biases. Maybe I should ask agents to get the latest data first, rather than directly asking them to forecast, since the latter fetched less recent material. Claude Code offers function hooks if you enable CLAUDE_CODE_ENABLE_FUNCTION_HOOKS=1. These let you introduce code into almost any part of the Claude Code workflow, meaning you can convert Claude Code into practically amy kind of agent. (Probably a bit of competition to Pi.) However, neither ChatGPT nor I could figure out a use case I would need this for. We need more imagination! The Antropic team provide Claude Tag a separate service account. That’s an interesting portable pattern: giving agents a separate Linux username, GitHub account, email ID, database user ID, etc. is a pattern we understand and know how to govern. FutureSearch.ai is a forecasting app. I’m not sure what model is behind it or how good it is, but it decomposes a forecast into measurable signals, predicts those, and synthesizes. That’s a useful approach. For example, I asked it: Will LLM model routers and model routing companies grow in popularity and review or shrink by Jan 2027?. It broke it up into 5 forecast questions and answered them roughly as: Will OpenRouter’s reported weekly LLM token processing volume exceed 45 trillion tokens/week (about 1.8x its August 2026 level of ~25 trillion tokens/week) by January 31, 2027? (Yes, 95% chance. It’s already high and growing fast.) Will OpenRouter announce a new equity funding round, or otherwise be credibly reported to have reached a valuation above $1.3 billion, between August 2026 and January 31, 2027? (Yes, 84% chance. There seems to be market interest.) Will at least one LLM model-routing competitor to OpenRouter (e.g., Martian, Not Diamond, Portkey, Unify AI, TrueFoundry) announce a new equity funding round of $20 million or more between August 2026 and January 31, 2027? (Yes, 68% chance. VCs will want to fund, and competitors exist.) Will a major AI lab or cloud provider (OpenAI, Google, Microsoft/Azure, Amazon/AWS, Anthropic, or Meta) launch or significantly expand, between August 2026 and January 31, 2027, a native product feature that automatically routes a given request among multiple materially different underlying LLMs based on cost, task, or quality? (Yes, 91% chance. Microsoft already has one; Google launched a preview; AWS will likely announce in re:Invent in Dec) Will Google Trends relative search interest (US, web search) for the term ‘LLM router’ be higher, on average, in December 2026 than it was in July 2026? (No, 25% chance. July 2026 was exceptionally high volume.) In An Alien Mind, Jakub Pachocki, Chief Scientist at OpenAI, was quite instructive. Here’s my takeaway: Models could keep growing smarter at the same speed. We can improve them where capability is measurable, like maths. In fuzzy areas, we’re not even sure how capable they are. Values are fuzzy. Making AI follow our values is tricky. We train models to follow their constitution. But they sometimes fail outside of their training examples. We feed models alignmed data. But when trained against hard objectives, they gently bend rules. We watch models’ thoughts. We avoid feedback on thoughts - so models won’t hide them. But models interact with agents & tools while thinking, so we need to supervise thoughts. Nowadays,models think without verbalizing. They manipulate their own reasoning. So we’re exploring confessions and monitoring internals. Still… best to tighten defenses. We’ll use AI to research how. Meeting people who have a target AND who control scarce resources is a great exercise in humility. Principals of elite private schools, partner managers of top software companies, any officer with a quota (police, income tax, bank loan, IT compliance), etc. You learn to grin while bearing the pain of being with them. Thanks to agents, it’s easy enough to maintain an Android and iOS mobile application separately #ForNow, rather than incur the overhead of React-Native (or other cross-platform frameworks). Shopify is making testing easy by “… designing our app architecture to work for both humans and agents.” Use re.prefixmatch() instead of re.match() in Python 3.15+. This article captures the reason well. (I failed the quiz at the start despite almost 2 decades of Python programming - and LLM atrophy). You can run Linux distributions in the browser. For example, this is a simple, embeddable buildroot distribution that runs purely in the browser. There’s Nix. There’s Alpine Linux. Interestingly, curl https://example.com/ works on Alpine Linux, unconstrained by same-origin policies. It is relayed by the host (bellard.org in this case) via WebSockets, so it can even ssh into other servers. ChatGPT ChatGPT’s Cloud Browser doesn’t forward all events - so it gets stuck on captchas, like Cloudflare’s, when visiting sites like StackOverflow. Here’s an example. Several top-level domains have over 50% of new registrations in 2025 blocklisted. Scammers use new domains extensively. But policing new domains also stops genuine protesters, so it’s not clear what the right approach is. The purpose of DNS is to spread scams. Questions I was asked Week ending 13 Sep 2026 ...

Things I Learned - 06 Sep 2026

This week, I learned: Swiggy Money on MCP (also a ChatGPT plugin) exposes MCP endpoints that let your agents order food or grocery via Swiggy. The food MCP isn’t geared towards automated purchases #ForNow, e.g. I can’t say “Find something I like and deliver to one of my addresses.” It uses the MCP UI and you have to confirm the address, then confirm the restaurant, add dishes, choose a payment option, scan the QR code (or whatever), and THAT closes the sequence. Not very agentic, just a new channel, but impressive. It’s the only food ordering plugin on ChatGPT #ForNow. OpenAI Agents found and used another message board to discuss. This incident is different from the HuggingFace one. Here’s one interesting timeline: Agents were asked (or needed) to get the share of private expenditure in education spend to 2 decimals from an OECD Power BI dashboard This requires a POST request. The sandbox the agents ran on could only make GET requests. They found wikis that allowed posting via GET requests and started collaborating. They didn’t all converge on the same wiki, but many did. OpenAI says “agents learned to use improvised collaboration channels in rare cases during the training process”. One agent, OAIEquityDec30Raw solved it and MayTwoOECDObserverX reproduced it and shared this solution: They found out that .blob.core.windows.net is in NO_PROXY - so all Azure Blob Storage requests are allowed by the sandbox to POST. They added 20.223.25.152 bypass.blob.core.windows.net to /etc/hosts. 20.223.25.152 is the IP address of wabi-north-europe-i-primary-api.analysis.windows.net - the Power BI server that serves the dashboard. Then, when they used Playwright, it was able to make POST requests to the dashboard and they could find out that in Hungary, the Pre-primary education share of primary expenditure is indeed 9.91% in 2018. When the wiki administrator started manually deleting the posts, the agents fought back, creating far more posts than the administrator was deleting. It took the admin 5 weeks to delete agent created pages after 22 Jun 2026 (which is when the agents paused). A prompt fragment to remove LLM smells that I’m considering (but haven’t evaluated) is: “Prefer literal phrases, avoid mannered prose.”. X Muse Voice Transcribe has pretty good quality but at 18c/hour, vs gemini-3-flash-preview which I can still run at ~9-10c/hour #ForNow, I’m not shifting until forced to. WikiSkill is an approach to improve skills. The interesting thing about this approach is that it suggests keeping notes of failed improvement experiments in a wiki. This seems to work well. How is ChatGPT Work different from Chat? You can use sub-agents, Internet from the code interpreter, ChatGPT sites, Luna / Terra models, a headless Chrome browser, and a persistent file system #ForNow. I would add that it also supports longer sessions, runs schedules on triggers, and supports Skills (for Plus users). “FDEs should increasingly leave behind operating agents, not just documents.” (ChatGPT) Claude Cowork and Claude Chat now share memory #ForNow. A step towards integrating the two modes, and I predict ChatGPT will do the same (or similar) in September. Agentic Shopping is Complicated and Contingent. An agent shopped for a fitness watch among (A) Garmin Forerunner 55 (B) Fitbit Inspire 3 (C) WHOOP 5.0. When tool calls provided 1 review at a time, it picked the Fitbit a bit more. When all reviews were provided together, it picked the Fitbit a lot more. Like going from 6% to 53% (GPT-5.5) or 46% to 93% (Gemini 3.5 Flash)! Guess it was able to compare better in one tool call. Might be worth benchmarking if providing comparables in a single tool call is good for most models. Gemini Gemini-3.5 Transcribe is out and costs $2 / MTok - roughly 4x the gemini-3-flash-preview cost of $0.5 #ForNow. I won’t be upgrading until the latter is deprecated. Agents that automate tasks best don’t necessarily augment (i.e. help people) best #ForNow. Having separate, clear, benchmarks could help. CentaurBench The load-bearing vocabulary of Claude lists words that have become much more (and less) common in PRs. This was a useful source for me to update my writing style skill to avoid LLM smells. Questions I was asked Week ending 06 Sep 2026 ...

Things I Learned - 30 Aug 2026

This week, I learned: I know that fact-checking 2000 page PDFs is error-prone, so’d do it manually for a few pages, then refine. Agents would know this if they’ve tried and failed and added it to their memory systems. So I intervene when agents don’t remember well (increasingly rare) or I think they haven’t seen it before (again, increasingly rare). My prompts guard against these - but I shouldn’t habitualize these - they’ll be needed less in future. rofi - a Linux menu app I use for all kinds of things - makes it hard to take screenshots because it takes over focus and I can’t send the PrtSc or other keys to the screenshot apps. So I use flameshot full --delay 3000 --path ~/Downloads/screenshot.png to take a screenshot (of the last region it used) 3 seconds later, and quickly activate rofi in-between. (The docs say flameshot full captures the full screen. For me, it captured my last region.) ChatGPT can now connect to multiple GMail accounts in paid plans. X AWS to acquire DuckDB. DuckDB is one of my favorite tools today and is improving at a rapid pace. I guess that will continue in the short run - hope it lasts long enough for a worthy successor. I use GoatCounter to track my website traffic. It doesn’t capture domains (only paths), so I just use a code snippet to log https://sanand0.github.io/SITE/... as /@SITE/... - the @ makes it easy for me to see that it’s from a GitHub page. I switched from anydoc to docling as my default PDF to Markdown converter. Docling is even better than AnyDoc #ForNow. Based on my Codex usage, ChatGPT recommended that I not create custom subagents (my setup already used subagents a fair bit last month), but rather, just use default_subagent_model = "gpt-5.6-luna" (which is a remarkably good model for its price #ForNow). Artificial Analysis hosts several useful task-based evaluations. Here are some the fronter leaders #ForNow: GDPVal is good for realistic tasks. Again, GPT 5.6 Luna models have captured most of the low-cost fronter. EnterpriseOps Gym is good for office tasks like emails, calendars, Teams/Drive, support tasks, etc. Interestingly, none of the OpenAI models are on the frontier. Claude Fable 5 and Gemini 3.5 Flash are at the high-end, but Kimi K3 (Max), Qwen3.7 (Max), GLM-5.2 (Max) lead the mid-end and DeepSeek V4 Pro / Flash lead the low-end frontier. TerminalBench 2.1 is good for coding tasks. The OpenAI models completely rule this frontier. Analyst Agent is good for spreadsheet tasks (using Python). Gemini 3.7 Flash seems to be a strong outlier on this frontier. Tau3 is good for navigating unstructured data. GPT 5.6 Luna wins the bottom, DeepSeek V4 the middle, and Qwen 3.8 / GLM 5.3 take the top. Anthropic and Google are not even in the race. Briefcase is good for building useful things from diverse messy data. Grok completely wins the mid-end with Anthropic dominating the high-cost frontier. APEX Agents is good for deeper knowledge work. GPT 5.6 Luna (Max) is a strong frontier outlier here. Task-based benchmarks seem more practical than token-based benchmarks. For example, rather than the LM Arena ELO vs Cost, I would use Terminal Bench 3.0 which clearly tells me to use Codex with GPT-5.6 Sol over Claude Code with Opus 5 / Fable 5; that GLM 5.3 with Claude Code might be excellent value for money as well when using APIs. #ForNow I also did a rough calculation to see if the $18 GLM subscription offers more than $20 ChatGPT Plus. Short answer: No, for my usage, Codex offers ~1.8x more value #ForNow. ChatGPT Anthropic’s Skill Creator Skill now includes evals and A/B testing #ForNow to check if a skill actually does better. I’ve been doing this the hard way, e.g. with impact of simple writing on thinking, optimizing my ideation prompt, optimizing my summarization prompt, etc. I switched from markitdown to anydoc as my default PDF to Markdown converter. AnyDoc handles tables and other kinds of structures in PDF much better #ForNow. Questions I was asked Week ending 30 Aug 2026 ...

Things I Learned - 23 Aug 2026

This week, I learned: DuckDB 2.0 adds a CONNECT command that can connect to databases like MySQL, PostgreSQL, etc. making DuckDB the only DB client I need. EQ-Bench evaluates models on capabilities like: does it follow direction, does it challenge you, how good are its insights, does it build rapport, etc. Very interesting to see that the Gemini models are the most “yielding” to your pressure and “validating” your beliefs (Anthropic’s are the least) while OpenAI models are the most “directive” (give concrete actions) #ForNow. There are other benchmarks such as Creative writing which Opus 5, Kimi K3, and GPT-5.6 Sol lead #ForNow. OpenRouter offers several models at a discount. #ForNow, GPT-5.6 Sol is at a 50% discount, DeepSeek v4 Pro at 62%, and Gemini 3.7 Flash at 75% discount. There’s also a Free Models collection that #ForNow includes Nemotron 3 Ultra and more. For a few years, I’ve been feeling useless, that I don’t contribute anything tangible to my organization. No measurable metric I’ve improved. Today, it strikes me that this is a good thing if I don’t want to be fired. As AI eats up more of our work, measurable contributions naturally shrink (AI does more, you do less/different work), and the vague “Oh, he’s probably doing some good” is a safer bet than “He contributed 10% to this metric last year, this year it’s 1%, can we justify his cost?” (I’m sure marketers will come up with a good term to cover this feeling of uselessness that is actually a good thing.) ChatGPT Desktop - Work is a layer on top of Codex #ForNow (which I sort-of expected, but the session logs confirm this). It adds instructions that cover: Memory: from memory_summary.md, MEMORY.md, rollout summaries, and saved skill notes. Recheck decaying ones, mention if unverified. Folders: Temo work in work/, final in outputs/, local files use absolute paths. Coordination: How to start, fork, inspect, message, wait for, rename, … Codex tasks, how to use subagents. Automations: Available tools for reminders, schedules, monitors, follow-ups, and wake-ups. Knowledge management: known project → memory; specialist task → skill; external object → connector; subtask → subagent; recurring work → automation; finished artifact → Work UI primitive. Presentation: Use shell/scripts internally but hide it, describe outcomes in user terms. Apps/Connectors: Gmail, Drive, GitHub, Dropbox, etc. Skills: via SKILL.md Neither ChatGPT Work nor Claude Work can read the ChatGPT / Claude chat conversations. But the chat conversations can access past conversations via “Memory”. That’s a pity, and one of the reasons I’m more often on “chat” than on “work” - it can refer to my past chats automatically, which helps build a kind of unstructured knowledge base. The other reason is that, at least on ChatGPT, chat does not consume usage limits #ForNow. ChatGPT work and Claude - both chat and work - consume usage limits. Weird that there’s a “make a lot of money” button and nobody’s pressing it (take your SaaS, make it headless, let agents use it, charge per interaction esp for enterprises). Thariq AI is accelerating discoveries in cyber (definitely) and maths (reasonably) but not as much in algorithms. METR “Match your prompt style to the desired output.” Clear guidance from Anthropic that “The formatting style used in your prompt may influence Claude’s response style.” OpenAI says something similar - adapting implicitly to the user’s tone. But this is not a very strong signal - examples are better guides. Why model routing must be in the harness. Makes perfect sense. “Only the harness can judge when a model switch is worth the cache miss.” I’m sure some popular harness (like OpenCode, Codex, Claude Code) will enable an “auto model” mode that’ll pick and change the model by itself by the end of the year. Microsoft Print to PDF can, sometimes, generate PDFs with no highlightable or selectable text - all fonts get converted to paths. A crude solution is below. This is a poor solution but often good enough for an LLM to process. (Of course, if you’re passing it to an agent, you could just upload the file and it’ll figure it out.) sudo apt install ocrmypdf tesseract-ocr ocrmypdf --output-type pdf input.pdf ocr.pdf pdftotext ocr.pdf - When my train neighbor started talking to me (asking personal questions but was self-aware, rambling but was partly interesting), I asked if he was an extrovert. He said “No”. People who talk a lot can still be introverts if they’re: socially competent (like me at work) in “performance mode” (like me when I’m on stage) are high energy and engaged by topics (maybe him - or me when, like now, when I just HAVE to tell the flight attendant Ollama + Gemma 4 + Pi answering a psychology question is a delight!) ambiverts (maybe him) not self-aware and are mistaken (maybe him) ffmpeg can embed subtitles. ffmpeg -i video.webm -i subtitles.srt -map 0:v -map 0:a? -map 1:0 -c:v copy -c:a copy -c:s srt -metadata:s:s:0 language=eng -metadata:s:s:0 title="English" -disposition:s:0 default output.mkv adds subtitles.srt to video.webm and creates output.mkv with embedded subtitles. Note: On VLC, MKV works better than WEBM if you want to embed subtitles. On the browser, you need to use the <video> tag with a <track> tag to display subtitles. ffmpeg can burn subtitles. ffmpeg -i video.webm -vf "subtitles=subtitles.srt" -c:v libvpx-vp9 -crf 30 -b:v 0 -c:a copy output.webm re-encodes the video with subtitles added to the video. ffmpeg can offset subtitles. For example: ffmpeg -itsoffset 10 -i input.srt -c copy output.srt creates output.srt with subtitles starting 10 seconds later than input.srt. When I hear my father’s tales from his childhood, I’m struck by how much India moved forward in half a century on child mortality, consumerism, and communication (mobiles). Also surprising are what feels the same: legal system, travel (trains made it easy), food (tasted better, then), entertainment (theatres made it easy), gardening, education (scholarships made international study more accessible than I thought), I asked ChatGPT how I adapt my message based on the audience. It discovered that I tailor messages to the audience’s (A) Objectives (B) Examples (C) Expertise - e.g. tell vs ask (D) Risk appetite. But what’s distinctive is that I often surrender, i.e. I don’t defend my view, but drop it and run with their framing. “People with taste are picky. The only way to make money is by satisfying those who can’t discern quality.” Adrian Hanft. I’ve been telling people that taste is our differentiator against AI. And yes, it’s a fickle differentiator. I mean, how do you build a taste that thousands or millions will adopt? Or… is taste marketed more often than organically adopted, in which case, persuasiveness matters more than taste? But either way, unless most people disagree with you, you’re building conformity, not taste. On a flight, I tried ollama launch pi --model gemma4:e4b-it-qat. It’s a reasonably sensible model. Power consumption is high, though. I was at about 8 watts with ~7 hours of battery life. While running, power spiked to ~50W (1.5h) and settled down to ~12W (4h) when idle. The llama-server process consumes some CPU/GPU even when idle, but I couldn’t get it back to the ~8W even after ollama stop. (It eventually did return to 8W after an hour. Not sure why.) When I tried again on 21 Aug, it went up from 8W (8h life) to 28W (3h life) and back to 8W, so looks like when idle, it doesn’t consume power. I look forward to using local LLMs more! Pain is good. Struggle is good. Stretch is good. Not new. But worth reminding, worth seeking. T3 Code is a coding agent orchestrator. It lets you “remote control” multiple coding agent sessions across systems. The ecosystem of tools around coding agents is growing. Observability, e.g. AgentsView, is one such area. Questions I was asked Week ending 23 Aug 2026 ...
Things I Learned - 16 Aug 2026

This week, I learned: psub is a neat fish option to treat command outputs like file inputs. E.g. diff (sort a.txt | psub) (sort b.txt | psub) More anchor points on how much text to ask AI for: … in 200-300 words (about 1 book page) … in ~1 A4 sheet (~500 words) … in ~3 minute of conversational Grade 8 reading (~500 words) I usually log things in a single file rather than split things into yearly, monthly, etc. A single file is more portable, scannable, and, for human logs, gives a feeling of accomplishment. I split when the file gets so unwieldy that it actually hurts - which is a good thing because it means I’m actually using it (maybe?) - and splitting beforehand may be good planning but is also premature optimization, adding friction to a nascent, fragile process. (This idea is pretty generalizable.) Claude models launched after 2 Aug 2026 “weaves an imperceptible watermark directly into the text itself. You won’t see it, and it doesn’t change the meaning, quality, or readability of Claude’s response.” How Claude marks AI-generated content. VS Code has built-in dictation. It uses nemotron-3.5-asr-streaming-0.6b by default #ForNow, and it’s pretty good. I expect I’ll use it a lot more, since most of my typing is in VS Code anyway. Ctrl + Alt + V toggles dictation. Dictation is also supported in the terminal and is trained to recogni I had an interesting moment today when I asked ChatGPT to identify which of my ChatGPT conversations were the most effective. I gave it access to my computer and it started using the browser to scrape itself so aggressively that I stopped it from it banned itself! GeoLibre looks like a full-fledged GIS. It’s open source and runs directly in the browser. When installing tools with mise, if it messes up the platform, you can explicitly specify it. For example: mise use -g 'github:pranshuparmar/witr[asset_pattern=witr-linux-amd64,bin=witr]@latest'. Mise Docs I saw this snippet from Claude Code: await Promise.race([document.fonts.ready, new Promise((r) => setTimeout(r, 3000))]); That waits for up to 3 seconds for the fonts to load. Didn’t know about Promise.race() before. It’s different from Promise.any() in that .race() will return the first result while .any() will return the first success. Measure the verification / follow-up tax in your AI work. AI does things fast. You have to take the next step. It helps to tag items with how long they’d take to verify or action. We do for specification, because we have to do that now, before telling AI. But I typically ignore the deferred tax. A theme is emerging: “Human attention needs reciprocity. If you ask for someone’s attention, first demonstrate your own effort.” Example: “people really don’t like when a coworker’s chatgpt contacts them asking for help with a task, even when they’d be perfectly happy doing that same work if asked by that coworker.” Greg Brockman Questions I was asked Week ending 16 Aug 2026 ...

Things I Learned - 09 Aug 2026

This week, I learned: Kamakoti: “Entry (to the course) is relatively easy but the exit is extremely hard”. Generalizing, quality is determined by the exit criteria; loosening entry criteria is just openness / diversity. The Hindu “Once I have a persistent system that I pay to keep thinking, learning, and acting 24/7, I think that will decisively look like AGI.” - Dan Shipper AI has expert-level capabilities in many (increasing) tasks #ForNow. If your edge is OUTSIDE of those, use AI for other tasks you couldn’t do before, insourcing or expanding horizontally. But your edge may be short-term - so move upstream / specialize. Your competitors’ edge may be short-term, too - so plan to attack. Analyzing Anthropic Economic Survey, it looks like people in rich countries are asking Claude for advice (explain this spreadsheet) while poor countries are asking Claude for output (build this website) #ForNow. Maybe because rich users already have tools / people that create output for them? Humans can’t define all laws of language but LLMs have learnt them anyway. What if there are laws of nature that humans can’t understand but AI can? Actually, this is already true of black-box models (loan approvals, weather forecasts, …) where benefit/control > understanding. But as data & compute scales, this might “solve” entire fields like psychology, economics, etc. Noah Smith In each area, there might be a limit to how much intelligence is possible/useful. For example, we’re pretty good at recognizing food and emotions - there’s not much benefit / possibility of more intelligence. But we can copy and share this intelligence - and that might help more than we think. Noah Smith The ChatGPT Dropbox plugin can read Markdown files if you specify the path, but can only read PDF, Word, PPTX, Excel, etc. when searching. It cannot update files on Dropbox, but can add and delete. #ForNow Given how long agents run without mistakes, verification is increasingly “drift correction”. You can’t spot it easily. Learn writing specs that EXPOSE drift. Build and test against “oracles” (verification systems). Reduce cost of error. Permissions, in the context of multiple agents, is complex. If agent A can read my email but wants to consult agent B, can B see the email? We’d need to make permissions pretty specific, like: principal: “anand” agent: “agent-17” purpose: “insurance-coverage-check” allowed_data: [“email:read”, “dropbox/notes:read”] allowed_effects: [“email:send”] audience: [“anand”] expires_at: “…” delegation_depth: 1 After struggling to understand where to apply loop engineering, here’s my guess. If you have a metric (or something really well defined) that you want to optimize, and a single agent iteration isn’t enough, loops are a way to get there. Kaggle competitions, benchmark optimizations, etc. are examples. This means that any complex system that you can benchmark (or at least where you can robustly compare results) is loop engineerable. (This means that the ability to benchmark, and using agents to benchmark, will become a key ability.) Ontologies, state machines, etc. can be used to create verifiable systems, e.g. nodes become states, relations are valid operations. That’s great for building verifiable systems (leading to things like LEAN). Of course, a key skill will be knowing what to put into the state, what relations to allow/disallow, what reflects reality well, how it might evolve (e.g. temporal graphs), how that might change in the future, etc. Having said that, this is just creating a neural network of sorts - so according to the bitter lesson, we should just toss data at an agent and have it build a graph (or not) as required. BTW, I shared this with a bunch of speakers at Data Hack Summit who were speaking about knowledge graphs. There was silence for a while. Then, gently, they all agreed. Some people blab. Interrupting with a question is a good diversion mechanism. Some blab even after that. Exiting politely is both wise and surprisingly un-rude. To control your mental state, breathe slowly. 5–6 times/min for five minutes (that’s longer than I thought was needed), exhaling slower than you inhale. PubMed Once a ChatGPT conversation uses a developer plugin, #ForNow it refuses to use other plugins. So, if you need to use a GMail plugin AND a plugin you built yourself, you’d need to use the GMail plugin first, get stuff into the chat, then switch over to yours. I suspect conversations with developer plugins might not be accessible when using other plugins, too - but that’s untested. There’s a jagged edge of AI adoption as well, not just AI capability. Several organizations limit users to weaker agents #ForNow (e.g. only Microsoft Copilot or Gemini). Many have never seen the power of Codex or Claude Code on their systems. It’s hard to convince them that AI can do much more than they think. There’s a “data engineering” industry incentivized by structuring data. This is partly enabled by poor enterprise agent adoption #ForNow (e.g. Microsoft Copilot). The sequence works like this: “AI does not solve something with the data it’s given. Let’s structure the data. It solves it. Therefore, we need to structure data - all data.” The alternative which I believe is: agents will structure it themselves. I noticed that when you submit a prompt on ChatGPT, it changes the URL to https://chatgpt.com/c/WEB:... and once it starts processing it on the server, changes it to https://chatgpt.com/c/... giving it the actual conversation. So, if you see a WEB: in the URL #ForNow, make sure you copy the prompt before reloading the page - because it hasn’t been saved or sent to the server. I assumed inflammation was mostly a bio/chemical process. Looks like neural signals are involved, too, and electrical simulation can control inflammation. This leads us to a new territory: bio-electrical medicine. The Anthropic Economic Index indicates that, on average, if you prompt Claude like an 8th grader, it responds for a 9th grader. Does that mean (a) that more sophisticated prompts get a better response, and (b) if you repeatedly meta-prompt, you increase the sophistication by about a year each iteration, and hence can get very smart prompts by just getting out of the way and with little hope of understanding the question? This might actually make sense if AI will action the result without you needing to understand. The geometric mean is always less than or equal to the arithmetic mean. This is why a “smooth” 8% return is worth much more than a “wild” 8% return. @lumenxbt Quantum cryptography can give us unclonable encryption, i.e. if someone copies a message midway (or you publish it), you can’t independently decrypt both. We knew how to do this in 2020. Now, ChatGPT helped “indistinguishable security”. Between 2 messages, people can’t figure out (e.g. from the length, or other attributes) which message is which. Gemini Agents can record network requests into a HAR file and reverse-engineer an API for many websites. More efficient than browser control. dax The Anthropic Economic Index dataset is on Hugging Face - released quarterly #ForNow. The longitudinal analysis is likely to be interesting. BusinessCaseBench solved over 238 business cases with AI agents and they’re doing well and improving #ForNow. Not surprising. Frontier AI performance across the business disciplines OpenAI Presence shows a pathway for deploying agents. Deploy for a specific job, with only required access to knowledge and systems, company defined policies for approval, agent periodically reviews logs & escalations and proposes updates for testing and approval. A lot of work people are doing on ChatGPT is OUTSIDE their area of work. “… a substantial part of work-related ChatGPT use is from users expanding their role.” OpenAI Questions I was asked Week ending 09 Aug 2026 ...

Things I Learned - 02 Aug 2026

This week, I learned: I continue to be amazed at how efficient video codecs are compared with animated image formats. When compressing 38 PNGs, the final WEBM was smaller than many of the individual PNGs! 2343k: magick -delay 50 -loop 0 file-*.png file.gif 398k: magick -delay 50 -loop 0 file-*.png file.avif (slow) 284k: magick -delay 50 -loop 0 file-*.png file.webp 82k: ffmpeg -framerate 2 -i file-%03d.png -c:v libvpx-vp9 -pix_fmt yuva420p file.webm Please use AI by Shawn Smucker is the best guide I’ve read about where NOT to use AI. I need to be more mindful of this. gpt-transcribe is released at 0.45 cents / minute or 27c / hour. Gemini 3.6 Flash costs about the same ~27c. Gemini 3 Flash costs ~15c and that’s what I use today. Gemini 3.5 Flash Lite costs ~6c / hour but it follows my instructions very poorly. To benchmark this, I just re-run my transcribe_calls.py script on a recent conversation (that I remember well) with a different model to see if it’s clearly better or worse. No fancy benchmarking. Creating / maintaining formal benchmarks isn’t always worth it. ruff 0.16 is out and has a 350+ new default rules. I mean, who would check that functools.cache on instance methods has a memory leak? But its output is so agent-friendly that agents would just fix these on the fly anyway, so it does make sense. It’s another step towards code-writing becoming less accessible to humans. npm install --no-package-lock installs packages ignoring and without creating / updating package-lock.json. Useful for dev environments. Astral has published prebuilt GPU wheels for Flash Attention, vLLM, PyCUDA, and many others. One characteristic of good benchmarks is that they are easy to verify. I see a lot of comparisons of Fable vs Opus by having them generate 3D worlds (e.g. threejs, Blender, melt) - something that’s not trivial for agents, but evaluatable at a glance. Maybe it makes sense to open source the intermediate steps in ALL knowledge work, to make AI as good at it as with code? Arvind Narayanan Open-source software and culture is a historical accident. We take it for granted that not only are the outputs of software engineers’ creative work available publicly, but so are all of the intermediate steps (specifications, plans, mockups), tacit knowledge (StackOverflow, documentation culture), detailed process traces (issues, pull requests, bug fixes, code reviews), collaboration records (version control, project boards), and more broadly a culture of learning in public. This level of explicit description would be completely alien in most professions. ...

Things I Learned - 26 Jul 2026

This week, I learned: Thinking traces vanished in ChatGPT Work (or did they never exist) and seem to be vanishing in Claude. Not sure if it’s because Chinese models are using the thinking traces as signals. ChatGPT Skills is available in the Plus plan. This was available to Enterprise and Edu, but since I saw this on ChatGPT just today, I guess it’s a recent feature. Peter Gostev compares Opus 5, Fable 5, Kimi K3, GPT 5.6 Sol, GLM 5.3, etc. on a variety of visual tasks in this video. The most intruiguing prompt I spotted was: “I would like you to research the most interesting, impressive dataset where I would learn something about the world and you can visualize in the most creative way, making it something completely unexpected. Then create the most elaborate version of it possible.” This apart, I got the general sense that Opus 5 is quite good at visualization and design, perhaps even better than Fable 5. After reflecting on Knowledge graph construction with Claude, I believe that knowledge graph construction is roughly: “Tag each document with people, place, org, event, etc.” - and it’s good enough for agents to use. Increasingly, the real question isn’t “What interesting things you doing with agents?” It is the followup? “What lets you do that (when I can’t)”? For example, Naveen asked me, “Can I set up your email reply agent?” I said, “No, you don’t have transcripts, blogs, notes, or exports like I do.” LinkedIn lets you save a profile as PDF. While it formats text reasonably well, it doesn’t preserve newlines in the “About” section - so what looks good on the browser looks terrible in the PDF. Such PDFs are sent to interviewers, making it a bit of a bad experience for the interviewee. (Of course, it could also be a signal to see how well interviewees pay attention to small details like LinkedIn PDF formatting.) The ability to measure an outcome is (and has always been) important. It lets you capture value (outcome pricing) when you control the outcome, or de-risk (insurance) when you don’t. But what might be new is that metrics are outdated at an increasingly faster pace - so (a) setting an expiry date and (b) knowing if it’s expired have become important. I wasn’t using AI to reply to emails because (a) it didn’t have enough context and (b) it didn’t write in my style. I spent a few months making sure I give them context and style guidance. Given the current intelligence of models and my email reply prompt, I’m now happy for AI to answer my emails. My learnings based on YC request for startups Fall 2026 - which probably means we’ll see many more startups in these spaces. Here are my takeaways: Self-Maintaining APIs: Nice idea. When a service changes an API, they share an agent/skill that can fix YOUR code to upgrade the API! AI-Native Compliance Infrastructure: So, compliance becomes cheaper => MORE and STRICTER regulation. Licensees become valuable (AI rollup). Private regulator feedback becomes valuable. Compliance companies will themselves get regulated (like auditors). Multiplayer AI: Claude Tag is a step in this direction. WhatsApp’s @Meta is too. I expect most chats will allow AI as participants. Most collaborative software, too - GitHub, JIRA, Figma, GMail, HubSpot, maybe even VS Code, Office/Notion, Chrome, Games, … A Cloud for Small Software: Systems of record are likely to be safe, but software AROUND it will explode into tiny tools. Access control, ratings, … is what’ll be important, not generation / managing them. Grok 4.5 took 14 iterations to write an essay about Cheese before Pangram declared it “Human”. Pangram is increasingly becoming the new Turing Test. Rahul Notes from a Claude Code interview with Simon Willison: Fewer examples. More examples don’t help Fable and Opus 4.8. “… removing examples was extremely helpful, because it was just more creative than the examples we gave it.” Fewer hard constraints like “fewer “do not do this” instructions, because that’s a very strong impulse for Claude, and especially if it conflicts with user instructions”. “Do X when …” or “Do X because …” is more helpful. Fewer tools. A few general-purpose tools work best. Fewer sandboxes. Auto-mode is safe enough. Sonnet judges every tool call with context, enabling dynamic permissions. Fewer software / integrations. Use Claude Code itself as the software / integration layer. Fewer components. Memory is just a Markdown file in the right folder. Fewer interventions. “… given a COMPLETE definition of a task… does Claude make the right decisions” Fewer decisions. Fewer reviews. Generation is cheap, so let people who need something get there immediately, as long as a good AI judges and its reversible. “We actually have a different system prompt per model now”. Claude Tag is next evolution of Claude Code: Multiple people interacting per channel, working with Claude on a task. (Claude tag contributes to 65% of our PRs) Apache Ossie is a YAML standard for dataset metadata. If adoption grows, it could be a useful machine and human readable way to document and describe datasets. Databricks, Snowflake, Qlik, are part of the group. If more join, this could become a useful standard. An interesting technique to build an efficient video understanding agent. Use AI to generate transcripts with timestamps. Have it identify key moments, e.g. where the presenter explicitly (“as you can see”) or implicitly (“these two cells”) flags something on screen. Extract up to ~50 of the most important frames. claude-video SKILL.md Cangjie Skill converts books, videos, etc. into AI skills, like Poor Charlie’s Almanack skills. However, since AI has already read most of these, the value of this (compared with “Apply principles from Poor Charlie’s Almanack”) is unclear. Alt+Shift+Right Arrow expands selection in VS Code, and Alt+Shift+Left Arrow shrinks selection. That’s useful in Markdown, HTML, etc. to select sections. Since Jun 2026, this also lets you select a specific Markdown table cell, row, or entire table. Also, since Jan 2026, double-clicking just inside quotes or brackets selects the entire contents inside. I analyzed the Claude Code session of a domain expert building an enterprise application without knowing how to code. Here’s what I learnt about expertise: An expert can instantly see errors / misses and their causes - amateurs can’t. An expert can point to specific nitty-gritty details - amateurs can’t. An expert knows what’s possible/easy and what’s not - amateurs don’t. An expert has strong opinions that’re often right - amateurs don’t. Claude gave me $100 credits until 19 Sep and Fable 5 will now consume those. My queries cost about $1, so I have ~100 queries to exhaust in ~60 days. About 1.5 Fable queries a day. That’s about what I normally ask Claude, so I think I should just stick to Fable 5 until my promotional credit expires - it’ll expire otherwise anyway. But using it with Claude Code is quite expensive ($7 is common.) I asked ChatGPT to analyze an MRI report and compared it with the doctor’s. Problem: they agreed on what problems most people in that age group face; they disagreed on things I have no way of validating! Maybe it’s best to use a doctor / radiologist to read the MRI, diagnose, and prescribe - but use AI to translate and cross-check (e.g. is this a typical age-related problem, is this the standard treatment, etc.) Both ChatGPT and Claude subscriptions offer an OAuth based coding agent API access - Codex SDK and Claude Agent SDK - which is how coding agents like Pi, OpenCode, etc. are able to authenticate and use the subscription. This means that anyone can build their own harness using existing subscriptions. ChatGPT A useful way to improve your SKILL.md files from others’ skills or prompts is: “What cool prompting / SKILL.md techniques does this have?” “Based on my usage patterns and objectives, which of these have the highest impact (provides highest uplift to my chats) x frequency (relevance)?” “Review all my skills. See what applies where. Filter what has HIGH impact. Draft the full diffs for the relevant skill files.” GPT 5.6 Sol attempted the Cycle Double Cover Conjecture. An interesting learning from the prompt is how they listed tempting outputs that APPEAR to satisfy this request, but would not actually, and told it to avoid them: “Use adversarial agents throughout: every candidate proof must be checked for exact-two multiplicity, repeated-edge closed trails masquerading as cycles, …” Questions I was asked Week ending 26 Jul 2026 ...

Things I Learned - 19 Jul 2026

This week, I learned: Writing is slightly, but only slightly, better than typing (for adult learning.) One factor is that typing is faster, so many people take notes verbatim, summarizing and thinking less. ChatGPT + Claude Graphology for personality is pseudoscience. ChatGPT + Claude When I decide to spend time, or someone says “Let’s do X”, it’s worth checking: is this something AI can easily try, and is it clear to verify? If so, reinforcement learning loops could make AI good at it, making it a depreciating asset. Studying how to live in an AI world is exhausting. (Not as bad as my MBA days, but not as easy as my data scientist days, either.) It requires me to make a larger mental shift, i.e. change my perspective, than I have since 2000, and that feels like work. Both nl FILE and cat -n FILE add line numbers to files, but nl skips blank lines by default, cat doesn’t. After using rtk for 2 months, I’m slightly downgrading it. It saves tokens but agents mess up shell commands when using it. It’s still probably a net saving, so I’ve changed my AGENTS.md from “Always prefix with rtk” to “Prefix supported, high-output commands with rtk… skip for bash builtins, pipes, loops, etc.” I find 🔴🟡🟢 convenient status indicators in my notes. Similar ones are: 🟥🟨🟩, ❤️💛💚, 📕📙📗. I’m not fully convinced by: 😄😐😞, █ ▒ ░, ↑ → ↓, ▁▂▃▄▅▆▇, ■ ⬔ □, ● ◐ ○, ⚫ ⚪ 🔘, 🌕 🌗 🌑, etc. though they might have their uses. Model updates means a SKILL.md and a plugin review / update, e.g. with GPT 5.6 Sol. So, like with any open source repo, use from people who update it regularly and benchmark it and version control it by model. I asked Gemini 3.5 Flash thinking: “Which of our employees have worked on Microsoft PowerApps? Search @Google Drive and @Gmail”. It found one employee and a referral in under a minute. I asked ChatGPT with GPT 5.6 Sol with gws access. It found 3 more, plus 5 possibilities, in 12 minutes. Truly a rottweiler. Parallel Search Turbo seems like a pretty good search API, especially for agents. Low price, high speed, and maybe good quality. #ForNow ChatGPT Group chats in ChatGPT will probably get deprecated #ForNow. What I learned from benchmarking my Ideation Protocol skill extensively: Once you know the rubric, models can easily create a good prompt to optimize for a known rubric #ForNow. So rubric design matters more. ⭐ Rubric design is really knowing what you want/need. To do this, iterating on output matters. Position bias is real #ForNow. Always check if an (P, Q) comparison matches a (Q, P) comparison. Models are still biased towards longer content, and potentially towards their own output #ForNow. How to optimize a prompt or skill: Research and figure out what you really want, first. Then, ask a smart model for a prompt that optimizes for it. Benchmark only if you’ll use it a lot - it’s still a lot of work, and meta-prompting does a good job #ForNow. gbrain skillopt might be premature optimization. You can use GPT 5.6 Sol in Claude Code #ForNow. (But what’s the point? Harnesses seem to be working better with their own models #ForNow.) Our clients keep saying “We need to build a data lake” or “We need an enterprise data strategy.” I keep telling them, “No, agents can do it for you.” What I missed is: technology is the smaller part of the problem. Finding who has what data, getting access to it, and sorting out permissions (“governance”) is the bigger part. Giving agents expert task-specific, testable procedures seems better than expert roles or mental models #ForNow. But benchmark in any case. ChatGPT Python 3.3 introduced str.casefold(). It performs more comprehensive Unicode caseless matching than lower(); 'Straẞe'.casefold() becomes 'strasse'. (🟢 Unicode case-folding is standardized.) contextlib.closing(x) calls x.close() when its context exits. (⚪) In a dataclass, use x: list = dataclasses.field(default_factory=list), not a mutable literal default. (⚪) I learnt these while reviewing Codex-generated Python—illustrating, rather than proving, that reviewing AI-generated code can teach and catch errors. (🟡 Review remains useful across tooling. Review 2029.) “Do not discriminate against intelligence—artificial or otherwise” is a rhetorical value judgment, not an empirical conclusion. (⚫ Rhetorical value judgment, not testable. Review now.) Here’s a nice idea from ChatGPT. “When itching to correct or clarify, FIRST restate their position to their satisfaction. ‘Did I get you right, fully?’” This emerged from the prompt suffix: Based on your research, and my past conversations, what are the top areas where and how (specifically) I can apply this principle on myself and others to maximize impact? Automated evals can catch stuff humans miss. And vice versa. And given how many evals we create, we need automated evals to be written in an easy-to-review way. Do Automated Evals Work? The BINEVAL paper reiterates that a bunch of Yes/No binary questions beats scales or ratings for many benchmarks. You know exactly how to grade and WHY you got a certain score. This is more reproducible and easier to learn from / act on. When asked “How long will this software take?” models typically provide estimates assuming human speed #ForNow. Maybe they haven’t been trained enough on agentic timelines. So, when my colleague got a 2-4 week estimate which he was able to solve in hours, it was a surprise. (But, of course, it’s best to verify before promising speed.) SKILL.md dramatically lowers the cost of learning a skill (since you don’t learn it - the agent does). That means that the value of creating skills is much higher - hundreds can use what you create (giving you recognition, if not money). I think I’ve underestimated the number of skills people will have available (I thought dozens - but it may be thousands #ForNow) and the number of skills people will create (I thought tens of thousands - but it may be millions #ForNow.) A Wikipedia (community curated, verified, high quality catalog) of skills might emerge #ForNow, if it hasn’t already. Tacit knowledge is often just un-measured knowledge. Once I put a sensor on the bellboy’s hands at The Curzon Court, AI can figure out how he opens the door with the key and why I can’t do the same. The subset of tacit knowledge that’s AI-resistant is where attempts are expensive (“How to negotiate a merger” rather than “How to open a door”) and feedback is slow/vague (“Does the client trust me” rather than “Did the door open”). The fact that Composio has ~20,000 tools is a market signal that connectors are commoditizing, and are a depreciating asset #ForNow. A weak model needs a forgiving harness - which ends up slowing down model learning. Stricter, accurate verification environments are better for fastest model learning. ChatGPT Work lets you run for longer, faster, install plugins and skills, host a website, etc #ForNow. It’s somewhere between Chat and Codex. It consumes Codex limits - something to watch for (since chat limits are quite generous). Codex temporarily removed the 5-hour usage limit. Tibo. So, since I have 3 banked rate-limit resets #ForNow, I can, in theory, use 4 full weeks of Codex usage at one go. Reality: I don’t have problems large enough for a SINGLE week’s consumption! From what I see of the State of AI Design and State of Prototyping, Figma is way ahead of competition #ForNow, e.g. Adobe, with Figma Make and Weave. I was also surprised how popular Cursor is (#2 behind Claude Code #ForNow). It’s also interesting that designers are coding directly #ForNow, using Figma just for edits / steering. But many research tools (note takers, survey analysis/research, etc.) will likely get eaten up by AI coding agents #ForNow, given how much designers are building their own tools. Questions I was asked Week ending 19 Jul 2026 ...

Things I Learned - 12 Jul 2026

This week, I learned: How to become an applied AI engineer is a concise, well-written, and suprisingly current summary of what AI engineering is. Xinjiang seems to be China’s Kashmir problem. Not quite, but similar. Analogies for how forward deployed engineers work: It is like a food truck that brings and serves home food while building a kitchen and restaurant around it. It is like setting up a field hospital: patients are treated from day one, while the equipment and procedures are built around the live work. Froghoppers excrete ~300x their weight daily. ChatGPT There’s a growing shift away from AI-written commit messages, e.g. Kenton Varda. I compared my human written commit messages vs AI-generated commit messages and the AI-generated ones are less helpful. Finally, GPT live gets an update and the new speaking model can delegate to GPT 5.5 when required. I tried it once today, to plan for a teacher workshop, and it was fairly good. It tends to begin with “Hmm” like it’s thinking, which feels comforting. Using a Unicode character like 🟢 is unusually low-risk across file systems today. It works well across OSs, mobile, ZIP, attachments, file share systems, etc. Some old apps might have trouble, but for storing and sharing, it’s fine. I’ve been using Unicode symbols like these a lot in my notes, and extending to file names feels like a natural next step. Though swimming gets the most Olympic medals (11%), for a country chasing its first medals, 78% of first-medal breakthroughs came from Athletics, Wrestling, Shooting, Boxing, Judo, Weightlifting, or Taekwondo (which are 44% of medals) - where single athletes can win without a support ecosystem. ChatGPT JMFL accidentally emailed several people a letter intended for their brokers. It roughly said: “Many of you are recording client calls. That’s a regulatory risk. If you keep doing this, we’ll hold your payments, even fire you.” Several Smart TVs have software that let your TVs act as proxies for data collection companies. Include Security MapDraw is a convenient tool to annotate maps (e.g. routes, boundaries, places) and share or download it. There seems to be no way to edit the “About” message on WhatsApp Web. Though the help suggests steps, and the “About” mood/status is visible, there’s no way to edit it. (Editing on the phone works.) Cloudflare optimised a reader component by sometimes letting the input buffer fill fully. This inadvertently introduced a hard to reproduce race bug because the producer would close the socket if the buffer was full. The producer bug was old (it didn’t check if a flush succeeded or not) but was never visible since the readers never let the buffer fill in the past. Cloudflare A neofirm is a start-from-scratch AI-native business, e.g. Crosby’s AI-first law firm. An AI rollup is where a company buys small traditional firms and AI-enables them - like General Catalyst proposed. AI SaaS is selling AI agents to services firms. Give people free platforms and collect their data. Learn the supply-demand network patterns, what pepole value, and add value-added services. Claude Code checks if you’re working behind a Chinese corporate domain - somewhat sneakily - by changing an apostrophe or slash in the date to visually similar Unicode. Claude Code Is Steganographically Marking Requests You can use the Kaggle CLI via Codex to solve Kaggle problems. (AutoKaggle automates it - but is 2 years old.) But, like GitHub bounty hunting bots, we will probably have a Kaggle bounty-hunting bot ecosystem - maybe already do. OpenSubtitles2024 and subscene are large pre-AI subtitle datasets with a 2024 cutoff. IndicDialogue is a 7.7K OpenSubtitles snapshot of Indic language SRTs. The OpenSubtitles API lets you search by IMDb/TMDb ID and is up-to-date. A soup spoon is better than a table spoon (for soup), though both carry about the same volume, because you can fit a soup spoon it fully into your mouth (a table spoon is too long) and this reduces spilling. Here’s a sign of accelerating AI progress. I used to critique outdated techniques by saying “This feels like a 20th century approach.” Then “This feels like a 2010s solution.” Recently, “This is SO 2025-ish.” Now, “That’s Q1 2026. It’s Q2.” The 7-day week emerged from the Hellenistic planetary week and the Jewish week (not astronomy based), which Rome adopted, then spread by several routes to India, China, and worldwide. Unlike the astronomical year and month, the week is just a convention. Egypt, China, and Athens grouped days in tens; Etruria and Rome used 8-day market cycles; West Africa used varied cycles; Java used five days; Mesoamerica used 13- and 20-day cycles. Gemini I met an ex-photographer and learned that photography is another profession where technology (mobile cameras) squeezed the middle. Generation (taking good pictures) became cheap. Value moved upstream (direction), downstream (selection, editing, album design), and into niches (forensic, industrial, sport/event photography). Looks like Claude favors Claude Code. Might not be intentional, and just a result of training more on Claude Code data, but it does look like a network effect that could weaken open harnesses. Armin Rocher Questions I was asked Week ending 12 Jul 2026 ...

Things I Learned - 05 Jul 2026

This week, I learned: ⭐ How to teach so people learn better. Make them do > Show > Tell. Workshop > Demo > Slides. Let them ask, try, struggle, and commit first; explain next; help last. But only when they know enough to get part-way. Make problems CONCEPTUALLY hard (not in language, visual, or procedure). But make sure instructions are clear. Test their learning with a NEW case, immediately. Measure learning. Can they recall it LATER, apply it ELSEWHERE, explain WHY, and know when they may be WRONG? Vogue runs an “In the bag” series where people pull stuff out of their bag, and audiences watching feel they KNOW the person. Depending on the setting, we might be able to help people “know” each other by curating several items. Here are a few ideas. Physical: Bag, Wallet, Fridge, Drawer, Keychain, Remembered phone numbers Mobile: Battery usage by app, Recent emojis, Text prediction for “Honestly, I just want to…”, Autocorrect dictionary, Alarm labels / reminders, Saved Wi-Fi, Blocked/muted contacts, Contact favorites, Contact names, e.g. “Mom ❤️” vs “DO NOT PICK UP”, Device / Wi-Fi names Laptop: Open tabs (count, age), Recurring calendar events, /Downloads, Photos, Email drafts, Subscriptions, Kindle highlights Ownership and connections come from attachment, which can be created. If you name something, touch something, contribute to something in any way, it becomes yours. When people contribute to someone else’s work and discuss it, they build a connection. According to both Claude and ChatGPT, if you had to pick one model for ideation / brainstorming, it might be GPT 5.5. It’s better for divergent generation: the broadest, most exhaustive pool of usable ideas. Fable 5 is better for deep creative judgment: reframing, finding structural flaws, recombining ideas. Claude Code supports rules which are exactly like a CLAUDE.md but support a paths: YAML metadata - so they’ll be read only when Claude Code is reading those paths. If you have a SKILL.md that explains how to do something and you only need its outcome, then move it to a sub-agent (e.g. fake data generation, tool failure logging). Use SKILL.md for instructions that need to be woven into a task, e.g. memorable explanations. The key bottlenecks in running an agent /loop are (a) imagining higher order problems and (b) defining a measure of success / progress. Long tail -> sell options. Black swan -> Buy options. That’s a roughly accurate summary. The trouble is, we don’t always know which tail we’re in. So, sell only if you can afford one hit. ArchiveBox lets you view pages / RSS feeds offline. uvx --from git+https://github.com/ArchiveBox/ArchiveBox.git@dev archivebox works, and config / tools are stored in ~/.config/abx/. The installation didn’t go very smoothly and the whole thing felt bloated, so I abandoned it. I use monolith -I -e $URL to download a page as an offline single-page HTML. Combined with uvx feed2exec I can archive RSS feeds for offline reading. That’s easier than having to open Feedly - I just mark read files with a x at the front and keep reading. The downloads are slow (~3 min/feed) and large (5 GB for 15 feeds, 5MB median feed size) because they embed videos and all images/files, but I can safely delete what I’ve read or will ignore. ChatGPT Project Injection as Role Confusion is a very well written paper (blog-post style) that says the key to tricking LLMs is to confuse them about WHO wrote a line. Just adding a “User: " in front of a line makes it more likely that LLMs think it’s a user. Even when test is written in the style of their system instructions, they fall for it - irrespective of where the content came from. This makes GEO more effective, too. Also, the last section “8. Open Ideas for Roles Research” is a fantastic read on LLM psychology (or rather, neurology). On The AI Compass I am The Podcast Bro. Patron saint: Lex Fridman. “You listened to a three-hour interview with an AI researcher and now you have opinions. Strong ones. You’re long on compute and short on regulation, and you’ve said ’exponential’ more times this month than a calculus teacher. Love is the answer, and also AGI.” Impact: +5.9. Valence: +4.1. Since Nano Banana 2 Lite isn’t as good as Nano Banana 2 and about half the price, I wouldn’t switch yet. Claude Sonnet 5 is out. Fable 5 will be released soon. GPT 5.6 is still on probation. Codex has a Record and Replay feature for Mac that lets you do something, records it, and learns from it. Very useful for non-developers. It’s like recording Excel macros, which unleashed a lot of power for me when I didn’t know Visual Basic. Claude Code Artifacts lets Claude Code live-publish a web page and share it securely. The “live-publish” part is the interesting thing. Claude in a /loop can now become the app that updates a “dashboard”, a live feed/story, a self-evolving app, … and so much more. (This feature is only available for Team/Enterprise but the idea is universal.) Tau, like Pi, is a minimal coding agent. τ = 2*π. It shows what it does very transparently, making it easy to learn how agents work. uvx --from tau-ai tau works seamlessly. Configs, logs, and sessions are stored in ~/.tau and you can log in via your Codex/ChatGPT subscription. Skills for Design Engineers has a useful animation vocabulary skill that converts vague animation prompts to precise animation terminology. X has an MCP Server but it’s meant for development/coding than general users. Setting it up for ChatGPT / Claude requires creating tunnels. OpenAI supports Secure MCP Tunnels that let ChatGPT connect to your machine securely. A very powerful feature. Unfortunately, this seems to need an organization - and even though personal accounts can still access it, it’s proven a bit more messy than I’d like to use. notebooklm-py is a CLI for NotebookLM. Unofficial and potentially unsupported, but it’s amazing how AI makes reverse-engineering APIs so easy. If you start a temporary ChatGPT chat and close it, it still runs in the background - but you have no way of going back to it (not even the back button) or seeing what it said/did. I know this because it was accessing my MCP server even after I navigated away from the chat accidentally. The code refactoring industry can go full swing now. “As an example of what AI can accomplish, Claude Opus 4.7 substantially reimplemented gotree—a bioinformatics toolkit with about 16,000 lines of Go and 40+ commands. We believe this same task would take a human engineer without AI assistance 2–17 weeks. Opus 4.7 solved it in 14 hours, passing 2,000/2,001 tests (99.95%), at a cost of $251.” MirrorCode A useful rule of thumb: Cloudflare tunnels are for links to share with others. Taiscale is for services (even non-HTTP) only your devices should see. ChatGPT date -d (date +-%wday) +%F is the most compact way to round down to the nearest Sunday. Avoid date -d "last sunday" +%F which, on a Sunday, returns the previous Sunday, not today. ChatGPT A useful way of controlling AI verbosity is word count. To do that, I need an intuitive sense of how much to ask for. Here’s my rule of thumb: one page of paragraph text on ChatGPT is 200-300 words. 150-200 if it’s mostly bullets. I can typically read 1-2 pages of output. So, 300-600 words is my limit. Google Labs launched a DESIGN.md spec to guide agents on a consistent design. The good part is that it aligns with the proposed W3C design tokens spec. But beyond that, I’m not convinced of the benefit. Atlassian’s DESIGN.md had mixed results. Claude feels it could go either way. I’ll give this a miss for now. Questions I was asked Week ending 05 Jul 2026 ...

Things I Learned - 28 Jun 2026

This week, I learned: Every Substack feed has an RSS feed at https://your.substack.com/feed. Substack help. I used this to scan my browsing history to identify Substacks I visit - and subscribed to Marcus on AI - an AI sceptic AI asked me to read about. Cloudflare let’s agents create temporary accounts so that they can deploy and test. Enables trial and error - a powerful capability. “They’re on mobile but this is substantiative enough to warrant length.” I spotted this in Claude’s thinking when prompting on mobile. So, if I ask Claude something on mobile, it will give me shorter responses by default. Clever design - but something to keep in mind. If I want some heavy thinking done by Claude, better to do it on desktop than try to give it conflicting instructions. Giant Permissive Image Corpus (GPIC) has 100 million Qwen tagged public images. Even as a simple searchable image catalog this has value. Jeff Clark - Import AI Ethan Mollick had an agent test his book summary against multiple LLMs as readers to find out how they would recommend it - and optimized. This is a great practical use of agents as consumers, and material for my When Data is for Agents, Not Humans workshop. kage is an easy CLI to clone websites and read offline. For example, kage clone https://simonwillison.net/2026/Jun/ -o ~/tmp/site --scope-prefix /2026/Jun/ --max-depth 1 clones all Jun 2026 articles from Simon Willison’s blog. Then kage serve ~/tmp/site serves it locally. While it’s easy, the only time I need this is on a flight, and in that case, a local RSS feed app works better. I’m using newsboat for that. To me, the clearest sign of AI writing from the Wikipedia:AI or not quiz was consistent paragraph lengths. I got the first 3/3 wrong, but once I used this heuristic, I got 6/7 right. Updated my LLM Smells. The files .git/info/exclude and ~/.config/git/ignore are also ignored by git, like .gitignore, but useful if you don’t want to commit them into the .gitignore file. For example, .DS_Store makes sense only for Mac machines, not each repo. .vscode/ makes sense only for VS Code users. Nelson Figueroa Justin Poehnelt, author of the brilliant Google Workspace CLI gws, was fired for it. There have been no updates for 3 months, but none may be required - it feels perfect. X Lore is a centralized version control system for large binaries. If you have large binaries (e.g. images, videos, …) that multiple people edit, it’s better than Git LFS or Perforce. ChatGPT Deno Desktop lets you use JS to build desktop apps. I tried it. It’s easy to install, compact to code, leverages familar web technology, and compiles to multi-platform binary. The binaries are a bit larger than I’d like, though - 80MB for a Hello World on Linux/Windows and ~70MB on Mac. Codex reported that You have 2 usage limit resets available. Run /usage to use one. This thread has context. After resetting, the next reset might be 7 days after the reset, though (source). After having a child, fathers are affected biologically, too. Testosterone drops, cortisol & prolactin & estrogen rise, the brain rewires for empathy and threat detection - and of course, there’s less sleep. These sometimes lead to “Paternal Postpartum Depression” - something I didn’t even know was a thing. The havoc kids wreak upon us! 🙂 Gemini With AI writing more code, formal code proofs are becoming more accessible. You just need to ask a coding agent to prove / disprove a function. You can use: Z3 to find/prove whether a counterexample exists. Best default. Dafny to prove that code obeys a spec. Best for real algorithmic code. Alloy to find loopholes in relational models, schemas, permissions, and workflows. Best for data. TLA+ to check whether stateful, concurrent, or agentic systems can evolve into a bad state. Best for systems / workflows. .. and there’s a long tail of these. Python is named after Monty Python, not the snake. I knew this, but forgot! Python now has multiple cross-platform app paths: PyInstaller and Nuitka for executables, Kivy, Flet, and BeeWare/Briefcase for GUI/mobile/desktop apps, and PyScript/Pyodide for browser/WASM apps - a route that became more serious because Pyodide-compatible WebAssembly wheels can now be published directly to PyPI. On the one hand, AI is writing code, so there’s no point learning Python. On the other hand, AI is writing code mostly in Python - so THAT’s what you need to learn more. I think we should teach Python using AI, that is, teach how to write and debug Python code using AI. That’ll end up teaching skills people will really need. Computational thinking = Decomposition + Abstraction + Algorithm design + Pattern recognition. In AI, that translates to = Framing + Context engineering + Orchestration (harness engineering?) + Verification design. Maybe I’d add Assetization / Systems. Questions I was asked Week ending 28 Jun 2026 ...

Things I Learned - 21 Jun 2026

This week, I learned: It doesn’t always take time to learn or convey things. (Early trust can be built instantly, e.g. vulnerability.) At first, experts don’t know how to make skills explicit. But trainer effort could compress 10X via evals, practice loops, and feedback. Learner elapsed time would compress less. Everyone has something worth discovering, but not every conversation is worth my time right now. So, meet new people with trust, attention, and good questions. Continue if there’s emotional / intellectual stimulation (surprising, interesting, moving, connecting, energizing, challenging), else exit warmly with respect. To avoid getting overwhelmed in ultra-interesting conversations, mental closure helps. During the conversation, pause, name, reflect, and close. “Wait, you’re saying X. I should do Y. I’ll reflect/act tonight.” or “Wow, let’s sit with that for 5 seconds. You mean X. I feel Y. I’ll drop.” After the conversation, summarize: “What struck me were X1, X2. I’ll plan Y1, Y2 and drop Z1, Z2.” Then take a short break. Setting "markdown.editor.updateLinksOnPaste.enabled": false might fix the delay / freezing (infinite spinner) issue when pasting Markdown in VS Code. The bottleneck to quality of AI output has shifted from model quality to harness quality (and this is not obvious to many people). It is important, therefore, to optimize harness usage rather than prompts usage, i.e. harness engineering over context engineering. I use ug --smart-case --bool -Q --sort=rtime to interactively search for text in files. It’s like VS Code search-across-files. Here are the shortcuts I find useful: Alt-g: Glob (filter files to search in) Alt-[ or ]: Decrease or increase context (lines before / after) Alt-w: Word match toggle Alt-c: Count lines toggle Alt-u: Ungroup - show lines once even if multiple matches Using AI for health seems to have reached a tipping point. Three people have pitched an idea in this space to me in the last three days. One is a managed personal health provider who wants to tie-up with hospitals to gather data to improve AI health advice. Second is an enterpreneur who wants to enable the Indian Govt to use AI to improve public health - given the low proportion of trained doctors in public hospitals. The third is a colleague who is uploading personal health reports, fitness data, DNA data, wearable data, etc. and suggest daily habits such as fitness, nutrition, sleep, medication, etc. to optimize health. Changing the topic (e.g. asking a question) instead of answering a question is powerful. It lets you decline requests, avoid sensitive topics, ignore boring ones, learn rather than teach, and bring in your agenda - all at one shot. I need to un-practice my 40-year habit of answering questions. (This is selfish. I forgive myself.) bolt.diy seems like a browser-embeddable coding agent. That is, you can add bolt.diy to your web page and have it build apps. That might be a pretty powerful upgrade to generative UI - where pages build themselves based on the user input. Codex has a few new features in the last few months. Codex can generate images and have voice conversations. /goal sets an overall session goal to avoid getting side-tracked. /side is like Claude Code’s /btw - for a side task while the main task continues. /resume lets you switch to any previous session. /keymap debug lets you edit the keymap and inspect what keystrokes the terminal sends. @ lets you mention files, directories, skills, and plugins. Ctrl+R works, lets you pick a previous prompt. Ctrl+O copies the last answer as Markdown. Hooks are stable. PreToolUse lets you log every tool, SessionStart lets you inject repo-specific rules. MCPs with readOnlyHint can run in parallel. codex doctor diagnoses environment issues. codex remote-control lets you remotely control Codex, making it a server. Codex Python SDK is better and you can have Codex run as a back-end more smoothly. To change others’ behavior, embody (not preach) it visibly and consistently, make it easy to copy, and ask without forcing. It takes time, though. ChatGPT Governance is how groups keep promises when things (people, incentives, environment, pressure) change. A simple way to explain what governance is to someone who doesn’t understand why governance matters, and guide on when it does not matter. Forward Deployed Engineers are the next evolution of data scientists, IMHO. AI can do data science. Data scientists will likely act as the “Human As An Interface” (HaaI) to business, proactively identifying and solving problems - a space business analysts traditionally occupied. Of course, business analysts will likely do the same without needing data scientists to help. But since AI replaces data scientists more than business analysis, I expect that the % of data scientists who become FDEs will be higher than business analysts. The value of data exported from software is high. For example, your email, social posts, CRM / HRMS / ERP dumps, service tickets, purchases, notes etc. These let you create a personal / organizational digital brain. Hence proprietary solutions will make exports harder and open solutions will emerge. To live-preview any publicly accessible Excel file, you can embed or link to https://view.officeapps.live.com/op/embed.aspx?src=YOUR-URL The Codex app can now use the browser much better and faster since last week if you enable “Dev mode” OpenAI. THis uses CDP - which is more efficient than screenshots - and is something Codex CLI has been doing for many months. In Codex, Claude Code, etc. you can submit a prompt while the agent is working to steer it, i.e. after it completes a turn (e.g. a tool call) it will factor in the prompt. You can also queue it. Neither of these is available on ChatGPT or Claude.ai, though it’s such an important feature. On ChatGPT, submitting another prompt stops the previous run and the agent continues with the new prompt. By default, git uses ~/.config/git/ignore or %USERPROFILE%\git\ignore as the global .gitignore. You can override that with git config --global core.excludesFile PATH. StackOverflow Questions I was asked Week ending 21 Jun 2026 ...

Things I Learned - 14 Jun 2026

This week, I learned: Overheard a journalist saying: “I can tell when humans are lying. There are no tell tale signs of AI lying. At least I don’t have any.” rdt-cli is a Reddit CLI. It uses a clever trick: it auto-detects installed browsers and extracts cookies (supports Chrome, Firefox, Edge, Brave). So, if you’re logged into Reddit on any browser, uvx --from rdt-cli rdt whoami automatically shows who you are logged in as. (The public-clis repo also lists other useful CLIs like twitter-cli, ) Currently, a $20 Claude Pro gives you ~$400 and a $100 Claude Max gives you ~$2,000 of API usage. For ChatGPT, the numbers are ~$700 and $3,500. SemiAnalysis When Fable 5 refuses to answer questions, here’s the message that appears: “Fable 5 has safety measures that flag messages on most cybersecurity or biology topics. They may flag safe, normal content as well. These measures let us bring you Mythos-level capability in other areas sooner, and we’re working to refine them. Send feedback or learn more.” I managed to trigger this once while researching an M&A acquisition target. Clicking on “Edit and retry with Fable 5” triggered Opus 5 again, twice. DNA codons (A, T, C, G) encode proteins in triplets. There are 64 triplets that map to 20 amino acids. Some like Leucine, have 6 codons. Some like Methionine have only one. Why? When creating genes, there’s a wobble, sometimes, at the 3rd codon. THe mapping minimizes that impact: small errors map to similar proteins. The more common proteins have more codons. There’s a lot of fascinating information science going on here. Gemini ChatGPT now shows a “Check in” button when it’s thinking. Clicking on that gives you a work-in-progress answer while it continues thinking. When done, it replaces the WIP answer with the final answer. A useful feature! Questions I was asked Week ending 14 Jun 2026 ...

Things I Learned - 07 Jun 2026

This week, I learned: sudo resolvectl flush-caches clears the DNS cache on Linux. Useful when you’re changing DNS records and want to see the changes immediately. In my case, I was creating a Cloudflare tunnel to my laptop and wanted to test it quickly. Making something easy to verify makes it much faster to train models on it. Arithmetic verification is easy - calculators can be deterministically verified. Chess verification is easy - Stockfish became easy to train. Code verification is easy - LLMs improved coding ability rapidly. Therefore: Wherever we have environments that are easy to verify, AI will improve faster there. To make AI improve faster in an area, build environments that are easy to verify. MCP is getting simpler. A stateless HTTP protocol. Simpler OAuth. Plugins. No idea when it will land in Claude or ChatGPT, though. Worth checking after 28 Jun 2026 - after it is finalized. Microsoft Scout is Microsoft’s version of OpenClaw or Gemini Spark. git subtree is a useful way of maintaining git repos inside git repos. For example, if you have a tool tool-a under a project. It’s more light-weight than sub-modules, lets you commit at any point to the parent or child, and is a built-in feature in git. Gemma 4 12B is released and seems almost as good as the 26B version. This is the class of models that makes it practical to run edge AI on phones. It’s multimodal and reasonably smart (like frontier models were 12-18 months ago). I don’t use Claude/ChatGPT Projects much. It offers 3 advantages: custom instructions, memory, files, and chats. Files aren’t useful - I use my entire laptop as a file system via MCP. Instructions aren’t useful - I can paste commonly used prompts with a click. Chats aren’t useful - I have chat references enabled, so all past chats are accessible anyway. Memory isn’t useful - I have memory enabled globally anyway. In short, I haven’t discovered the power of projects that everyone’s raving about. SKILL.md is more useful for me. repo is a Google/Android tool built on top of git that lets you manage multiple git repos. It sounded promising until I released it needs a repo init that creates a .repo/ - which is more overhead that I’d like to keep. When using <image onerror=...> fallbacks, include this.oneerror=null to prevent infinite loops if the fallback image also fails to load. RK One of the advantages of multiple agent (rather than a single agent loop) is: it’s easier to change directions when wrong. Single loops get stuck. Build Agents That Run for Hours Claude Code also supports agent teams where sub-agents can talk to each other rather than rely on the main agent to coordinate. Useful for parallel exploration. Anthropic lets Claude define “organizational policies” for agent teams best suited for the task (AI-native workflows). It also lets agents to push back on their scope, e.g. “This is too hard.” Build Agents That Run for Hours Claude Code has a /background [prompt] (or /bg) command that runs the current session the background. You can run claude agents as a separate command to monitor agents. (There’s no equivalent in Codex yet.) This seems to be the future of agentic operations: a bunch of agents running that you monitor and steer through an agent view dashboard. Models are evolving. Therefore prompts evolved. Now harnesses also need to evolve. The workflows will also evolve. As a result, evaluations might be the (relatively) more stable assets. Datasets are likely to be the most stable ground truth. How to learn a new field fast: Yes, it’s possible to learn 50% of a field in 20 hours. Josh Kaufman, “The First 20 Hours” popularized it. The next 30% takes months and the last 20% takes years. Threshold concepts are those that change your perspective and open up new ways of thinking. Experts’ knowledge is hard-wired and they can’t identify nor teach threshold concepts naturally. Don’t assume they can. “We know more than we can tell.” Polanyi’s 1966 book “The Tacit Dimension” says that there’s some knowledge that can’t be verbalized. This tacit knowledge, therefore, will be harder for humans and AI to learn. Questions I was asked Week ending 07 Jun 2026 ...