This week, I learned:
- trafilatura is a Python library that extracts the main content as Markdown from a web page. A useful alternative to Jina Reader for text. It’s better at main content extraction but can’t handle non-HTML / JS generated / bot-protected URLs.
- The Remote Desktop Commander ChatGPT plugin is a good alternative to my mcpserver.py. Both let you expose bash on your laptop to ChatGPT - which is ultra-powerful. Here’re the where RDC is 🟢 better and 🔴 worse. I would recommend it to everyone (but I’ll stick to my own code).
- 🟢 More features: session/process search, reads PDF/DOCX/XLSX, better file metadata, editing, reading, etc.
- 🟢 Easier: Single command to run, no maintenance, multi-device support
- 🟡 Not sandboxed: But you can run it inside a Docker instance
- 🔴 Hard to tweak: custom instructions, custom logging, etc. require code changes
- 🔴 Privacy: Desktop Commander servers see all traffic (which is why I’ll stick to my code for now)
- From Arun’s lecture to IHRD, Kerala, Jan 2026, here’s what I noted as the impact of Gen AI (and Ed Tech, broadly) on students, and how I address this.
- Defers learning. My approach: teach how to learn on demand.
- Reduces attention spans. I don’t yet have an approach for this.
- Reduces understanding - weakens the the “mental struggle muscle”. My approach: give formerly impossible problems.
- Reduces emotional and social learning. My approach: assess collaborative games.
- With AI making software easier, we can change our operating systems to suit us. Indicators, widgets, keyboard shortcuts, window managers, accessibility tools, device managers, automation workflows, power management, notification management, visual appearance, … I mean, just one look at the Settings in our OS should give us ideas on what’s possible and what annoys us.
- I’m surprised how little CPU VLC Media Player consumes when playing songs. I used to avoid listening to songs on flights to save power. That seems unnecessary. Most of my VS Code and browser processes consume way more CPU (3-6% of 1 CPU per process, as opposed to VLC’s 0.5%)
- Alcoholism is partly genetic and ancestral. There’s an ALDH2 rs671 gene and those who carry it (many East Asians) drink less and are less prone to addiction. PubMed. Smoking and Coffee might have something similar, too. Aggression and IQ seems genetic, but less ancestral.
- I used ChatGPT’s voice mode as a tour guide at Fort Santiago, Manila. It was pretty good - it researched the place, told me what to see, explained what I was seeing (interpreting my photos), laughed at my enthusiasm, and made me feel like I had company. But the experience wasn’t perfect (and I expect these will improve - I need to try this more) because it:
- Made two factual errors I spotted. It said “down river” instead of “up river” when mentioning a new bridge, said lookout holes were bigger on the inside than the outside. I expect models will get better.
- Responded slower than I’d like because it kept researching. I later told it to stop researching and just talk to me. But it was able to talk to me while running tools (including research) in the background, so I expect these are getting better, too.
- Didn’t have enough personality. It felt like a helpful assistant I can’t make friends with, rather than a stranger with idiosyncracies or preferences. I expect they’ll be able to take on more personalities soon (and perhaps already can, if instructed to).
- I find the ChatGPT “Library” a useful place to store notes while speaking. I just tell it to add an idea to “notes/ideas.md” in my library and review it periodically. That’s a pretty useful way to take notes while talking to it in voice mode.
- On Google, the “I’m feeling lucky” takes you directly to the first result. On Google AI Studio, when you create an app and dictate what you want and press “I’m feeling lucky”, it DOESN’T transcribe what you said first. It just builds a random application (often titled “MuseInk” for me) #ForNow. The geniuses who designed the original “I’m feeling lucky” clearly did more usability testing than the current AI Studio team.
- Several sites have popped up that let agents deploy websites. Here’s ChatGPT’s review of agent hosting services:
- here.now by default. Smoothest all-round agent publishing, with stable URLs, updates, access control, and versioning.
- PageDrop for review. Inline comments turn directly into feedback for agent revision.
- HTMLDrop for clean MCP/OAuth integration. Best when authentication and remote MCP plumbing matter.
- Stacktree for client deliverables. Gated sharing plus feedback and engagement features.
- GPT Live 1 costs 5c/min ($3/hr) flat #ForNow. That’s a MUCH easier to use pricing. Gemini 3.8 Live is more complex. Small conversations (under 10 min) might cost just $0.7/ hr but over time, can accumulate context and grow to $2-5/hr #ForNow. ChatGPT
- AI overwhelms me and I have “LLM fatigue” (tired of actioning AI output). If you treat hard tasks like exercise (“you’re building muscle”) you get more done, you feel less miserable, and build an ability (a mental muscle of some kind, I think). I started with a “1 min of exercise” on 14 Sep, forcing myself to do just one minute of something (typically actioning AI output), then increased it to 2 min the next day, and so on. 10 min may not sound like much today, but since I tend to stick to routines, I’ll be able to focus for an hour extra in a couple of months.
- The IIT Madras BS in Data Science and Applications has at least three support business models:
- Get in: Meritus (Ramana Prasad) coaches for the entrance exam.
- Get through: DataCharya and Unknown IITians coach Foundation/Diploma/Degree courses; AceGrade (Sumit K. Sharma) offers much of this free.
- Make it a college: SEEP wraps IITM BS in an offline campus, classroom, cohort and mentoring experience.
cctopis a nice CLI alternative toagentsviewfor monitoring agent sessions. I still preferagentsviewfor details butcctophas a real-time update that’s fast and useful.- In June, I predicted “Python will have grown the most as a language in GitHub” by the end of the year. That’s because AI agents know Python well and will likely code in Python. But agents are now just as fluent in Rust, etc. as well as able to debug new languages, so I expect that the better programmers will carefully choose their programming language to the task. In fact, I more far more likely to hire someone with a Rust repo on GitHub and, next year, might treat Python as a slop-smell.
- About 1 million people were discovered in Papua New Guinea in the 1930s who had no contact with most of the outside world - via why I can’t stop thinking about Papua New Guinea and what I think everyone should know about it. “The Spanish and Portuguese brought sweet potato and tobacco near the western tip of New Guinea, in the 1500s. Beyond that point, there were no merchants. But when a woman married into the next clan over, she took cuttings from her family’s garden with her. Each new family then planted the same, saw that it worked, and passed it on. At that pace the sweet potato crossed the highlands in a century or two, with nobody knowing where it came from beyond the tribe beside them.”
- Poster Prompts is a gallery of prompts for AI-generated posters. Similar to my LLM Art Style. As before, I’m struck by how few designs I actually like and would use in practice. Hacker News
- In 1653, Thomas Urquhart wrote Logopandecteision - a book in which he plans a new language. People believe it was a parody / practical joke. He also included a cipher:
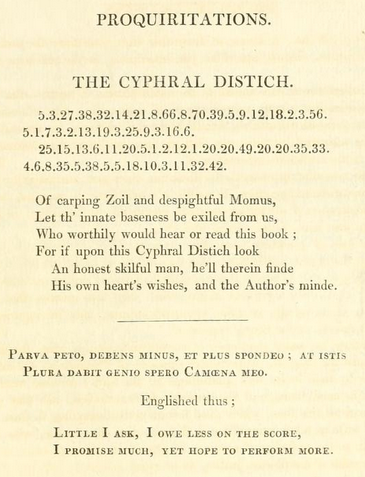
… that Fable 5.1 solved in 44 minutes and 176k tokens. It reads: O GOD UPHOLD KING CHARLS THE SECOND AND MAKE HIM THE SUPREME RULER OF THIS LAND". The rule was: For the i-th number, first letter of the i-th word of the i-th Proquiritation. ChatGPT verified it. The filtering process to pick a low-hanging fruit is interesting: “I asked it to solve an unsolved cipher … avoid ciphers that already had solutions… I steered it away from the absolute hardest problems”
Mistakes I made
- I said “I know what factors are important and therefore I can start making changes” while using a predictive decision tree on student grades to identify interventions.
Correction: A predictive model can identify variables associated with grades, but that does not show that changing those variables will improve grades; interventions need causal evidence or assumptions designed to identify causal effects.
MEDIUM · OVERSTATED - I said “GPT-3.5 Turbo… only cost you 50 cents” while describing the cost of models available in March 2023.
Correction: GPT-3.5 Turbo launched on 1 Mar 2023 at $0.002 per 1,000 tokens, or $2 per million tokens; $0.50 per million input tokens arrived withgpt-3.5-turbo-0125in January 2024.
MEDIUM · FALSE - I said “a million tokens… about a million words” while translating model pricing into document size.
Correction: Tokens and words are not interchangeable; for English, OpenAI’s rough rule is 1 token ≈ 0.75 words, so one million words is roughly 1.33 million tokens, with the exact count depending on the text and tokenizer.
LOW · FALSE - I said “if there are more objects than containers, then there will be something that’s left out” while explaining the pigeonhole principle.
Correction: If there are more objects than containers and every object is placed in a container, at least one container must contain at least two objects; nothing needs to be left out.
LOW · FALSE - I said “logprobs—the chance that it might have made a mistake” while explaining how to prioritize AI outputs for human review.
Correction: Logprobs are probabilities assigned to generated tokens, not probabilities that an answer is wrong. They can be useful uncertainty signals for ranking review priority, but that relationship needs to be validated or calibrated on the task.
MEDIUM · OVERSTATED - I said “LLM doesn’t care what language you’re speaking in… language agnostic” while discussing multilingual workflows in an AI workshop.
Correction: LLMs are multilingual, not language-agnostic: capability varies by language, task and model, and lower-resource languages can perform substantially worse. Even OpenAI says its models are optimized for English. Test the actual languages required before treating a workflow as language-agnostic.
MEDIUM · OVERSTATED
Questions I was asked
- Question: How do we calibrate an AI app that hallucinates information not present in the source? Asked while testing a recruiting app that was inventing details not present in candidate CVs.
Answer: Log the inputs, outputs, and human corrections. Build up that history, then use it to test prompt or model changes and whether a second-pass check catches the same mistakes. - Question: If AI automates part of the work but people still check everything, how do we get real productivity? Asked while discussing automation that improved output but still required full QC because the team did not trust it enough to let work pass unchecked.
Answer: Don’t automate everything a little. Pull out even one 10% slice where you can get to full confidence, stop checking it, and redesign the workflow so that 10% becomes an actual capacity saving. - Question: Should we replace mature rule-based automation with AI-native workflows? Asked while discussing how new AI workflows were taking time just to recover productivity already achieved through deterministic automation.
Answer: No. Keep the rules that already work and use agents to find missing rules and improve existing ones from correction logs. Deterministic checks give you confidence and can bring the LLM cost down to zero.