Open weights models are nudging up the frontier.
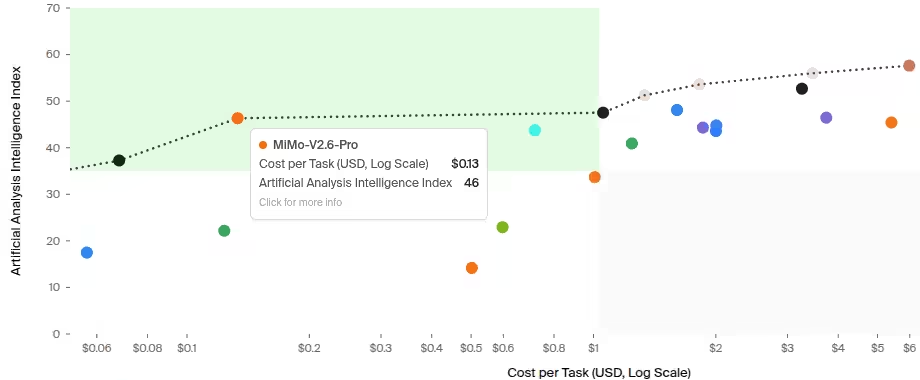
For example, MiMo V2.6 Pro is an outlier on the Artificial Analysis Intelligence vs Cost per Task benchmark
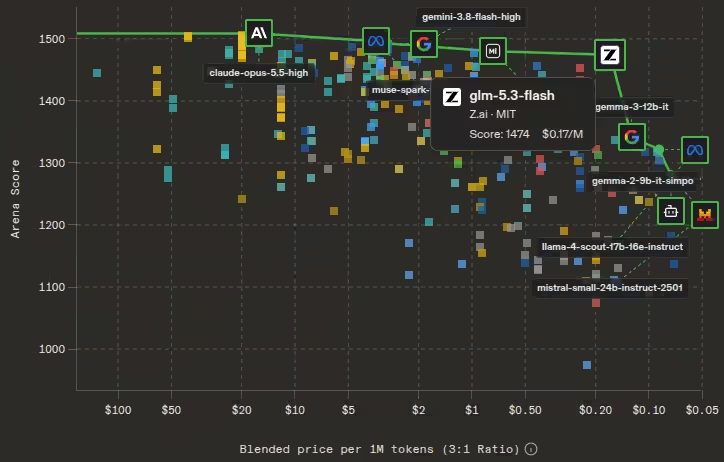
GLM 5.3 Flash is an outlier on the Arena Text Pareto
Deepseek V4.1 Flash seems to be doing a great job as well.
So, I thought I’d relook which model to use locally for coding.
BTW, I don’t use local models for coding. It’s pointless, except on flights with power sockets. Partly in preparation for flights, and partly to check if I’m missing something, I benchmarked two models I could run locally on my 8 GB RTX 2000 GPU: Gemma 4 E4B and Qwen 3.6 against GPT 6 Luna. (Better models like Qwen 3.8, MiMo V2.6 Pro, GLM 5.3 Flash, Deepseek V4.1 Flash, etc. are too big for my GPU.)
I asked ChatGPT to look at my recent coding work and suggest 3 prompts. It did:
- flare-loading: Make a large image-heavy page load better on a poor network without reducing image quality.
- mcpserver-console: Make rapidly scrolling MCP tool logs easier to understand without
- whatsapp-integrity: Detect corrupt/misattributed backup JSONL safely before touching WhatsApp/CDP.
I gave the task to all three models. Here’s what happened:
| Task | Gemma 4 E4B | Qwen 3.6 | GPT-6 Luna |
|---|---|---|---|
| flare-loading | 🔴 Didn’t fix | 🟡 Preloaded but didn’t optimize | 🟢 Optimized |
| mcpserver-console | 🔴 Didn’t complete | 🟡 Improved readability but timed out | 🟢 Concise solution |
| whatsapp-integrity | 🔴 Didn’t complete | 🟡 Built a solution but timed out | 🟢 Concise solution |
In short, there’s still no reason I’d use a local model for coding. But if I did have to, I’d use Qwen 3.6 today.
The process of benchmarking is becoming increasingly easy. Here’s roughly how I created this benchmark entirely using ChatGPT in about half a dozen prompts:
- I’ve been using gemma4:e4b-it-qat and it’s working fine. Several new models have been released since. What would you now recommend as the best model I can run on my laptop using ollama?
- What’s the easiest way for me to set up and use Qwen 3.6 with llama.cpp and use it via pi agent?
- Suggest 3 tasks that I can use to benchmark or compare the quality of these models. Something where I can instantly / easily judge the output and is likely to produce a difference between these models (and GPT 6 Luna - which I’ll add later into the benchmarks.) You’re welcome to iterate a few times to see if it really provides an output that’s well differentiated and easy for me to see the difference.
- OK. Create, under
~/code/llmevals/qwen-3.6-vs-gemma4-e4b/a set of directories for each of these tasks (perhaps one set for qwen and one set for gemma? I’ll leave it to you to decide the best organization) as well as a benchmark.sh that I can run which will update / fix the directories. Commit the files. When done, let me know. I will run benchmark.sh. Then you can review the output and compare the quality. I’ll do the same. We’ll compare notes and decide next steps. - Now modify benchmark.sh so that it will run for codex.
- Compare the results and let me know what you think. Then I’ll share my opinion.