Qwen 3.6 vs Gemma 4 vs Luna
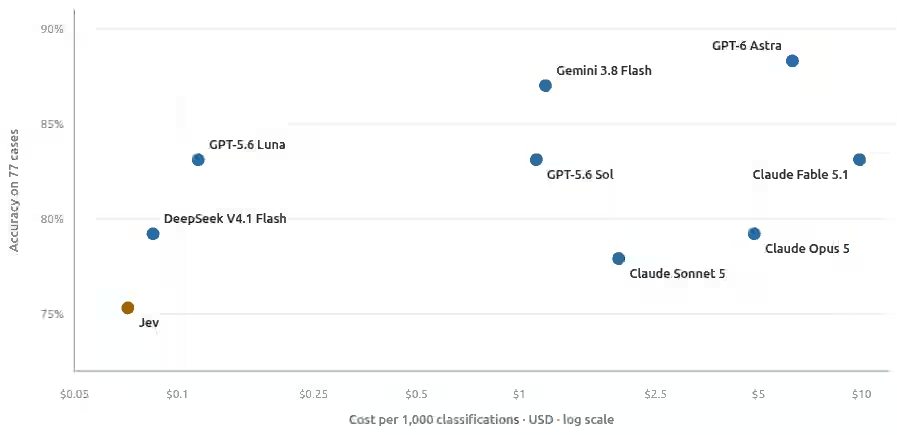
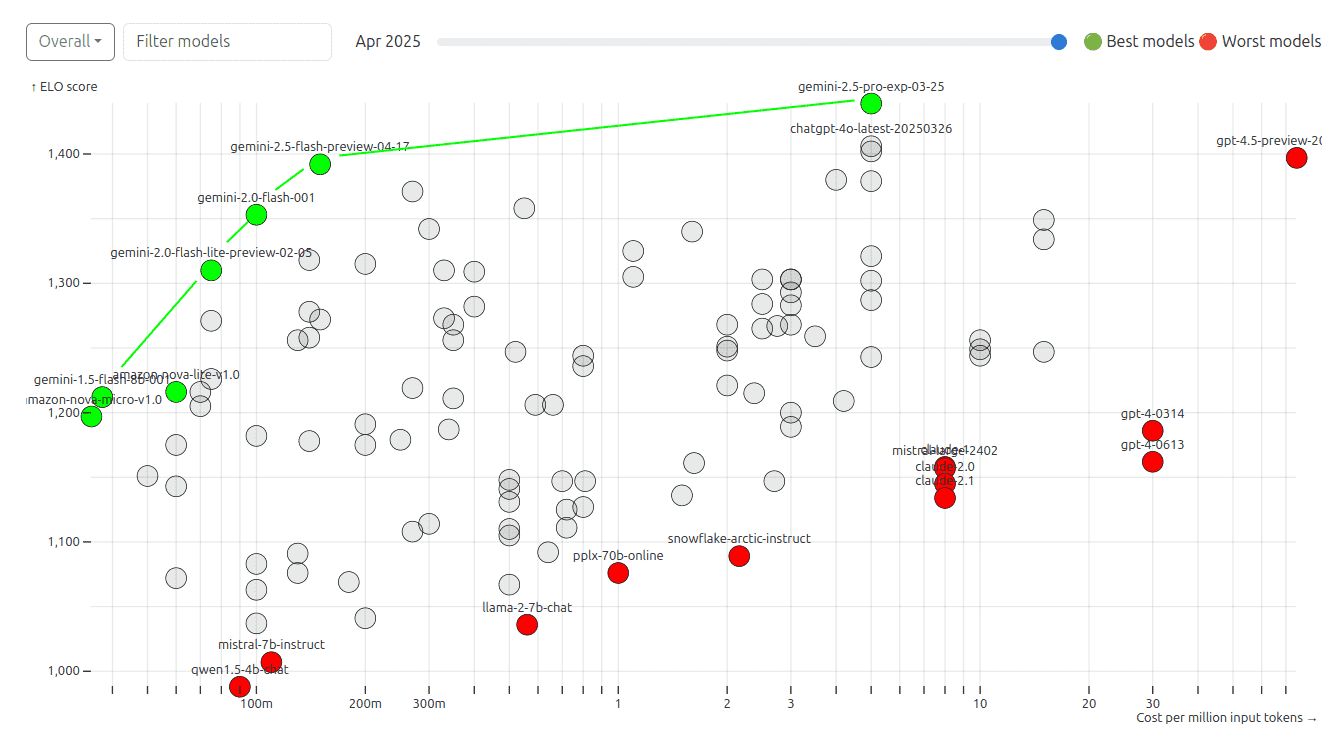
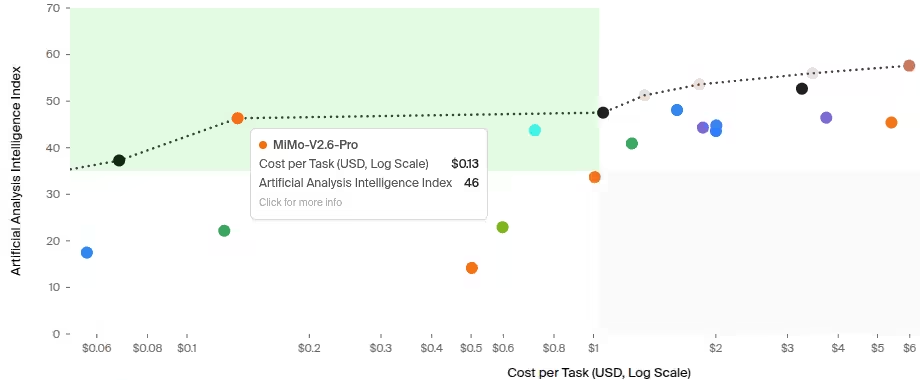
Open weights models are nudging up the frontier. For example, MiMo V2.6 Pro is an outlier on the Artificial Analysis Intelligence vs Cost per Task benchmark GLM 5.3 Flash is an outlier on the Arena Text Pareto Deepseek V4.1 Flash seems to be doing a great job as well. So, I thought I’d relook which model to use locally for coding. BTW, I don’t use local models for coding. It’s pointless, except on flights with power sockets. Partly in preparation for flights, and partly to check if I’m missing something, I benchmarked two models I could run locally on my 8 GB RTX 2000 GPU: Gemma 4 E4B and Qwen 3.6 against GPT 6 Luna. (Better models like Qwen 3.8, MiMo V2.6 Pro, GLM 5.3 Flash, Deepseek V4.1 Flash, etc. are too big for my GPU.) ...