2026 10

Learning in a Podcast Interview

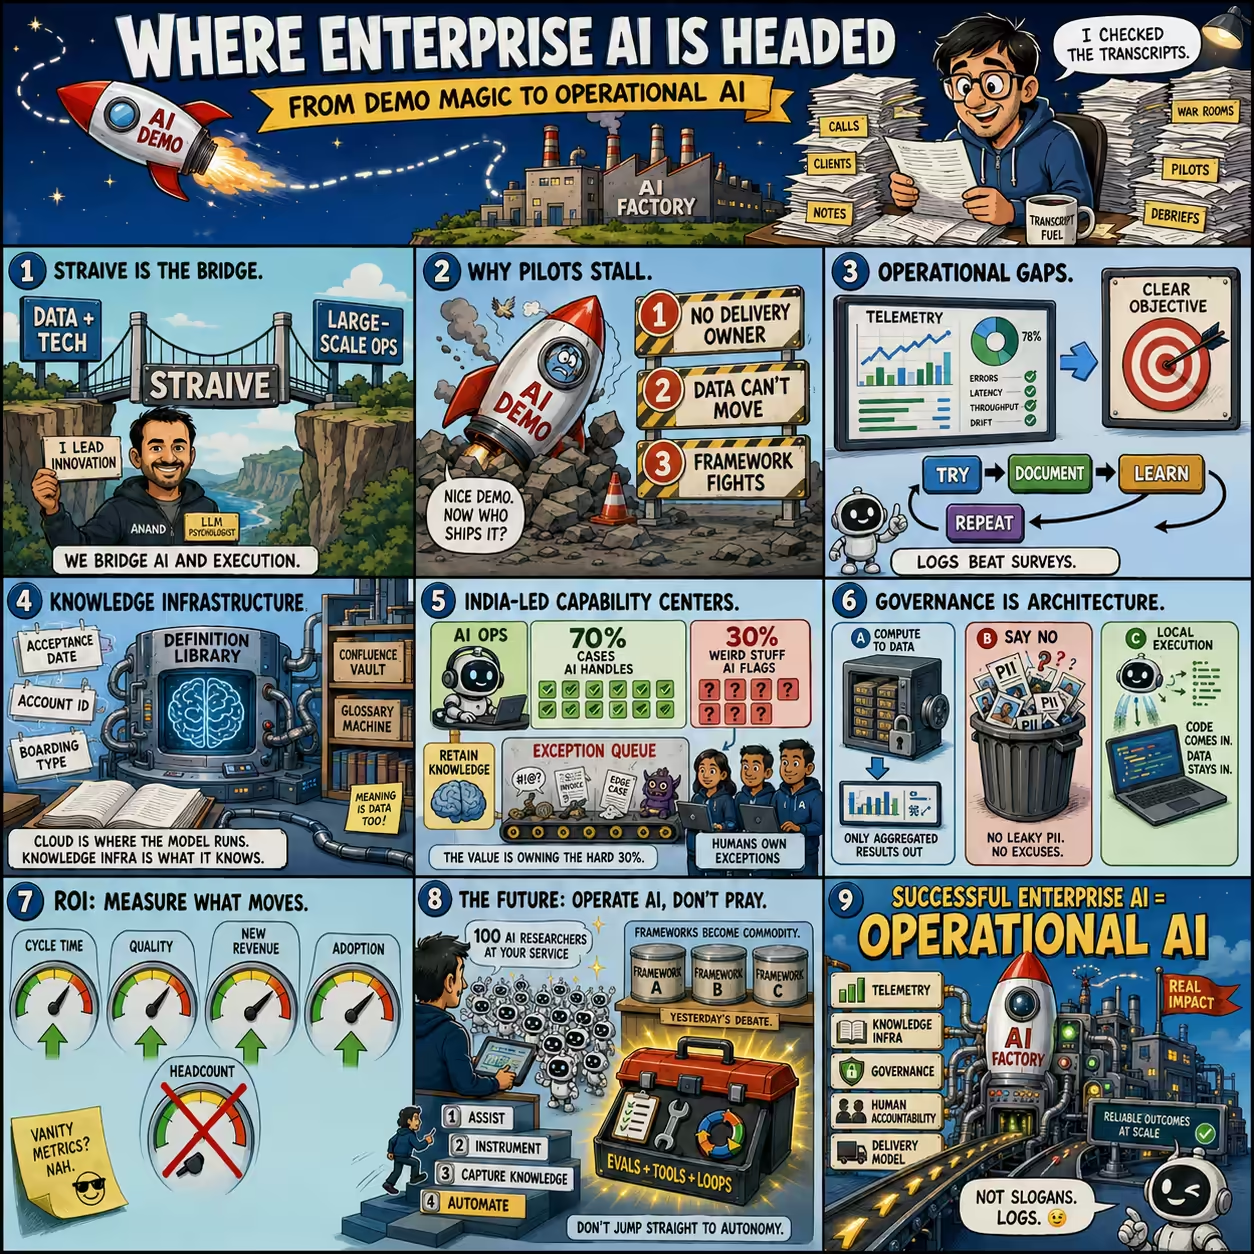
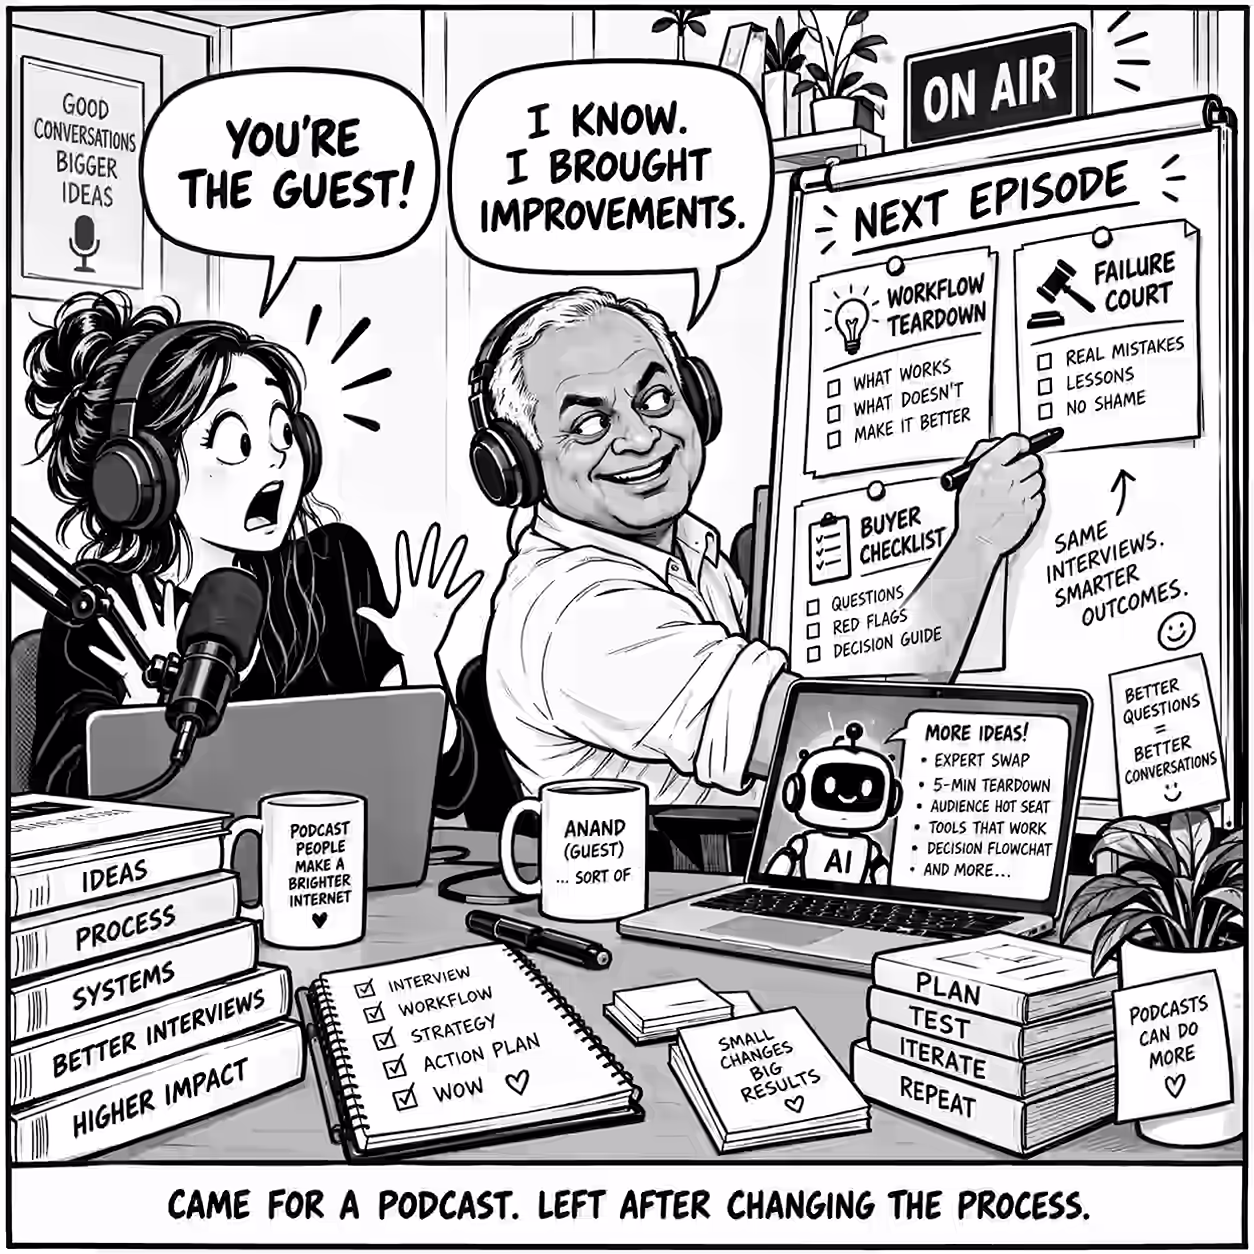
Priya Dialani interviewed me for a podcast. Here’s the rough summary: What do you and Straive do? Straive builds AI and runs AI. I poke at LLMs to learn what they cannot do. My friend calls me an “LLM Psychopath”. Why do AI pilots get stuck before production? AI speeds up coding, but less of testing. Making sure it works can take months. Why organize enterprise knowledge? Better organized info is good for humans and agents. Duh! Can AI organize it? Yes! I’ve had it create one-line summaries of 10K+ docs on Straive Google Drive for easier searching. How can India’s GCCs benefit from AI? Put AI lovers next to business teams and give them AI agent access. They’ll solve asked and unasked problems. How does AI fail? Unanticipated things happen in production. So, have agents monitor failures and revise the process. How is AI software different? Normal software fails reproducibly. AI fails in new ways we haven’t fully understood. Where should a company start with AI? Skip AI strategy. Give people agent access, have them try it, and share what they learned. What if people don’t know what to try? Ask AI. “How could you improve my work?” Even rubbish ideas waste only 5 minutes. How much should we experiment? A lot! Generation is cheap. Ask for 10 options, not one. Who cares even if all 10 fail? But what happened outside of the interview was just as interesting. ...

CIO Newsletter

Find the best ideas for my next occasional email to CIOs and senior technology/data leaders. Use relevant skills from @LocalMCP2 - expert-lens, ideation-protocol, blind-spot, anand-objectives, ... ## 1. Calibrate the newsletter Using personal Gmail via `gws`, find sent emails from `[email protected]` containing: `you might have hinted you'd like such emails from me` Read the newsletter emails, not merely the matching snippets. Infer: - the audience; - the recurring structure and tone; - what counts as sufficiently important; - topics already covered, so they are not repeated. These are not AI-news roundups. The strongest emails usually begin with something I personally did, observed, measured, decided, or got wrong; provide inspectable evidence; derive one surprising enterprise implication; and give readers something concrete to try or reconsider. ## 2. Search my corpus Search primarily after the latest matching newsletter, while allowing older material that was overlooked. Use a staged search: 1. Scan indexes and recently modified files to identify at most 30 candidate sources. 2. Deep-read at most the 12 richest sources. 3. Re-open the best evidence to verify exact wording, numbers, dates, and provenance. Prioritize: - recent meeting transcripts and notes under `~/Dropbox/notes/` and ``~/Dropbox/notes/transcripts/`; - `~/code/talks/README.md` and linked talks; - `~/code/blog/description.md` and targeted posts; - `~/code/til/README.md`; - `~/code/llmdemos/config.json`; - `~/code/llmevals/README.md`; - email or chat only when it supplies a firsthand incident, reaction, decision, result, or failure. Do not let public AI news become the core idea. Public sources may corroborate my evidence, but cannot substitute for it. ## 3. Gate every candidate Keep an idea only when most of these hold: - **Firsthand:** I did, observed, measured, decided, or materially shaped it. - **Surprising:** it challenges a reasonable CIO assumption. - **Consequential:** it could change an enterprise decision within the next 6–12 months. - **Evidenced:** there is a concrete incident, number, artifact, failure, or audience reaction. - **Exclusive:** a well-read CIO is unlikely to learn most of it from ordinary AI media. - **Emailable:** it supports one focused story: incident → implication → practical move. - **Shareable:** it is public, can be safely anonymized, or is clearly marked as requiring approval. Reject generic trends, secondhand frameworks, routine project updates, unsupported opinions, thin rewrites of earlier newsletters, and impressive claims whose provenance cannot be recovered. Explore broadly before ranking. Include 2–3 `IDEA`s: rich sources that may not yet support a finished thesis but are likely to provoke a better idea. ## 4. Output Return 8–12 ideas, prioritized. For each: 1. **Working title and one-sentence thesis** 2. **Opening incident or evidence** 3. **Why a CIO should care** 4. **Why this is uniquely me** 5. **Sources:** exact path, date, and useful line range or section; mention any public artifact available in the source 6. **Shareability:** PUBLIC / ANONYMIZE / APPROVAL NEEDED 7. **Missing evidence or weakness** 8. **Verdict:** WRITE NEXT / STRONG / IDEA / SKIP Then provide: - the top three in order, explaining why each narrowly beats the next; - one attractive but generic idea rejected; - one strong idea rejected because it is not sufficiently me; - any important corpus area that could not be inspected. Do not draft the newsletter. Be concise, skeptical, and specific. Never invent a result or imply external approval. 27 Jul 2026: Created. ChatGPT
Tacit is just un-instrumented

At The Curzon Hotel, my key card didn’t work. But every time I went to the reception, they’d send a bellboy who would use the same key card, jiggle it a bit, pull it in and out a few times, and the door would open. Every night. For five nights. I just couldn’t get the knack of it. I’ve been at the other end of this. People often reach out to me saying, “Anand, this software isn’t working.” Then I go do the same thing they did, and it works. (Sometimes, I just need to watch them do it and it works.) ...

How AI bottlenecks shift

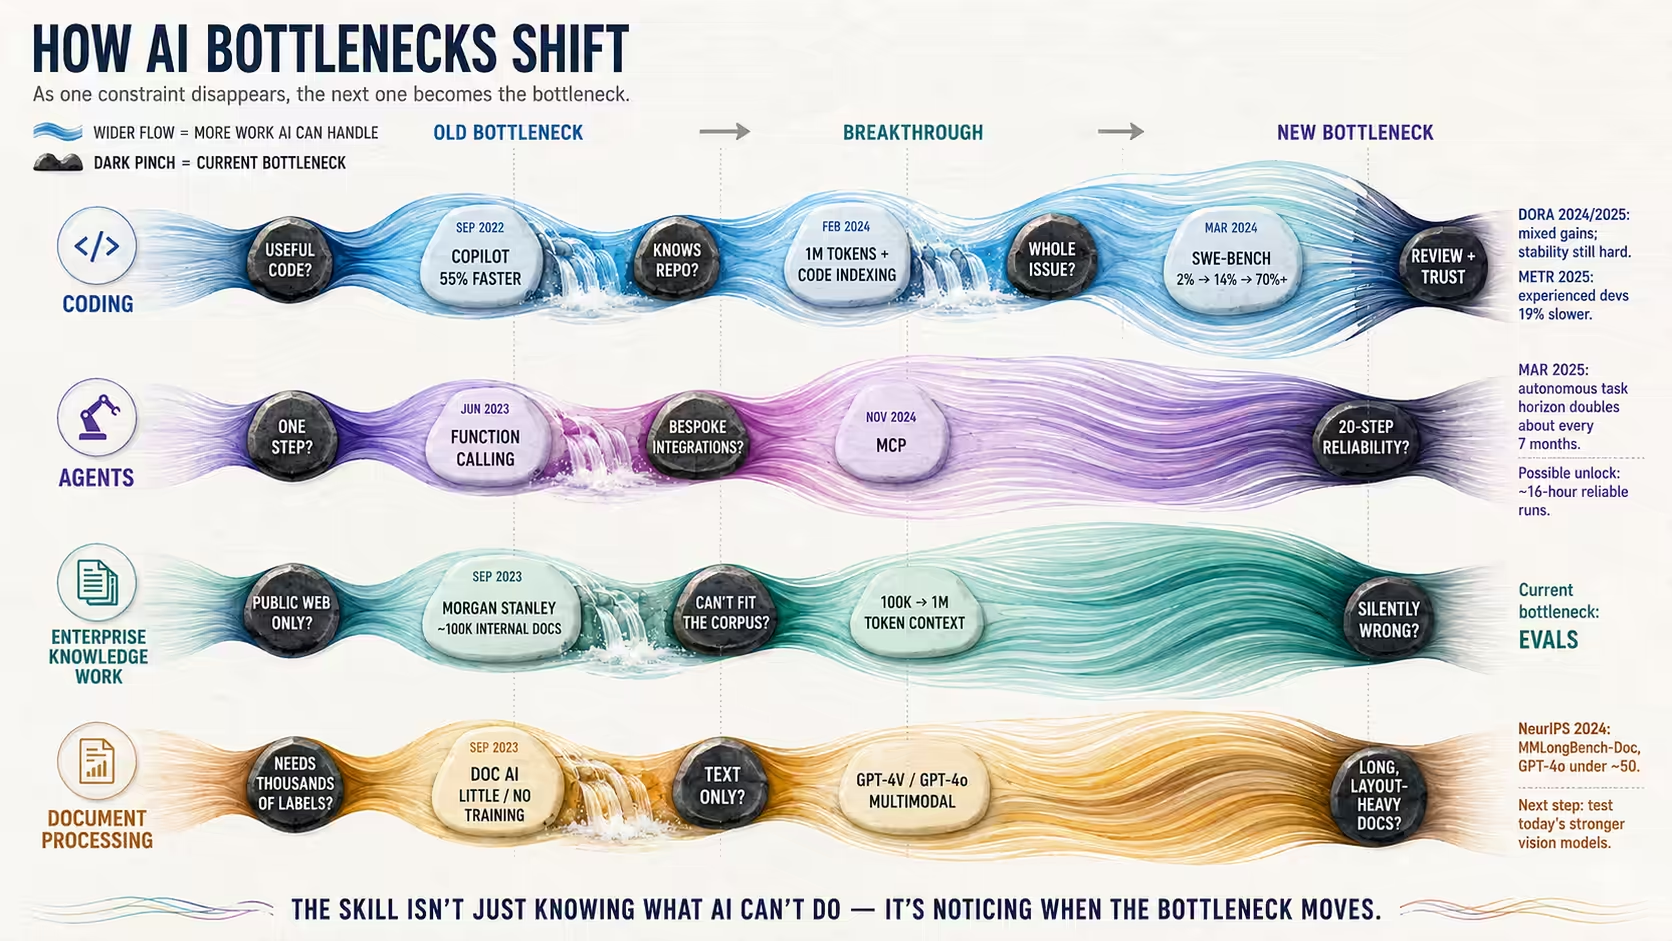
I wrote about my changing AI opinions. At least some of this is because the industry is moving so fast that the bottlenecks keep shifting. Here are four examples of how we AI couldn’t do something (the bottleneck), but that became possible, and the bottleneck shifted - changing the way we work. It’s good to keep this in mind when thinking about AI. Coding: “It can’t write useful code. We can’t get real help.” But in Sep 2022: GitHub finds Copilot developers are 55% faster. “It writes code but doesn’t know our codebase. We can’t let it touch real projects.” But in Feb 2024: Gemini 1.5 Pro has 1M-token context ~ 30K LOC". Cursor indexes code. “It understands the repo but can’t ship a fix on its own. We can’t hand it a whole issue.” But in Mar 2024: Devin solves 14% of SWE-bench - up from 2%.. Verified SWE-Bench is now 70%+. “It ships fixes, but we can’t review them fast enough or trust they’re stable.” Oct 2024: DORA 2024 finds AI hurt both throughput and stability. Now: Sep 2025: DORA 2025 finds is positive but stability stayed negative. Now: Jul 2025: METR’s RCT finds experienced devs 19% slower. Agents ...

AI Coding Agent Subscription ROI

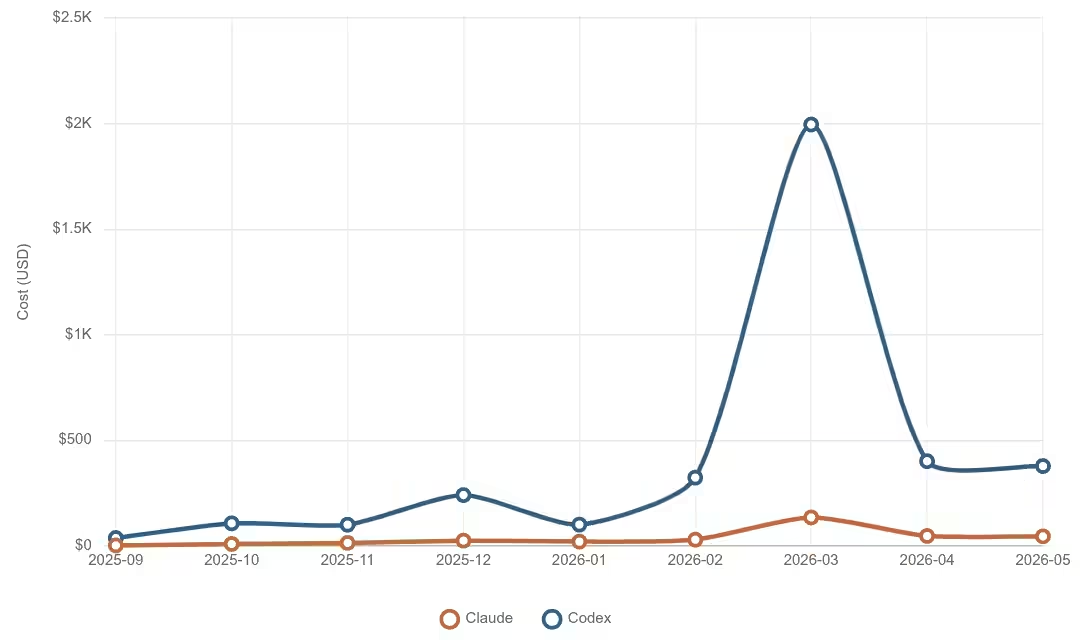
I ran npx -y ccusage monthly --compact to get the following break-up of my AI coding agent costs. Month Codex Claude 2025-09 $37.47 $2.29 2025-10 $106.79 $9.13 2025-11 $100.35 $14.24 2025-12 $240.69 $24.88 2026-01 $100.89 $20.28 2026-02 $323.21 $29.46 2026-03 $1996.32 $134.87 2026-04 $401.36 $47.07 2026-05 $378.20 $45.13 This shows the ROI of my $20 subscriptions to each. I get ~$35 worth of API calls for my $20 Claude Pro subscription and ~$400 of API calls for my $20 ChatGPT Plus subscription (on top of my ChatGPT chats.) ...

Where Enterprise AI is headed

A podcast host sent me eight questions. Instead of rehearsing answers in my head, I used ChatGPT with Local MCP to read 6 months of call transcripts and find the best examples: Iteration 1: Here are questions I have been asked to answer in a podcast. Help me prepare with examples. For each question, go through my transcripts or emails and find examples relevant to the question and share (for each relevant example) a summary, how it’s relevant, and the relevant verbatim quotes from the transcript. Iteration 2: Mention WHO said it. Emphasize the most important parts. Do a second pass. More examples. Disprove your own hypotheses with evidence to the contrary and retain what remains robust. Iteration 3: Do a third pass. Find more real-life examples. Try and disprove yourself even harder. Share the best examples for what survives - not all. Same format. Iteration 4: Ensure diversity of client examples. For example, in Q2, all three are the same client. Extend to add / replace examples - ideally with better ones. Then I used Claude with examples of my writing style to summarize it in my voice. ...

LLM Deprecations and Price Changes

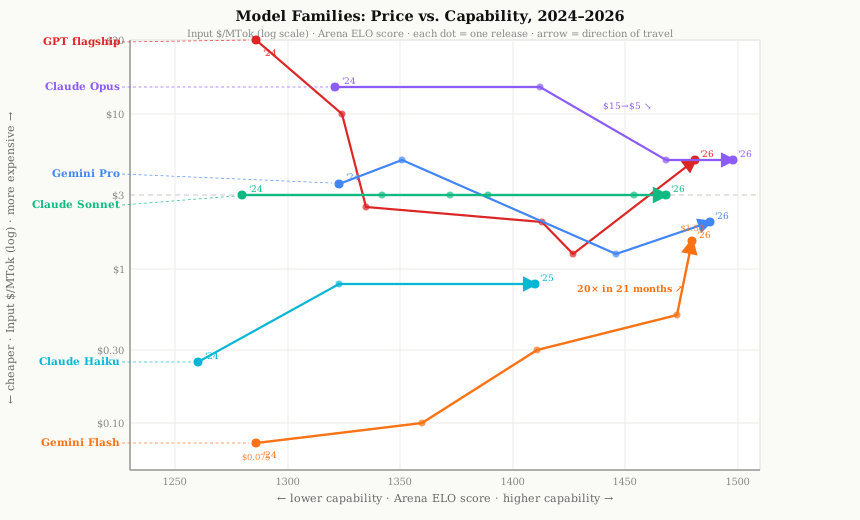
A colleague told me a near-miss horror story. As Google began deprecating Gemini 2.0, we moved to Gemini 2.5 Pro. But reasoning is enabled by default and cannot be turned off. For our specific problem statement, reasoning was not required. Token costs increased 10x and speeds were 3-4x slower. We moved the client to Gemini 2.5 Flash Lite, which has reasoning turned off by default and offers much lower latency. ...

AI advice for teams

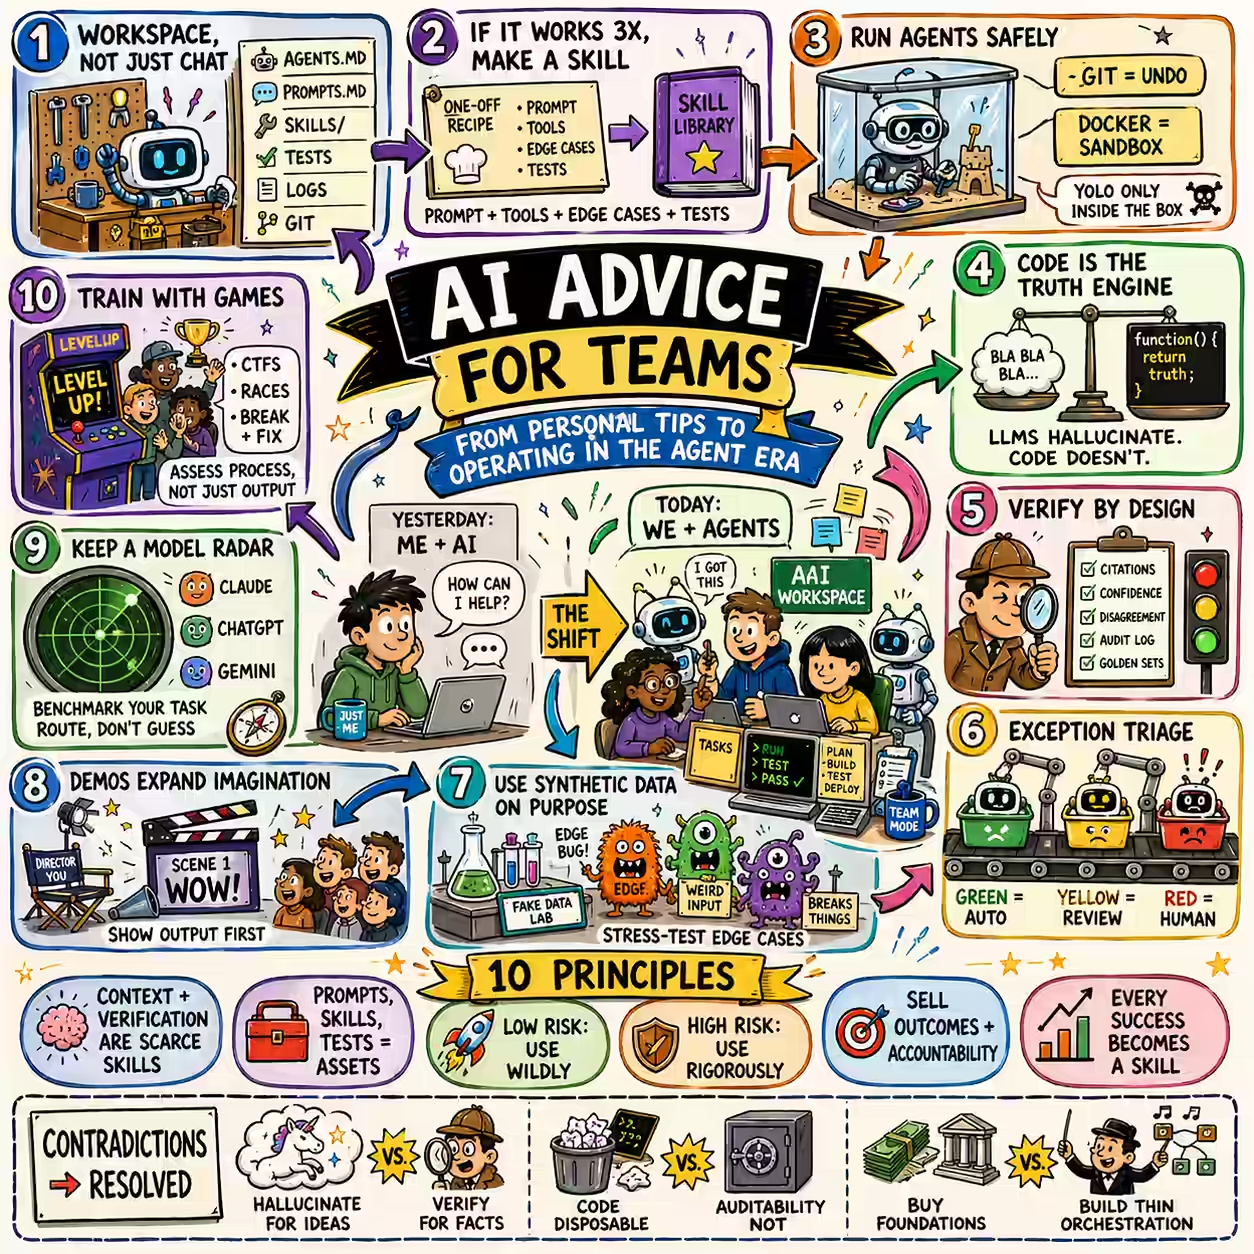
I updated my AI Advice page by: Transcribing my calls in the last 2 months (Gemini 3.1 Pro, “Transcribe this call recording…”) Extracting AI advice (Gemini 3 Flash, “Summarize ALL AI-related advice … into 1-sentence bullets”) Asking Claude, ChatGPT, and Gemini to document what’s new / changed. I added this request: But, and this is IMPORTANT, analyze my original writing style, write it exactly in that style, and then verify to make sure it follows the same style (correcting where required.) ...

Gemini Enterprise Business

I got an email from Google Cloud on my work account “excited to introduce you to Gemini Enterprise”. Once I signed up, it said, “you have 30 days to try Gemini Enterprise – Business edition at no cost.” After that, it costs US $21/user/month, which I can subscribe to here. The main differences from Gemini Pro (consumer accounts) seem to be: Data Privacy. Google won’t read or use your data to train. (In Pro, you need to turn it off explicitly. Here, it’s the default.) Admin Controls. Admins can turn off connectors, manage users, retention policies, etc. Copyright Indemnification. If AI infringes copyright and you get sued, Google will find the case. But if you’re using Gemini via your Google Workspace account (i.e. your work account already has Pro subscription), then it makes no difference - it’s all the same. ...

Learnings from building Babbage Insight

Here’s a great post by Karthik Shashidhar on why they shut down Babbage Insight, and the learnings from the experience. (I’m reproducing in full here since LinkedIn is hostile to content.) I added ⭐ to points I found most interesting. As the more perceptive of you would have figured out by now, we are shutting Babbage Insight . When I told this to one of my old friends, his immediate reaction was “so what were your learnings from this experience?”. And so I decided to write this. ...

2025 1

Features actually used in an LLM playground

At Straive, only a few people have direct access to ChatGPT and similar large language models. We use a portal, LLM Foundry to access LLMs. That makes it easier to prevent and track data leaks. The main page is a playground to explore models and prompts. Last month, I tracked which features were used the most. A. Attaching files was the top task. (The numbers show how many times each feature was clicked.) People usually use local files as context when working with LLMs. ...

2024 1

What does Gramener ask ChatGPT?

I looked at how Gramener uses ChatGPT Plus by evaluating 600+ chats asked over 3 months from Oct 2023 to Jan 2024. The team asks 6 questions a day. We don't track who or how many actively use ChatGPT Plus. This also excludes personal ChatGPT accounts. Still, 6/day is low for an entire team put together. The questions fall into 8 categories. Category%Excel, data exploration & analysis25%Text extraction and summarization13%HTML, CSS, or JavaScript code13%Python code13%LLMs, AI and use cases9%OCR and image analysis9%Generate images, logos, and designs7%General knowledge, policy & environment5%Audio and translation5% Here are some questions from each category - to give you an idea of emergent ChatGPT Plus usage. ...

2013 1

Open source in corporates

[This is a post that I’d published internally in InfyBlogs in Dec 2009. Time to share it.] Last month, my first application went live. I’ve been writing code for 20 years. Not one line of my code has been officially deployed in a corporate. (Loser…) It’s a happy feeling. Someone defined happiness as the intersection of pleasure and meaning. Writing code is pleasurable. Others using it is meaningful. But this post isn’t quite about that. It’s about the hoops I’ve had to jump through to make this happen. ...

0001 1

Q1. What are the key reasons behind this “last-mile problem” in scaling AI to production? In my experience, the last-mile problem is rarely because the model is not powerful enough. The bigger issue is that a good AI demo and a working enterprise process are very different things. A demo can work with a clean sample, a friendly user, and a narrow workflow. Production has messy data, approvals, system dependencies, latency, security reviews, exception handling, and people who have to trust the output enough to act on it. ...