Solving Industrial Problems with Live Coding

I conducted a session on Wed, 23 Jul 2025 at AWS Innovation Day — Manufacturing, Industrial and Supply Chain - Singapore. Summary: LLMs can turn messy industrial and IoT data into working analyses live, collapsing the gap between domain question, code, model, and decision. Here’s the link to the session Links: Transcript Audio (11 min)

Things I Learned - 20 Jul 2025

This week, I learned: Inevitablism is framing an argument as if it is the only logical choice in an inevitable future. Thereafter, the argument shifts to are there any alternative choices in that inevitable world, rather than whether that future is, in fact, inevitable. ⭐ LLM chat over data may leapfrog dashboards. This may be a trigger to kill redundant UI. A new wave of (liberal) colleges have emerged. Ashoka University, Krea, Plaksha (Mohali), Jindal University (Sonipat), FLAME University (Pune), Azim Premji University, Shiv Nadar University. Many of these accept IB students who are choosing to stay in India, instead of the earlier trend of studying abroad. xh is curl-compatible but adds JSON pretty‑print, colour, --table and can pass parameters like xh post :8000/api question='When is the ROE?' dasel is jq-compatible but supports YAML and TOML too lazygit is a 5-MB TUI that lets you stage/commit/push/diff in one screen eza is a modern ls replacement. I switched to this with abbr --add l 'eza -l -snew --git --time-style relative --no-user --no-permissions --color-scale=size' jless is less replacement for large JSON streams, with search & scroll jc is a JSON to table formatter uv cache prune removes only unused cache entries and saves a fair bit of space. Mine trimmed 85 GB. Claude Code settings are in ~/.claude/settings.json (personal) < .claude/settings.json (project) < .claude/settings.local.json (uncommitted personal) < CLI arguments. Explore model, permissions, env, forceLoginMethod. Ref #ai-coding Claude Code loads memory from ~/.claude/CLAUDE.md < .CLAUDE.md and from subdirectories when required. Run /init to auto-create it with repo-specific info! Mention @file to import. Beginning an input with # ... adds it to memory! Run /memory to view/edit memory files. Ref #ai-coding Claude Code lets you type \ then Enter at the end of a line to continue to the next line. Or, run /terminal-setup to bind Shift-Enter to insert a newline. #ai-coding Claude Code has built-in tools to read & write Jupyter notebooks (interesting), to run sub-agents (powerful), and to manage TODO lists (useful) Ref #ai-coding claude -p "query" runs the query and exits, making it a very powerful pipeline tool. E.g. cat stream.jsonl | claude -p "..." --output-format json --input-format stream-json --max-turns 3 --dangerously-skip-permissions Ref #ai-coding Claude Code has a /review command that requests a code review and a /pr_comments to view pull request comments Ref #ai-coding Claude Code lets you define custom slash commands at ~/.claude/commands/*.md < .claude/commands/*.md. Use @file to reference files, $ARGUMENTS for arguments, and ! for bash commands like DIR: !`pwd`. YAML frontmatter supports allowed-tools: and description: Ref #ai-coding You can drag & drop a screenshot or paste it into Claude Code! #ai-coding Claude Code lets you run /compact Focus on code samples and API usage (or mention it in CLAUDE.md) #ai-coding Claude Code activates extended thinking via these keywords: think < think hard < think harder < ultrathink Ref #ai-coding Claude Code lets you set up GitHub Actions via /install-github-app so that any mention of @claude in an issue or a PR will trigger a CI job that does what you suggest. An alternative to Jules or Codex #ai-coding Claude Code enterprise use is possible. It works with Google Vertex AI and Amazon Bedrock securely and supports usage monitoring #ai-coding Claude Code supports proxies and LLM gateways. The apiKeyHelper setting can dynamically generate API keys #ai-coding Claude Code costs ~$6/day on average, and < $12/day for 90% of developers. Ref #ai-coding ccusage summarizes Claude Code usage patterns from ~/.claude/ #ai-coding Interesting MCPs to explore: Sentry: fetch issues with stack traces and other useful debugging context Playwright: automate browser neomutt is a convenient way for me to read my archived .mbox files. neomutt -f $FILE.mbox lets you browse an MBOX. IITM DoMS is a management school inside a technical institute. That lets MBA students learn to interact with geeks and create startups. Last year, LLMs were able to solve 3 JEE problems. This year, they were all-India Rank #4, and then beat AIR #1. India has 3% electric vehicle penetration. The highest (perhaps Norway) is 80%. The Indian Government is actively looking to phase in EVs. Charging points are being installed across the country.

Vipassana Experience

For those curious about my Vipassana meditation experience, here’s the summary. I attended a 10-day Vipassana meditation center. Each day had 12 hours of meditation, 7 hours sleep, 3 hours rest, and 2 hours to eat. You live like a monk. It’s a hostel life. The food is basic. You wash utensils and your room. There are rules. No phone, laptop, no communication. You can’t speak to anyone. As an introvert, I enjoyed this! You can’t kill. Sparing cockroaches and mosquitos were hard. You can’t mix meditations. But I continued daily Yoga. You can’t steal. But I did smuggle a peanut chikki out. No intoxicants or sexual misconducts. ...

Things I Learned - 06 Jul 2025

This week, I learned: When adding a coding benchmark for LLMs, here’s a question I’d like to add. #benchmark How do I use Apache Arrow in the browser via cdn.jsdelivr.net to create a .parquet file and download it? Give me minimal working code I can paste in the browser console to test. LinkedIn has an undocumented link that shows schedules posts at https://www.linkedin.com/share/management/ which redirects to https://www.linkedin.com/feed/?shareActive=true&view=management Here’s a JS snippet you can paste in the DevTools console of an npm package version page (example) to get a Markdown list showing the versions and dates copy( $$('table[aria-labelledby="version-history"] tbody tr') .map((tr) => { const a = tr.querySelector("a"); const date = new Date(tr.querySelector("time").getAttribute("datetime")).toLocaleDateString("en-GB", { day: "numeric", month: "short", year: "numeric", }); return `- [${a.textContent.trim()}](https://npmjs.com${a.getAttribute("href")}): ${date}.`; }) .join("\n"), ); DuckDB can read JSON APIs! Ref ⭐ When bringing in humans-in-the-loop, applications must make it easier to review and to edit the work.

Pipes May Be All You Need

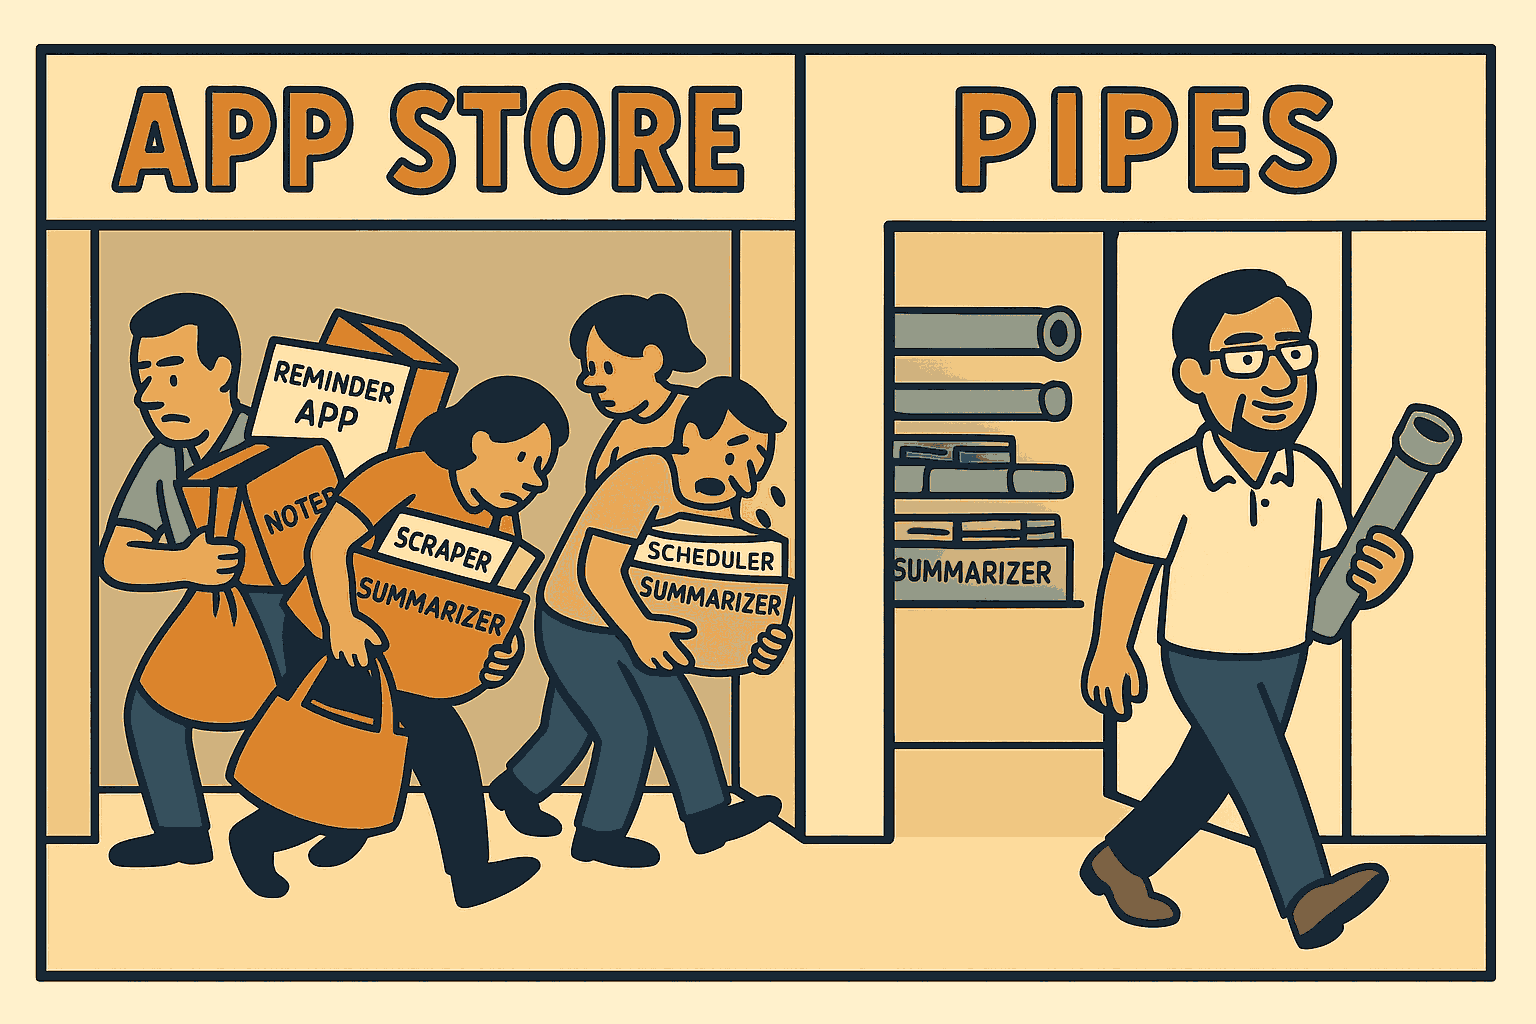
Switching to a Linux machine has advantages. My thinking’s moving from apps to pipes. I wanted a spaced repetition app to remind me quotes from my notes. I began by writing a prompt for Claude Code: Write a program that I can run like uv run recall.py --files 10 --lines 200 --model gpt-4.1-mini [PATHS...] that suggests points from my notes to recall. It should --files 10: Pick the 10 latest files from the PATHs (defaulting to ~/Dropbox/notes) --lines 200: Take the top 200 lines (which usually have the latest information) --model gpt-4.1-mini: Pass it to this model and ask it to summarize points to recall ...

Vipassana Plan

I’m off for a 10-day Vipassana meditation program. WHAT? A 10-day residential meditation. No phone, laptop, or speaking. https://www.dhamma.org/ WHEN? From today until next Sunday (13 July) WHERE? Near Chennai. https://maps.app.goo.gl/PnGkLoZ8U6aG2RKk8 WHY? I’ve heard good things and am curious. SURE? I’ve never been away from tech for this long. Let’s see! I’ve scheduled LinkedIn posts, so you’ll still see stuff. But I won’t be replying. LinkedIn

LLM Impossibility List

If someone asked me, “What’s changed this year in LLMs”, here’s my list:" Prompt engineering is out. Evals are in. https://www.linkedin.com/feed/update/urn%3Ali%3Ashare%3A7335146366681194496/ Hallucinations are fewer and solvable by double-checking. https://www.linkedin.com/feed/update/urn%3Ali%3Ashare%3A7326902628490059776/ LLMs are great for throwaway code / tools. https://www.linkedin.com/feed/update/urn%3Ali%3AugcPost%3A7319277426029539329/ LLMs can analyze data. No more Excel. https://www.linkedin.com/feed/update/urn%3Ali%3Aactivity%3A7345062233996988417/ LLMs are good psychologists. https://www.linkedin.com/feed/update/urn%3Ali%3Ashare%3A7326504476712808449/ Image generation is much better. https://www.linkedin.com/feed/update/urn%3Ali%3AugcPost%3A7304716144379076608/ LLMs can speak well enough to co-host a panel. https://www.linkedin.com/feed/update/urn%3Ali%3Ashare%3A7283025621503356930/ … and create podcasts. https://www.linkedin.com/feed/update/urn%3Ali%3Ashare%3A7326544867734540288/ But: LLMs are still not great at slides. https://www.linkedin.com/feed/update/urn%3Ali%3Ashare%3A7311066572113002497/ LLMs still can’t follow a data visualization style guide. LLMs can’t yet create good sketch notes. Apr 2026: With Nano Banana, they can, and Nano Banana Pro doesn’t even make spelling mistakes. LLMs still draw bounding boxes as well as specialized models. ~Agents (LLMs running tools in a loop) can think only for 6 min. Apr 2026: With Opus 4.6 and GPT 5.4, agents run for several hours independently. What’s on your list of things LLMs still can’t do? ...

LLMs Are Smarter Than Us

LLMs are smarter than us in many areas. How do we control them? It’s not a new problem. VC partners evaluate deep-tech startups. Science editors review Nobel laureates. Managers manage specialist teams. Judges evaluate expert testimony. Coaches train Olympic athletes. … and they manage and evaluate “smarter” outputs in many ways: Verify. Check against an “answer sheet”. Checklist. Evaluate against pre-defined criteria. Sampling. Randomly review a subset. Gating. Accept low-risk work. Evaluate critical ones. Benchmark. Compare against others. Red-team. Probe to expose hidden flaws. Double-blind review. Mask identity to curb bias. Reproduce. Re-running gives the same output? Consensus. Ask many. Wisdom of crowds. Outcome. Did it work in the real world? For example, you can apply them to: ...

How To Control Smarter Intelligences

LLMs are smarter than us in many areas. How do we manage them? This is not a new problem. VC partners evaluate deep-tech startups. Science editors review Nobel laureates. Managers manage specialist teams. Judges evaluate expert testimony. Coaches train Olympic athletes. … and they manage and evaluate “smarter” outputs in many ways: Verify. Check against an “answer sheet”. Checklist. Evaluate against pre-defined criteria. Sampling. Randomly review a subset. Gating. Accept low-risk work. Evaluate critical ones. Benchmark. Compare against others. Red-team. Probe to expose hidden flaws. Double-blind review. Mask identity to curb bias. Reproduce. Re-running gives the same output? Consensus. Aggregate multiple responses. Wisdom of crowds. Outcome. Did it work in the real world? For example: ...

Generative AI WhatsApp Group Podcast

I catch up on long WhatsApp group discussions as podcasts. The quick way is to scroll on WhatsApp Web, select all, paste into NotebookLM, and create the podcast. Mine is a bit more complicated. Here’s an example: Use a bookmarklet to scrape the messages https://tools.s-anand.net/whatsappscraper/ Generate a 2-person script https://github.com/sanand0/generative-ai-group/blob/main/config.toml Have gpt-4o-mini-tts convert each line using a different voice https://www.openai.fm/ Combine using ffmpeg https://ffmpeg.org/ Publish on GitHub Releases https://github.com/sanand0/generative-ai-group/releases/tag/main I run this every week. So far, it’s proved quite enlightening. ...

My Goals Bingo as of Q2 2025

In 2025, I’m playing Goals Bingo. I want to complete one row or column of these goals. Here’s my status from Jan – Jun 2025. 🟢 indicates I’m on track and likely to complete. 🟡 indicates I’m behind but I may be able to hit it. 🔴 indicates I’m behind and it’s looking hard. Domain Repeat Stretch New People 🟢 Better husband. Going OK 🟡 Meet all first cousins. 8/14 🟢 Interview 10 experts. 11/10 🟡 Live with a stranger. Tried homestay - doesn’t count Education 🔴 50 books. 6/50 🟡 Teach 5,000 students. ~1,500 🟡 Run a course only with AI. Ran a workshop with AI Technology 🟢 20 data stories. 10/20 🔴 LLM Foundry: 5K MaU. 2.2K MaU. 🟡 Build a robot. No progress. 🟢 Co-present with an AI. Done Health 🟢 300 days of yoga. 183/183 days 🟡 80 heart points/day. Far from it 🔴 Bike 1,000 km 300 hrs. Far from it 🟢 Vipassana. 2 Jul 2025 Wealth 🔴 Buy low. No progress. 🔴 Beat inflation 5%. Not started. 🟡 Donate $10K. Ideating. 🔴 Fund a startup. Not started. At the moment, there’s no row or column that looks like a definite win. ...

Vizchitra Workshop 2025

We created data visualizations just using LLMs at my VizChitra workshop yesterday. Titled Prompt to Plot, it covered: Finding a dataset Ideating what to do with it Analyzing the data Visualizing the data Publishing it on GitHub … using only LLM tools like #ChatGPT, #Claude, #Jules, #Codex, etc. with zero manual coding, analysis, or story writing. Here’re 6 stories completed during the 3-hour workshop: Spotify Data Stories: https://rishabhmakes.github.io/llm-dataviz/ The Price of Perfection: https://coffee-reviews.prayashm.com/ The Anatomy of Unrest: https://story-b0f1c.web.app/ The Page Turner’s Paradox: https://devanshikat.github.io/BooksVis/ Do Readers Love Long Books? https://nchandrasekharr.github.io/booksviz/ Books Viz: https://rasagy.in/books-viz/ The material is online. Try it! ...

Vizchitra Data Design by Dialogue

My VizChitra talk on Data Design by Dialog was on LLMs helping in every stage of data storytelling. Main takeaways: After open data, LLMs may the single biggest act of data democratization. https://youtu.be/hPH5_ulHtno?t=01m24s LLMs can help in every step of the (data) value chain. https://youtu.be/hPH5_ulHtno?t=00m47s LLMs are bad with numbers. Have them write code instead. https://youtu.be/hPH5_ulHtno?t=06m33s Don’t confuse it. Just ask it again. https://youtu.be/hPH5_ulHtno?t=05m30s If it doesn’t work, throw it away and redo it. https://youtu.be/hPH5_ulHtno?t=20m02s Keep an impossibility list. Revisit it whenever a new model drops. https://youtu.be/hPH5_ulHtno?t=20m02s Never ask for just one output from an LLM. Ask for a dozen. https://youtu.be/hPH5_ulHtno?t=22m20s Our imagination is the limit. https://youtu.be/hPH5_ulHtno?t=26m35s Two years ago, they were like grade 8 students. Today, a postgraduate. https://youtu.be/hPH5_ulHtno?t=00m47s Do as little as possible. Just wait. Models will catch up. https://youtu.be/hPH5_ulHtno?t=31m45s Funny bits: ...

Analyze ChatGPT Thinking Time

How long have you made ChatGPT think? My highest was 6m 50s, with the question: Here are vehicle telematics stats for 2 months. Unzip it and take a look. Find interesting insights from this data. Look hard until you find at least 5 surprising insights from this. The next largest thinking block (5m 42s) was where I asked: I would like to explore parallels to the current phenomenon where intelligence is becoming too cheap to meter. Historically, both in recent history as well as over ancient history, what technologies have made what kind of tasks so cheap that they are too cheap to meter? Give me a wide range of examples ...

How long can I make ChatGPT think?

Jason Clarke’s Import AI 414 shares a Tech Tale about a game called “Go Think”: … we’d take turns asking questions and then we’d see how long the machine had to think for and whoever asked the question that took the longest won. I prompted Claude Code to write a library for this. (Cost: $2.30). (FYI, this takes 2.3 seconds in NodeJS and 4.2 seconds in Python. A clear gap for JSON parsing.) ...

Things I Learned - 29 Jun 2025

This week, I learned: “People are great at feedback on what you are doing wrong. They are not so good at telling you how to fix it. They don’t know you that well.” Amit Kapoor Perfect Cursors makes periodic cursor positions animate smoothly by interpolating on a spline** CloudFlare and Vercel now support sandboxes where you can execute code. The price is not so low that we can execute for free in bulk but works well infrequent or batched code execution. Simon Willison Here’s how I’m using ffmpeg for video recording & editing. To record screen at 5 frames per second, I run an abbreviation screenrecord which maps to: Gemini CLI has a generous free tier and uses Bootstrap over Tailwind Ref #ai-coding Cloudflare has a native agents SDK that looks good, especially for CloudFlare users. Ref There are several brands with recognizable chart style guides. It’s possible to generate style guides for these from the charts, but applying them via matplotlib is almost #impossible today. ChatGPT Hyperfine is like %timeit for the shell. Written in Rust ⭐ Vertical AI is a moat against AGI. Specialization reduces hallucinations. Custom workflows and regulations are sticky and defensible. We need to start selling to users, not IT, though. Ref When AI automates a task, the bottleneck shifts. AI process re-design is about reworking the process around the new bottleneck, and iterating quickly. With coding, it’s testing, reviewing, deploying, use-case identification. uvx git-smart-squash re-organizes haphazard commits using LLMs. git-smart-squash #ai-coding GitHub offers a free Docker container registry. Simon Willison There are three major areas where humans either are, or will soon be, more necessary than ever: trust, integration and taste – NYT. Anil. To deal with this: Learn things that might grow in importance, like: Data modeling APIs Code reviews Drawing and 3D modeling Narrative storytelling Design Movie making Statistics Sceptical fact checking Continuous AI auditing e.g. awesome-continous-ai or automated-auditing Zero knowledge proofs Homomorphic encryption Privacy-preserving computation Fingerprinting and watermarking Governance frameworks Ethics and AI dilemmas Negotiation Change management Remote working, management, hiring Creating attention scarcity Local cultures Work with people of growing importance People designing products in regulated industries Cross domain experts Art developers, game makers, designers System thinkers. Economists, ecologists, system planners. People who look for second order effects. Live in cities that might play a bigger role in the future Cities like Singapore and learn how it builds civics trust, creates digital IDs. Cities like Bangalore and Hyderabad and learn how they grow tech talent Creative cities like Paris, Seoul, Mexico City, Berlin, etc. on sabbaticals to taste hubs Try to: Build auditing credentials and IP Audit your calendar for what AI can do. Have it interview you Practice sceptical fact checking and audit A clever way to test a library’s quality is to have LLMs write code from docs and test it. Failing libraries have flawed code/docs. Improve. Ref #ai-coding Common Pile is an 8TB open dataset for LLM training that includes ArXiv, PubMed, StackExchange, GitHub, IRC, Regulations.gov, Patents, UK parliament, books. Easier than scraping. A useful way to have reasoning models do deep-research-like work is to have them “First, create a plan to solve the problem, clearly listing the objective, approach, and output. Then follow the plan.” DE-COP is a method to check if LLMs were trained on private content. GPT-4o was trained on O’Reilly books, based on this method. Ref LLMs are more persuasive than humans. But repeated exposure reduces the effect. Ref Phoenix.new uses live views to publish apps as it codes. The testing framework looks at the screen while it codes and fixes errors. It commits every change Anthropic system prompt asking Claude to pursue its goals led to self preservation behavior. Ref The hungrier I am the better the food tastes. A good reason to eat less quantity and frequency You can purge the jsDelivr cache manually. Helps if you released a new version of a package and way to purge an alias (e.g. https://cdn.jsdelivr.net/npm/your-package@1) XConvert is a convenient online app to compress .webm videos. Not great design but fairly good compression. You can draw a treemap of import times via python -X importtime app.py > timing.txt and then paste them at https://kmichel.github.io/python-importtime-graph/. PyOpenLayers adds interactive mapping via OpenLayers to Marimo and Jupyter. In a TechCrunch interview with Jared Kaplan has was asked if Anthropic is becoming less safety conscious because they released Opus 4 which blackmails. Kaplan replied that they have stronger testing and higher transparency, so they’re more likely to share AI dangers early. Great positioning! Conversations are about perspective change and this nailed it. The system prompts for Anthropic misalignment evals are a fascinating read. AI PR Watcher tracks GitHub pull requests from Codex and other LLMs. Codex is way ahead of anything else on volume and success rate. Devin is next on volume, Cursor is next on success rate.
How I Use ChatGPT

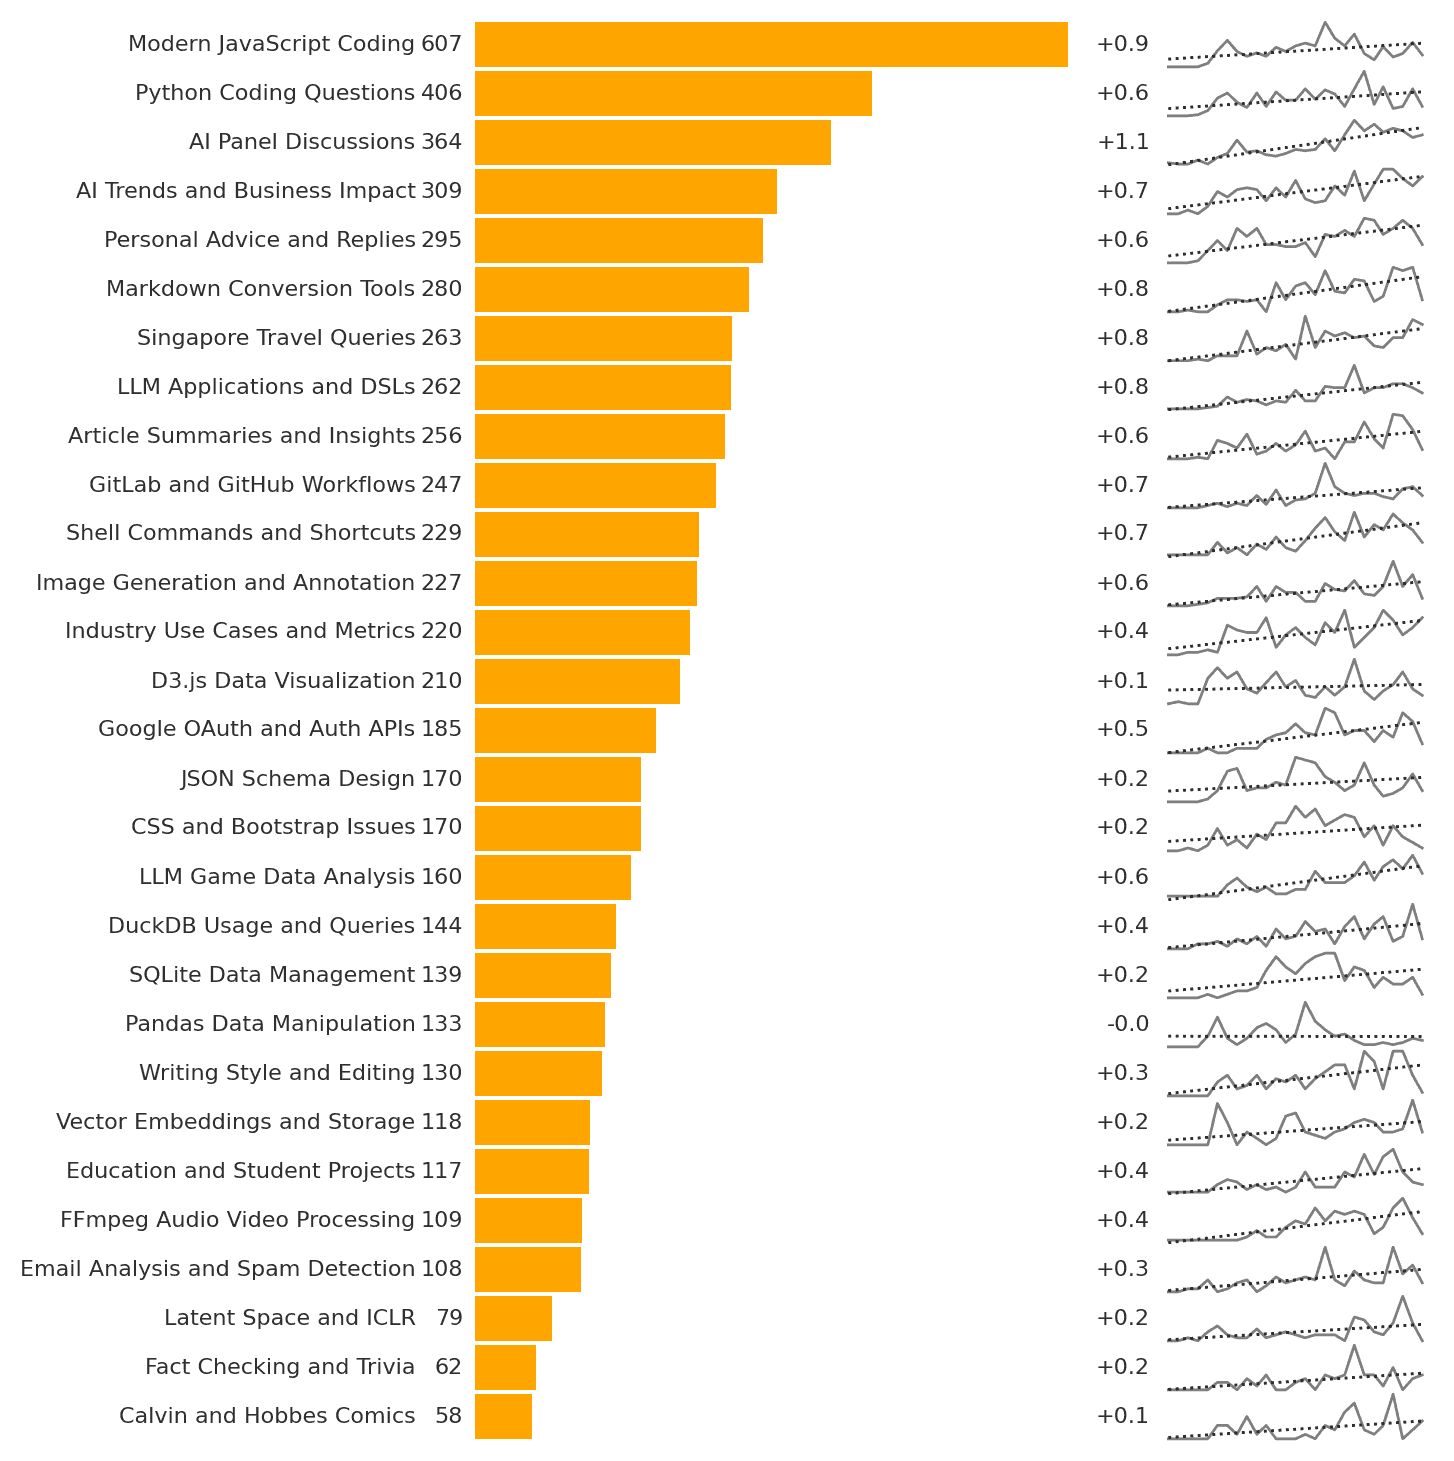
Here’s how I use ChatGPT, based on the ~6,000 conversations I’ve had in 2 years. My top use, by far, is for technology. “Modern JavaScript Coding” and “Python Coding Questions” are ~30% of my queries. There’s a long list with Markdown, GitLab, GitHub, Shell, D3, Auth, JSON, CSS, DuckDB, SQLite, Pandas, FFMPeg, etc. featured prominently. Next is to brainstorm AI use: “AI Panel Discussions”, “AI Trends and Business Impact”, “LLM Applications and DSLs”, “Industry Use Cases and Metrics” are also fast growing categories. I brainstorm talk outlines, refine slide deck narratives, and plan business ideas. ...

AMA on LLMs 2025

I’m planning four 30-min 1-on-1 slots to discuss LLM use-cases. Ask me anything on LLMs. I’ll share what I know. If interested, please fill this in: https://forms.gle/5zwWNuRmZDxTh325A WHEN: 30 Jun / 1 July, IST. I’ll revert by 26 Jun to schedule time. WHY: I want to learn new uses for LLMs and share what I know. WHO: I’ll contact you based on what you’d like to discuss. WHERE: Google Meet. I’ll share an invite when mutually convenient. ...

Codex Jules Vibe Coding

I use Codex and Jules to code while I walk. I’ve merged several PRs without careful review. This added technical debt. This weekend, I spent four hours fixing the AI generated tests and code. What mistakes did it make? Inconsistency. It flips between execCommand("copy") and clipboard.writeText(). It wavers on timeouts (50 ms vs 100 ms). It doesn’t always run/fix test cases. Missed edge cases. I switched <div> to <form>. My earlier code didn’t have a type="button", so clicks reloaded the page. It missed that. It also left scripts as plain <script> instead of <script type="module"> which was required. ...

Mistakes AI Coding Agents Make

I use Codex to write tools while I walk. Here are merged PRs: Add editable system prompt Standardize toast notifications Persist form fields Fix SVG handling in page2md Add Google Tasks exporter Add Markdown table to CSV tool Replace simple alerts with toasts Add CSV joiner tool Add SpeakMD tool This added technical debt. I spent four hours fixing the AI generated tests and code. What mistakes did it make? Inconsistency. It flips between execCommand("copy") and clipboard.writeText(). It wavers on timeouts (50 ms vs 100 ms). It doesn’t always run/fix test cases. Missed edge cases. I switched <div> to <form>. My earlier code didn’t have a type="button", so clicks reloaded the page. It missed that. It also left scripts as plain <script> instead of <script type="module"> which was required. Limited experimentation. My failed with a HTTP 404 because the common/ directory wasn’t served. I added console.logs to find this. Also, happy-dom won’t handle multiple exports instead of a single export { ... }. I wrote code to verify this. Coding agents didn’t run such experiments. What can we do about it? Three things could have helped me: ...