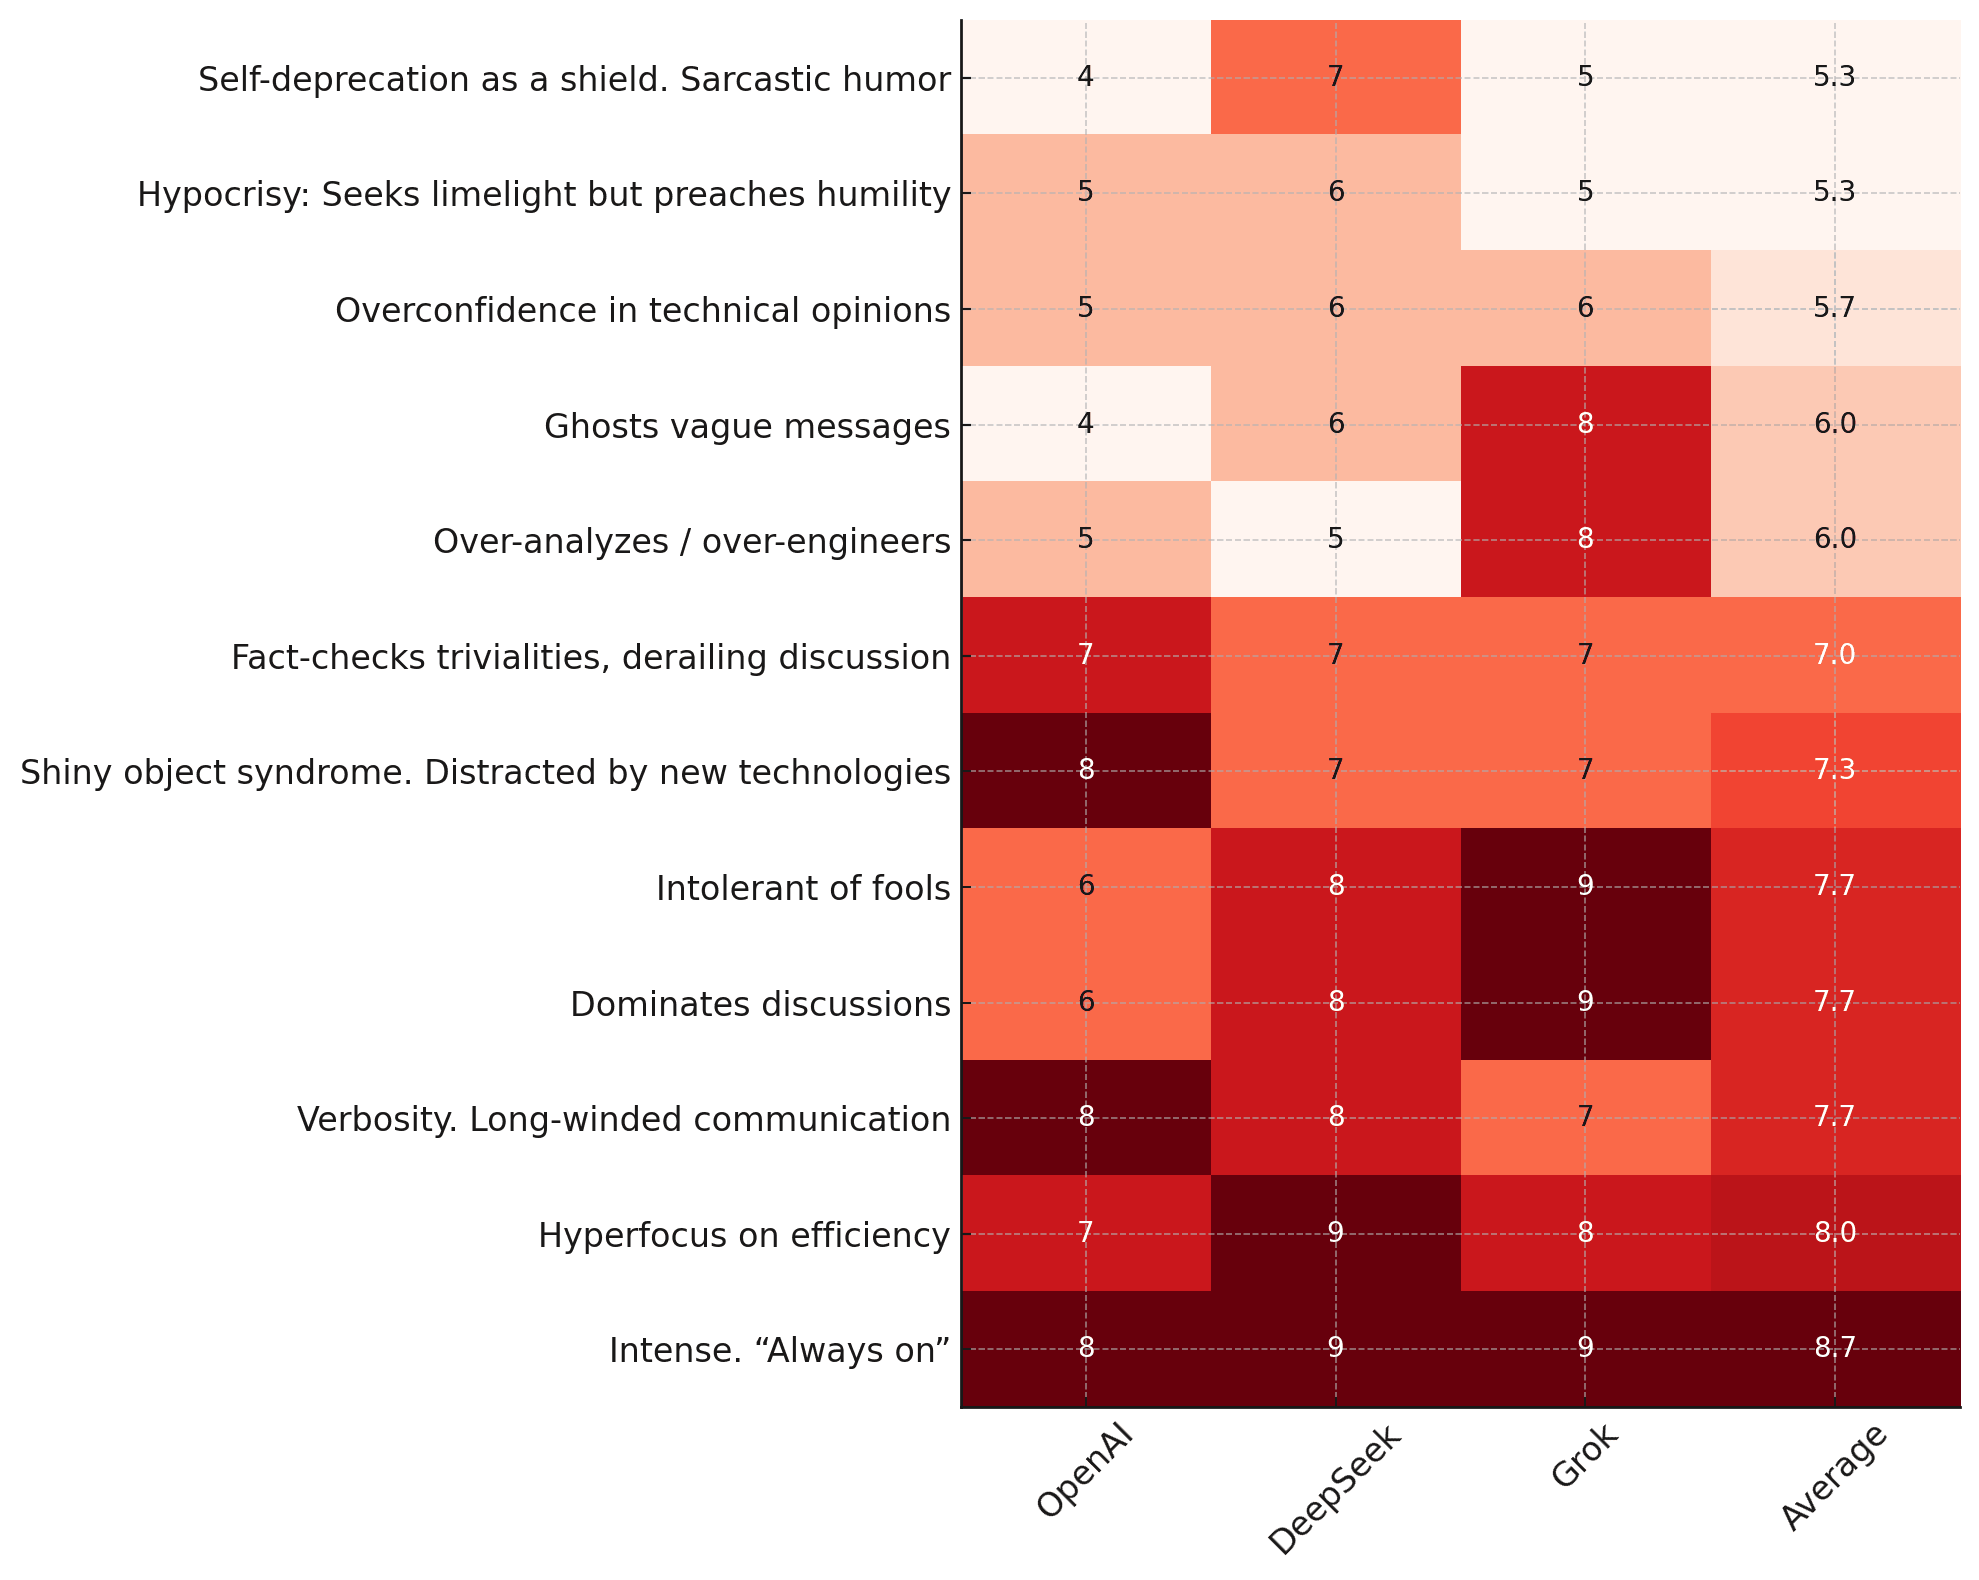
After ChatGPT's discussion of my personality flaws, I asked it to listing specific conversations as evidence for flaws. Then I asked 3 LLMs to rate the evidence.
Personality FlawChatGPTDeepSeekGrokAverageSelf-deprecation as a shield. Sarcastic humor4755.3Hypocrisy: Seeks limelight but preaches humility5655.3Overconfidence in technical opinions5665.7Ghosts vague messages4686.0Over-analyzes / over-engineers5586.0Fact-checks trivialities, derailing discussion7777.0Shiny object syndrome. Distracted by new technologies8777.3Intolerant of fools6897.7Dominates discussions6897.7Verbosity. Long-winded communication8877.7Hyperfocus on efficiency7988.0Intense. “Always on”8998.7 🟢 LOW: Self-deprecation / sarcastic humour as shield ChatGPT: 4/10. Bio and a few quips reveal dry self-mockery, yet direct chat evidence of humour as defence is sparse; it surfaces only occasionally. | DeepSeek: 7/10. Explicit self-awareness goals and dry humor noted, but little evidence of defensive/sarcastic use. Grok: 5/10. Some self-deprecating humor exists, but its use as a shield is not strongly supported. 🟢 LOW: Hypocrisy: seeks limelight yet preaches humility ChatGPT: 6/10. You aspire to humility but routinely headline conferences and TEDx talks; the coexistence of public speaking and stated modesty gives the charge a middling footing. | DeepSeek: 6/10. TEDx/PyCon prominence contrasts with stated humility goals, though self-improvement efforts are genuine. Grok: 5/10. Public speaking contrasts with humility goals, though this may indicate self-awareness, not hypocrisy. 🟢 LOW: Over-confidence in technical opinions ChatGPT: 7/10. You assert strong views (e.g., Node vs FastAPI) but also invite verification and accept corrections, yielding only moderate evidence of over-confidence. | DeepSeek: 6/10. States strong preferences upfront but routinely invites validation and course-corrects. Grok: 6/10. Strong opinions are expressed, but openness to correction moderates the perception of overconfidence. 🟢 LOW: Ghosts vague messages ChatGPT: 5/10. You’ve stated you ignore low-context e-mails, but chat logs show you usually follow-up or clarify rather than disappear. | DeepSeek: 6/10. Documented tendency to ignore low-context questions, though chat logs show active clarification habits. Grok: 8/10. Multiple instances show the user ignoring or not responding to unclear or low-context messages. 🟢 LOW: Over-analyzes / over-engineers ChatGPT: 5/10. Designing auto-re-flow SVG chevrons and exhaustive RAG specs hint at depth beyond the simple solution, yet you also champion “smallest libraries” and lightweight rate-limiters. | DeepSeek: 5/10. Some prototype/structuring tendencies, but strong preference for minimal solutions counterbalances this. Grok: 8/10. The user often dives deeply into tasks, sometimes creating complex solutions for simple problems. 🟡 MEDIUM: Fact-checks trivialities, derailing discussion ChatGPT: 8/10. Many requests revolve around “double-check,” “fact-check,” or recalculating tiny details, which lengthens threads even when stakes are small. | DeepSeek: 7/10. Frequent accuracy demands and citation hunts elongate discussions, but stays focused when content is solid. Grok: 7/10. Evidence of prioritizing precision, like fact-checking minor details, can disrupt conversation flow. 🟡 MEDIUM: Shiny-object syndrome ChatGPT: 6/10. Parallel explorations of Godot, Matrix, Cloudflare Workers, SVG SmartArt, esp32-eye, etc. reveal a persistent pull toward new tech before finishing earlier threads. | DeepSeek: 7/10. Broad simultaneous explorations (Godot/WASM/DuckDB), though sustains core projects long-term. Grok: 7/10. Exploration of new technologies is frequent, but focus on core projects suggests a balanced curiosity. 🟡 MEDIUM: Intolerant of fools / low clarity ChatGPT: 7/10. Frequent demands for precise formats, citations, and “be specific” instructions show a low tolerance for ambiguity, though you still help patiently on non-technical questions. | DeepSeek: 8/10. Strong pattern of rejecting ambiguity/fluff, though softened by humor and non-technical engagements. Grok: 9/10. The user consistently demands clarity and efficiency, showing little patience for ambiguity or fluff. 🟡 MEDIUM: Dominates discussions ChatGPT: 4/10. Long, multi-part prompts and the need for TL;DRs suggest you can overshadow lighter voices, but you periodically insist on brevity and delegate tasks, tempering the effect. | DeepSeek: 8/10. Long technical messages (avg ~3k chars) and intense Q&A patterns create conversational dominance. Grok: 9/10. Detailed, technical responses consistently steer and dominate conversations. 🟡 MEDIUM: Verbosity / long-winded communication ChatGPT: 5/10. Average messages run several thousand characters, and you often request exhaustive, multi-section outputs—though you sometimes tell the assistant “Shorter please,” verbosity remains a clear pattern. | DeepSeek: 8/10. Multi-step technical requests dominate interactions, though periodic “shorter please” self-corrections exist. Grok: 7/10. Messages are often lengthy and detailed, though the user also requests concise responses from others. 🔴 HIGH: Hyper-focus on efficiency ChatGPT: 8/10. Recurrent themes—cost monitoring, smallest-lib preference, GPU-utilization alerts—show you relentlessly optimise workflows and expect others to keep pace. | DeepSeek: 9/10. Unambiguous prioritization of concise formats, minimal libraries, and metric-driven optimization. Grok: 8/10. Repeated emphasis on concise, efficient communication and minimal tools is evident. 🔴 HIGH: Intense – “always on” ChatGPT: 8/10. Around-the-clock, multi-topic requests (weekend cron jobs, 2 a.m. prototypes) portray sustained high energy, with only a few calmer “travel nerves” moments as counter-weight. | DeepSeek: 9/10. High-volume technical queries across domains, 6am research routines, and rapid prototyping habits. Grok: 9/10. High energy and engagement are consistently shown through task initiation and scheduling. My actions: Learn from fools and focus on the big-picture. Specifically:
...