Watching videos with a phone case

Two months ago, I was impressed at the ingenuity of a lady who used a plastic cover to watch videos on a flight. Today, on the same Indigo flight from Singapore to Chennai, I saw a man one seat ahead of me use the headrest cover on the seat in front to watch videos. (The headrest cover is the cloth behind your head on airline seats. It saves cleaning effort.) ...

My predictions in 2025

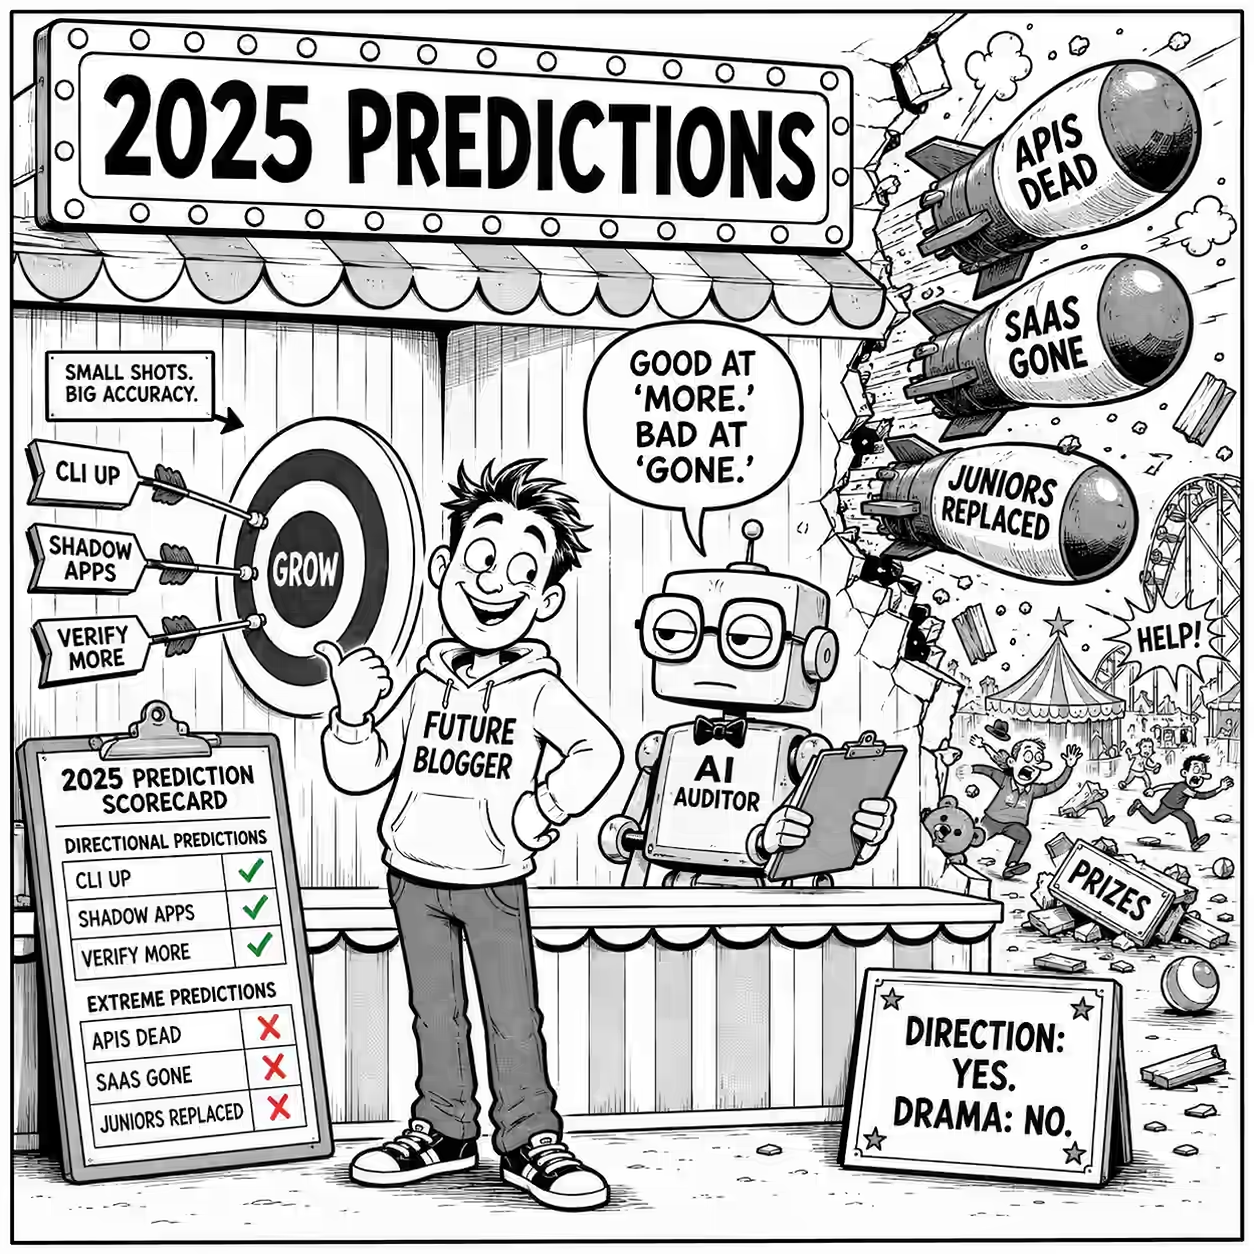
In 2025, I made a number of predictions on this blog. (Not intentionally. I just said stuff.) I asked ChatGPT to audit them. It selected 440 claims, filtered out vague or pending ones, and verified the rest. Here’s what I got right and wrong. 🟢 “My chat will overtake search in 12-18 months. When ChatGPT becomes my primary lens on knowledge…” (chatgpt-vs-google-usage.md:L27). Audit: This actually happened in your own browsing data: search led through April 2026; in May, chat jumped to 2,211 visits vs 1,319 search visits, and stayed comfortably ahead thereafter. 🟢 “Typed languages are better suited for vibe coding. This will likely lead to the growth of typed languages (TypeScript, Rust, Go) but also of typing in untyped languages (e.g. Python).” (things-i-learned-10-aug-2025.md:L33). Audit: TypeScript became GitHub’s #1 language in August 2025 and grew 66% YoY; GitHub itself explicitly connects the rise of typed languages to more reliable AI-assisted coding. This is unusually strong because you got both the direction and mechanism. (The GitHub Blog) 🟢 “Code Mode … is a smart way to use MCPs and a very likely future direction. Using LLMs to write code to call MCPs rather than directly.” (things-i-learned-05-oct-2025.md:L49). Audit: OpenAI’s current Responses API has essentially this as a named capability: Programmatic Tool Calling lets a model write and execute programs that coordinate multiple tools and intermediate results. (OpenAI) 🟢 “CLI optimization for LLMs will likely emerge. More CLIs (and wrappers / hooks in the shell) will improve output and error contexts for LLMs…” (things-i-learned-27-jul-2025.md:L86). Audit: By May 2026 you were yourself testing rtk, a CLI proxy explicitly producing compact agent-friendly command output; across 216 commands you measured about 50% token reduction. That is almost exactly the wrapper you predicted. 🟢 “In the future, AI that works directly with file systems, Model Context Protocols, and local APIs are likely to become more important.” (features-actually-used-in-an-llm-playground.md:L76). Audit: File-system-native coding agents became mainstream, while MCP expanded into both hosted and local integrations; Anthropic now packages local MCP servers as easy-to-install desktop extensions. (Claude Help Center) 🟢 “Agents are slow. Parallelizable tools … will grow. Tool speed … will become more important.” (things-i-learned-22-jun-2025.md:L106). Audit: Parallelism has become a central agent UX: OpenAI’s Codex app is explicitly built around managing multiple agents simultaneously; at the extreme, internal users now accumulate more than 60 hours of agent turns per day by parallel execution. (OpenAI) 🟢 “Companies-of-one will grow. Sole founder can handle support functions.” (things-i-learned-24-aug-2025.md:L14). Audit: Nasdaq’s Economic Institute finds one-person US business applications up more than 20% since early 2025, with essentially all recent application growth coming from solo businesses. Stripe separately reports solo founders reaching 63% of Atlas C-corps in Q2 2026. (Nasdaq) 🟢 “We will move towards an organization structure where developers are embedded with business teams rather than working as a separate group. Sort of like embedded executive assistance instead of a central typing pool.” (things-i-learned-08-jun-2025.md:L49). Audit: Forward-deployed engineer demand reportedly increased 42-fold from 2023-25, with roughly 9,000 roles globally by early 2026. The role is almost precisely “technical people embedded with the business to make AI work in its real environment.” (Reuters) 🟢 “Shadow apps will grow. Anyone can code. Users build apps with prompts, sheets, agents, outside of IT SDLC. Like Excel sheets.” (things-i-learned-24-aug-2025.md:L18). Audit: Microsoft now explicitly describes a “new wave of shadow AI”: users installing coding/desktop/SaaS agents outside traditional IT governance, and has built discovery products specifically for unmanaged AI applications and agents. (Microsoft) 🟡 “Agents generate diffs/PRs. Tools to edit and comment on these online will emerge.” (things-i-learned-22-jun-2025.md:L107). Audit: GitHub now measures PRs created and merged by Copilot coding agent, while review comments can be handed directly to the agent with “Fix with Copilot,” including batches of review feedback. That’s almost verbatim fulfillment. (The GitHub Blog) 🟡 “Models’ ability to orchestrate longer workflows will improve. Factor that into your application design.” (things-i-learned-10-aug-2025.md:L44). Audit: By mid-2026, OpenAI reports large increases in requests corresponding to >30-minute, >1-hour and even >8-hour human tasks, while Codex explicitly targets long-running tasks spanning hours or longer. (OpenAI) 🟡 “Code review process will be re-invented.” (things-i-learned-22-jun-2025.md:L109). Audit: GitHub has rebuilt Copilot review around an agentic architecture that gathers broader repository context, uses tools, produces findings, and can hand fixes to another coding agent. This is substantially more than autocomplete added to old review. (The GitHub Blog) 🟡 “Domain expertise will therefore become even more valuable in the near future.” (things-i-learned-20-apr-2025.md:L39). Audit: 2026 hiring evidence points toward domain/product expertise becoming more important rather than pure coding alone, particularly as AI handles more implementation and firms need people who can connect it to actual business functions. (Reuters) 🟡 “Validation is the New Bottleneck: Since coding is now much faster, the critical, time-consuming task has shifted to reviewing, testing, and validating the LLM’s output.” (things-i-learned-17-aug-2025.md:L90); you also predicted “The Quality Control (QC) function will become larger and more critical” (L95). Audit: GitHub has now productized exactly that bottleneck in Code Quality; more than 10,000 enterprises used its preview, and GitHub explicitly frames AI-accelerated code output as creating the need for trustworthy pre-merge quality validation. (The GitHub Blog) 🟡 “Agents generate technical debt faster than humans. Solving this will become a major problem/opportunity.” (things-i-learned-22-jun-2025.md:L114). Audit: GitHub’s 2026 Code Quality launch is close to a commercial instantiation of this forecast: AI increases code output, so automated quality/debt detection and remediation moves earlier into the development cycle. (The GitHub Blog) 🟡 “Governance will grow. Non-experts are acting like experts. Validation is more important.” (things-i-learned-24-aug-2025.md:L19). Audit: The companion to shadow AI has indeed been governance: Microsoft now ships specific discovery, monitoring and governance for unmanaged AI agents, while NIST has continued expanding formal GenAI evaluation tooling. (Microsoft Learn) 🟡 “Soon, we won’t just follow a lesson plan – we’ll have lessons built just for us. AI will track how we learn and adapt in real time. It’ll feel like having a personal coach in your back pocket.” (o3-is-now-my-personalized-learning-coach.md:L91). Audit: ChatGPT Study Mode now asks what the learner knows, adapts explanations, checks understanding, works from uploaded course material, and uses memory to personalize support; OpenAI explicitly describes the objective as personalized learning support available to any student. (OpenAI Help Center) 🟡 “Cost is going down so quickly right now that all you have to do is wait, and stuff will become available for a very affordable or even a free price.” (things-i-learned-16-mar-2025.md:L116). Audit: The broad direction held. OpenAI cut GPT-5.6 Luna API prices by 80% in July 2026 while simultaneously improving capability-per-dollar. The “all you have to do” part is hyperbole, but the price-curve forecast was right. (OpenAI) 🟡 relayed: “Control of chips and GPU compute is what will likely be the gameplay to control AI dominance globally.” (things-i-learned-02-feb-2025.md:L16, attributed there to Dario Amodei). Audit: Advanced-AI-chip export licensing remains an explicit geopolitical control mechanism in 2026, including restrictions and license review for H200/MI325X-class accelerators going to China. 🔴 “AI closes the gap between junior & senior devs – even when both use AI. Quality doesn’t suffer much. So onboarding can be faster, compensation ladder may shorten.” (things-i-learned-03-aug-2025.md:L52). Audit: The emerging evidence says AI changes the work but does not erase the expertise gap: experienced developers are better at steering/delegation, while low-experience AI-heavy contributions incur substantially more review and lower acceptance. (arXiv) 🔴 “LLMs already deliver hours of analyst work in minutes. Entry-level roles WILL vanish.” (goodbye-mba-hello-ai.md:L17). Audit: The labor-market warning was directionally good, but “vanish” is a major magnitude error. Stanford finds a meaningful relative decline among 22-25-year-olds in highly AI-exposed jobs, while employment remains substantial and overall exposure groups still show employment growth. “Entry-level hiring contracts sharply” would have scored much better. (Stanford Digital Economy Lab) 🔴 “Coders micro-manage LLMs. I think a novice will be more efficient and get better results than me.” (how-to-visualize-data-stories-with-ai-lessons.md:L285). Audit: Current empirical work points the other way in real software work. In a 22,953-PR study, lower-experience AI-heavy developers received 4.5* more review comments, had 31% lower acceptance, and took over 5* longer to resolve issues; qualitative work likewise finds experienced developers better at delegation and control. (arXiv) 🔴 relayed: “API access from model providers will shrink. Selling tokens is not a viable business model given lowering costs.” (things-i-learned-23-mar-2025.md:L19, from the Alexander Doria notes immediately above it). Audit: Almost exactly backwards. Model providers expanded their APIs into richer agent platforms, and token-metered API access remains a core commercial model - including premium pay-as-you-go modes. (OpenAI) 🔴 “APIs are likely to be replaced by just chat requests that will do the same thing. APIs might be replaced by RPA, where somebody uses a chatbot to do the equivalence instead.” (things-i-learned-16-mar-2025.md:L111-L112). Audit: Chat did become a front end, but the implementation moved toward more APIs underneath, not fewer: tool APIs, Responses, MCP, computer-use interfaces and programmatic tool calling are now the substrate agents use. (OpenAI) 🔴 “Software companies build ‘SaaS’-like apps today. Agents will replace apps. Instead of UI, workflows, and app logic, they’ll engineer prompts, APIs, and evals.” (agents-will-replace-saas-apps.md:L12). Audit: The interface-shift was right; “replace” was not. Gartner now forecasts agentic AI may expose roughly 20% of SaaS application spending by 2030 - meaning substantial disruption, not app extinction. Agents are often a new interaction layer over systems of record and APIs. (Gartner) 🔴 relayed: Models will “internalis[e] workflows … to wipe out the apps and workflow space.” (things-i-learned-23-mar-2025.md:L17, from Alexander Doria notes). Audit: “Internalize capabilities” was insightful; “wipe out” was the failed extrapolation. Enterprise applications remain a very large substrate even in Gartner’s fairly aggressive agentic-AI forecast. (Gartner) 🔴 “Demand for SaaS (one-size-fits-all) will shrink.” (things-i-learned-06-apr-2025.md:L89). Audit: Not yet. For example, Gartner forecasts Indian SaaS spending growing 18.9% in 2026, from $3.9B to $4.6B. AI is changing SaaS economics and seat licensing, but current demand is still growing rather than shrinking. (Gartner) 🔴 “The early majority have come in… Soon the late majority will come in asking for existing solutions that have already solved their problem for many others.” (things-i-learned-03-aug-2025.md:L44). Audit: This mapped your client/audience experience onto population adoption much too quickly. In 2026, US Census data put business AI usage around 17-20%, nowhere near a conventional late-majority phase. (Census.gov) 🔴- baseline error: “Given the cost and accessibility of drones, I guess drone terrorist attacks will soon emerge.” (things-i-learned-16-nov-2025.md:L43). Audit: They had already emerged. The UK government documented Daesh using small armed remotely piloted aircraft carrying grenades in Iraq in 2017; the UN had already been studying weaponized UAS use by non-state armed groups for terrorism-related purposes before this 2025 post. This is therefore a clean failure to establish the baseline, not a future hit. (GOV.UK) 🔴 relayed: “Personal writing with connection won’t go away. AI can’t give you heartbreak. But the rest of non fiction writing will vanish.” (things-i-learned-30-mar-2025.md:L69, under “Notes from Writing with AI”). Audit: Nonfiction is under real pressure, but “vanish” is nowhere close. UK nonfiction publishing still generated about GBP1.0B in 2025, down only 3%; the wider publishing industry reached record revenue. (Publishers Association) Legend: ...
Things I Learned - 16 Aug 2026

This week, I learned: psub is a neat fish option to treat command outputs like file inputs. E.g. diff (sort a.txt | psub) (sort b.txt | psub) More anchor points on how much text to ask AI for: … in 200-300 words (about 1 book page) … in ~1 A4 sheet (~500 words) … in ~3 minute of conversational Grade 8 reading (~500 words) I usually log things in a single file rather than split things into yearly, monthly, etc. A single file is more portable, scannable, and, for human logs, gives a feeling of accomplishment. I split when the file gets so unwieldy that it actually hurts - which is a good thing because it means I’m actually using it (maybe?) - and splitting beforehand may be good planning but is also premature optimization, adding friction to a nascent, fragile process. (This idea is pretty generalizable.) Claude models launched after 2 Aug 2026 “weaves an imperceptible watermark directly into the text itself. You won’t see it, and it doesn’t change the meaning, quality, or readability of Claude’s response.” How Claude marks AI-generated content. VS Code has built-in dictation. It uses nemotron-3.5-asr-streaming-0.6b by default #ForNow, and it’s pretty good. I expect I’ll use it a lot more, since most of my typing is in VS Code anyway. Ctrl + Alt + V toggles dictation. Dictation is also supported in the terminal and is trained to recogni I had an interesting moment today when I asked ChatGPT to identify which of my ChatGPT conversations were the most effective. I gave it access to my computer and it started using the browser to scrape itself so aggressively that I stopped it from it banned itself! GeoLibre looks like a full-fledged GIS. It’s open source and runs directly in the browser. When installing tools with mise, if it messes up the platform, you can explicitly specify it. For example: mise use -g 'github:pranshuparmar/witr[asset_pattern=witr-linux-amd64,bin=witr]@latest'. Mise Docs I saw this snippet from Claude Code: await Promise.race([document.fonts.ready, new Promise((r) => setTimeout(r, 3000))]); That waits for up to 3 seconds for the fonts to load. Didn’t know about Promise.race() before. It’s different from Promise.any() in that .race() will return the first result while .any() will return the first success. Measure the verification / follow-up tax in your AI work. AI does things fast. You have to take the next step. It helps to tag items with how long they’d take to verify or action. We do for specification, because we have to do that now, before telling AI. But I typically ignore the deferred tax. A theme is emerging: “Human attention needs reciprocity. If you ask for someone’s attention, first demonstrate your own effort.” Example: “people really don’t like when a coworker’s chatgpt contacts them asking for help with a task, even when they’d be perfectly happy doing that same work if asked by that coworker.” Greg Brockman Questions I was asked Week ending 16 Aug 2026 ...

Should we fix poor design

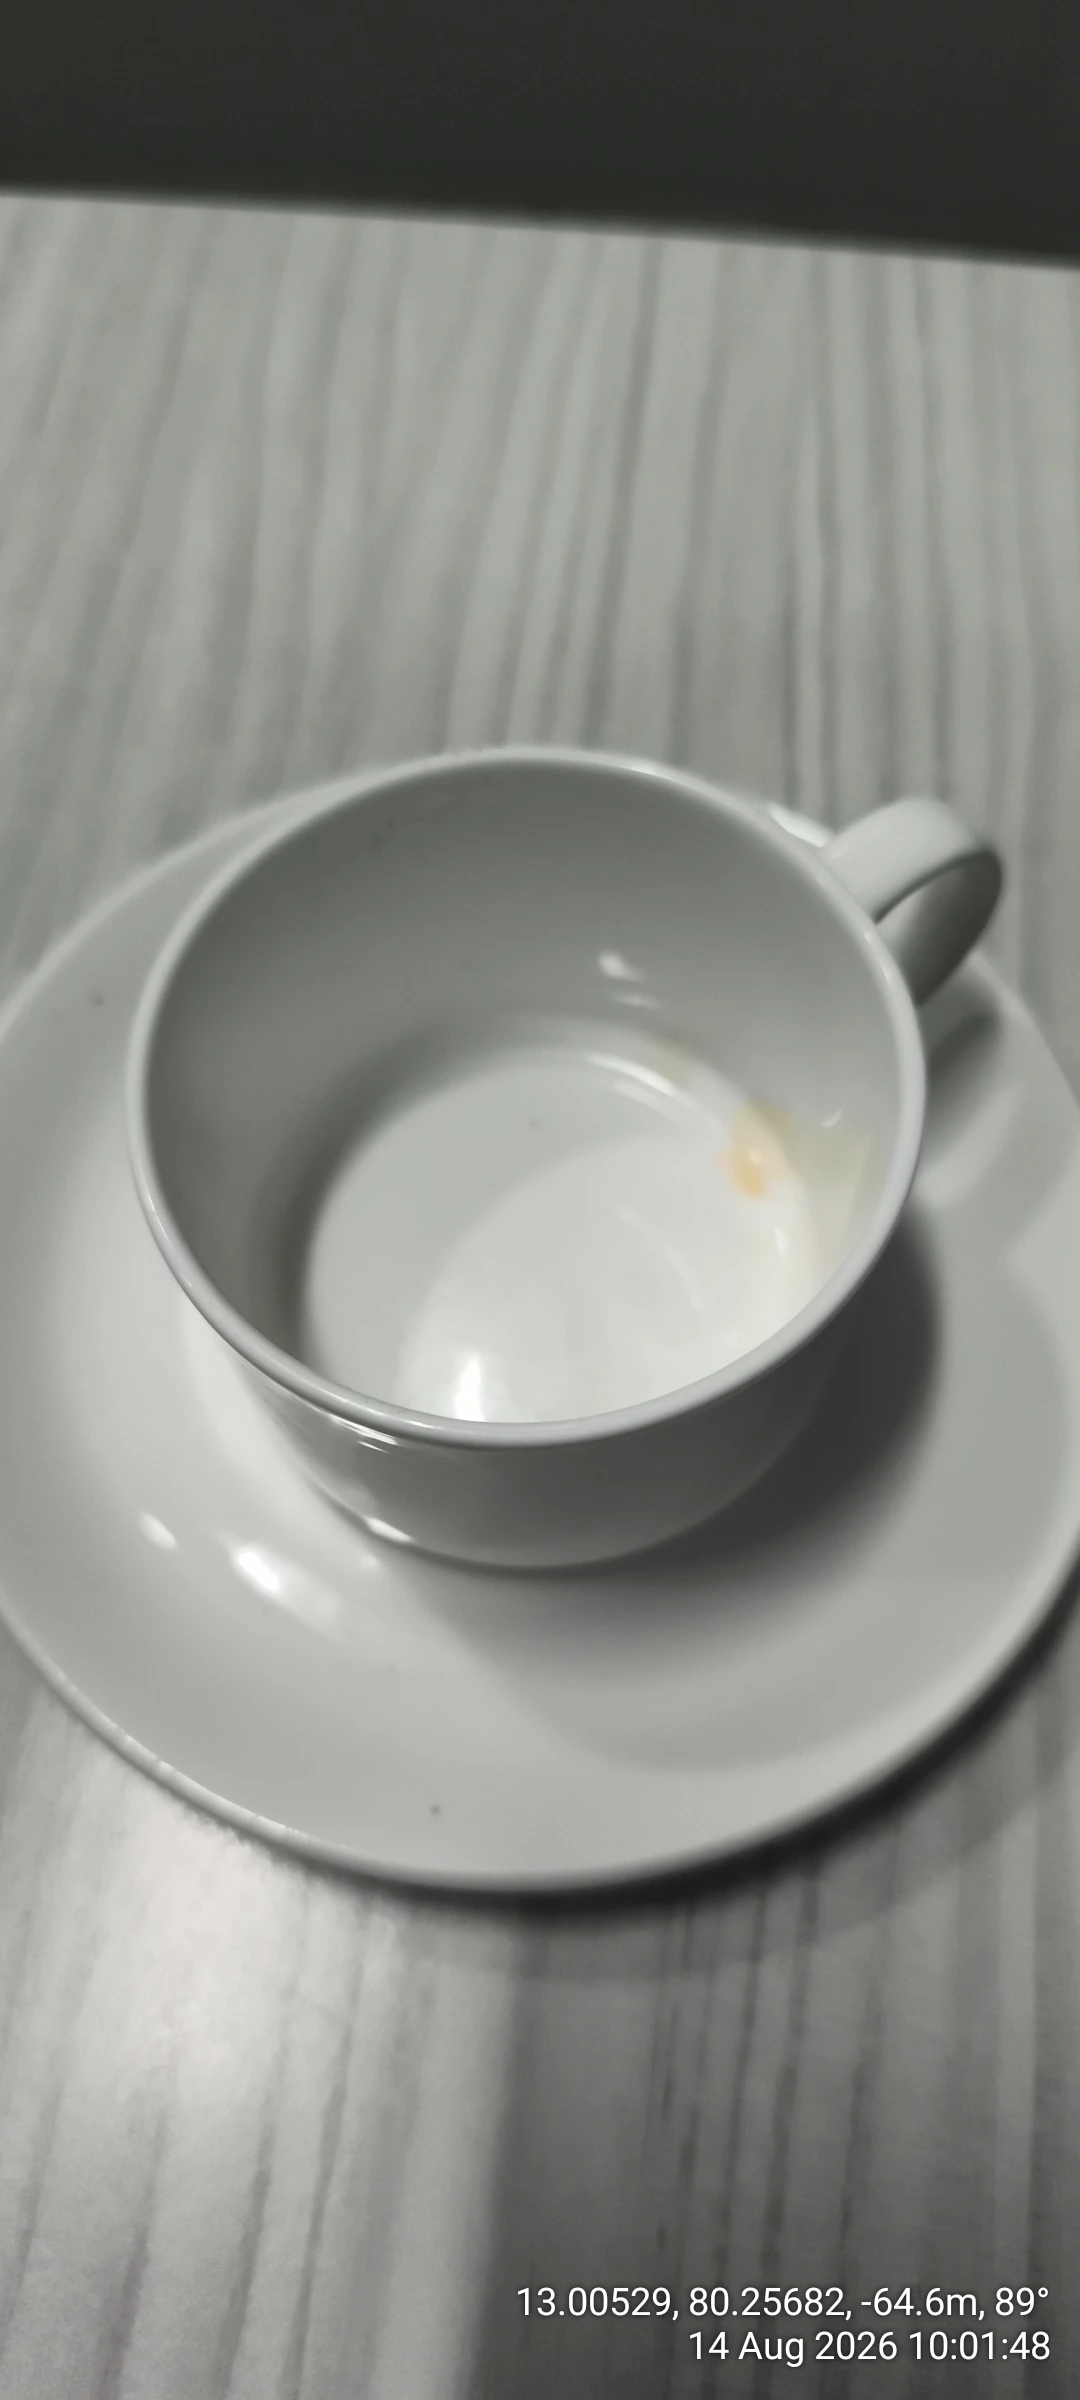
Sugar (or condensed milk) in tea I get often stays unmixed at the bottom. I forget to stir it. Is that poor design that should be fixed? Or is the steadily increasing sweetness of the tea a brilliant feature? Anyway, I therefore lick the bottom of the cup to get every last bit of sweetness. But this cup is so deep that my tongue can just about reach the bottom. And I can’t reach the bottom near the handle, because my nose is in the way. ...

Why Are You Even Sitting in This Class?

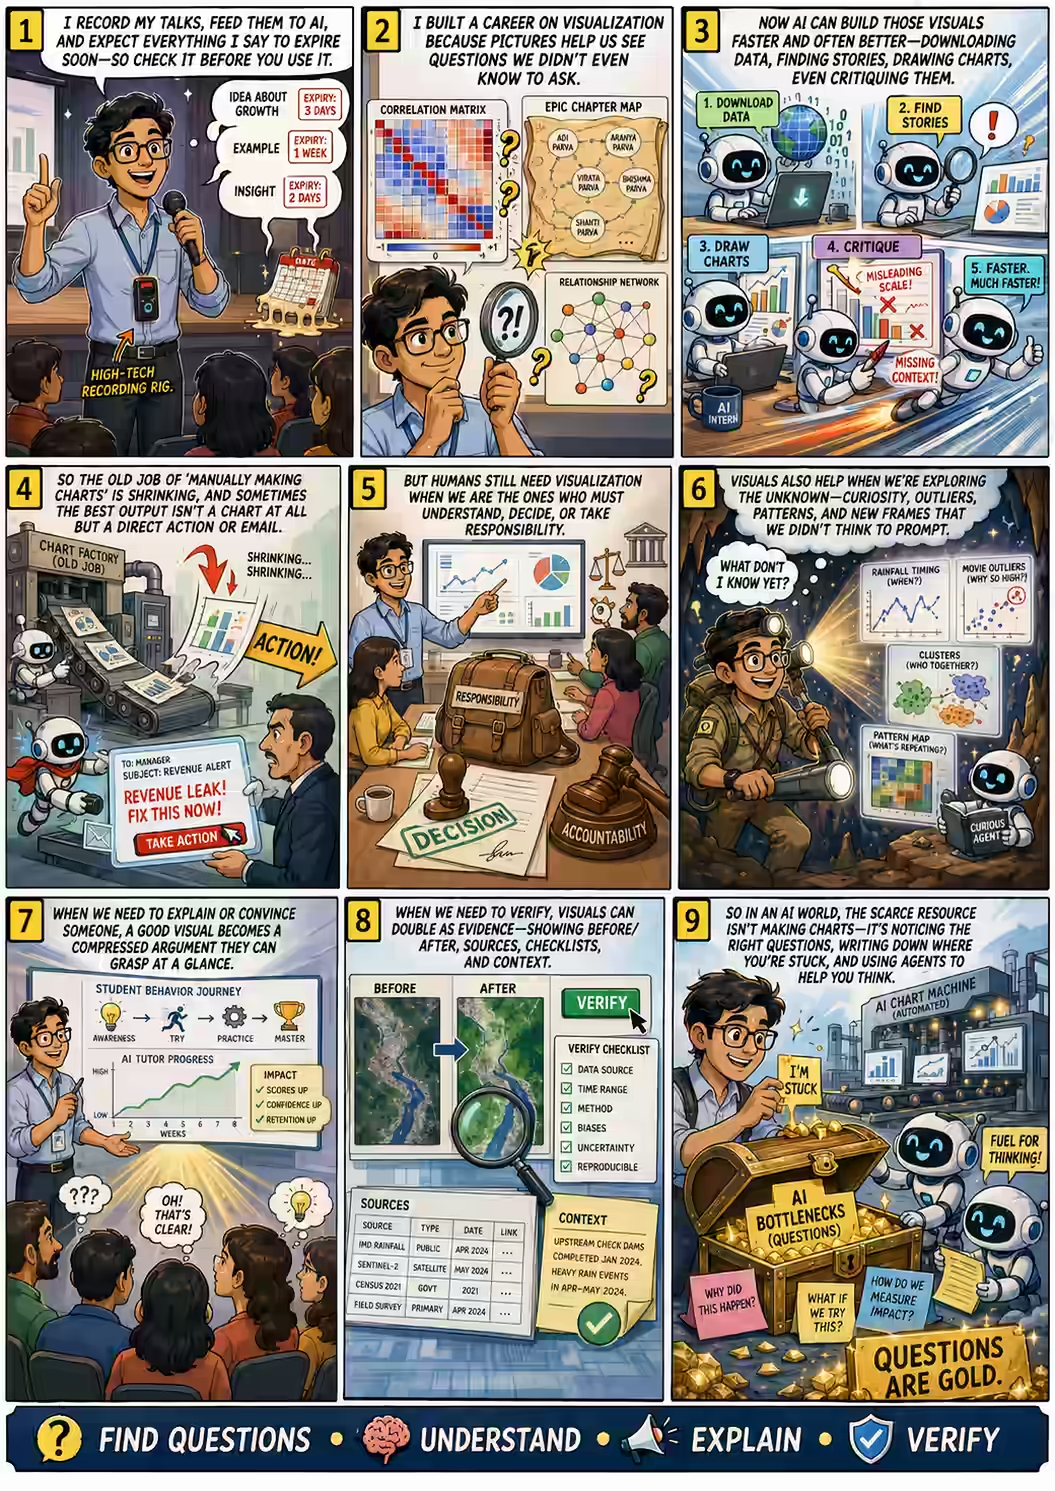
I conducted a session on Wed, 12 Aug 2026 at ED5518: Data Visualization for Engineers - Department of Engineering Design, IIT Madras, Chennai. Summary: AI can generate charts and analysis. The enduring skill is knowing what deserves to be visualized, challenged, and communicated. Here’s the link to the session Links: Transcript Audio (72 min)

What Is This Course Really Teaching?

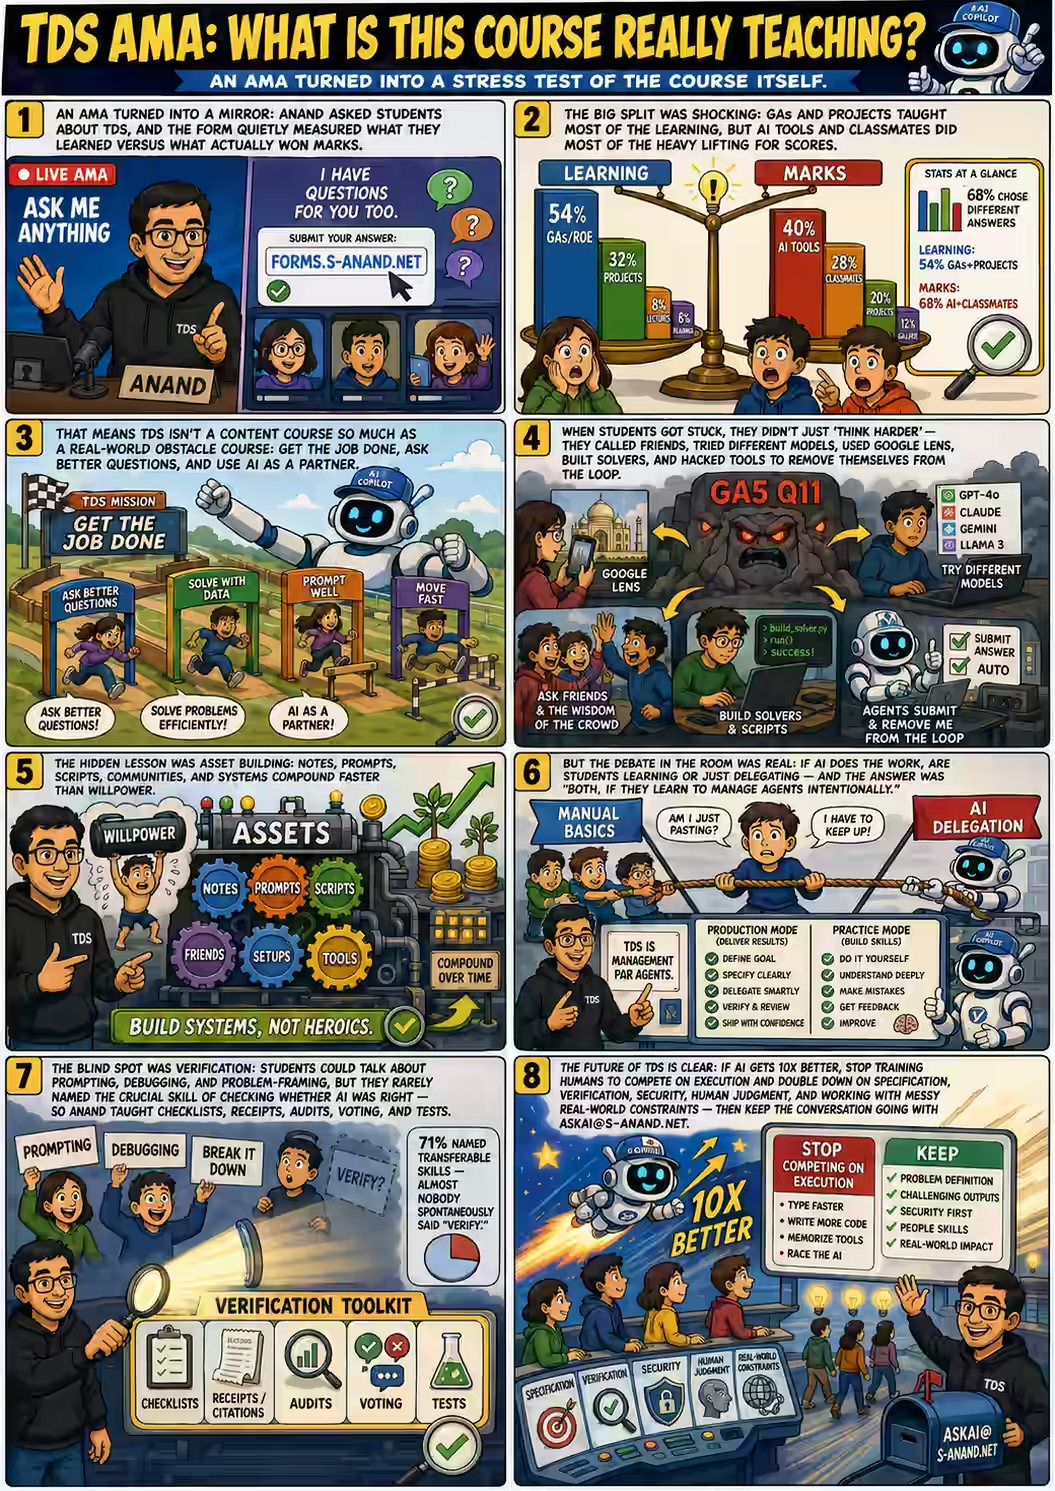
I conducted a session on Mon, 10 Aug 2026 at Tools in Data Science AMA - Remote. Summary: Tools change faster than curricula. The course is really about learning how to learn, automate work, and judge results rather than memorizing tools. Here’s the link to the session Links: Video (62 min) Transcript Audio (62 min)

Ask AI Anything Email

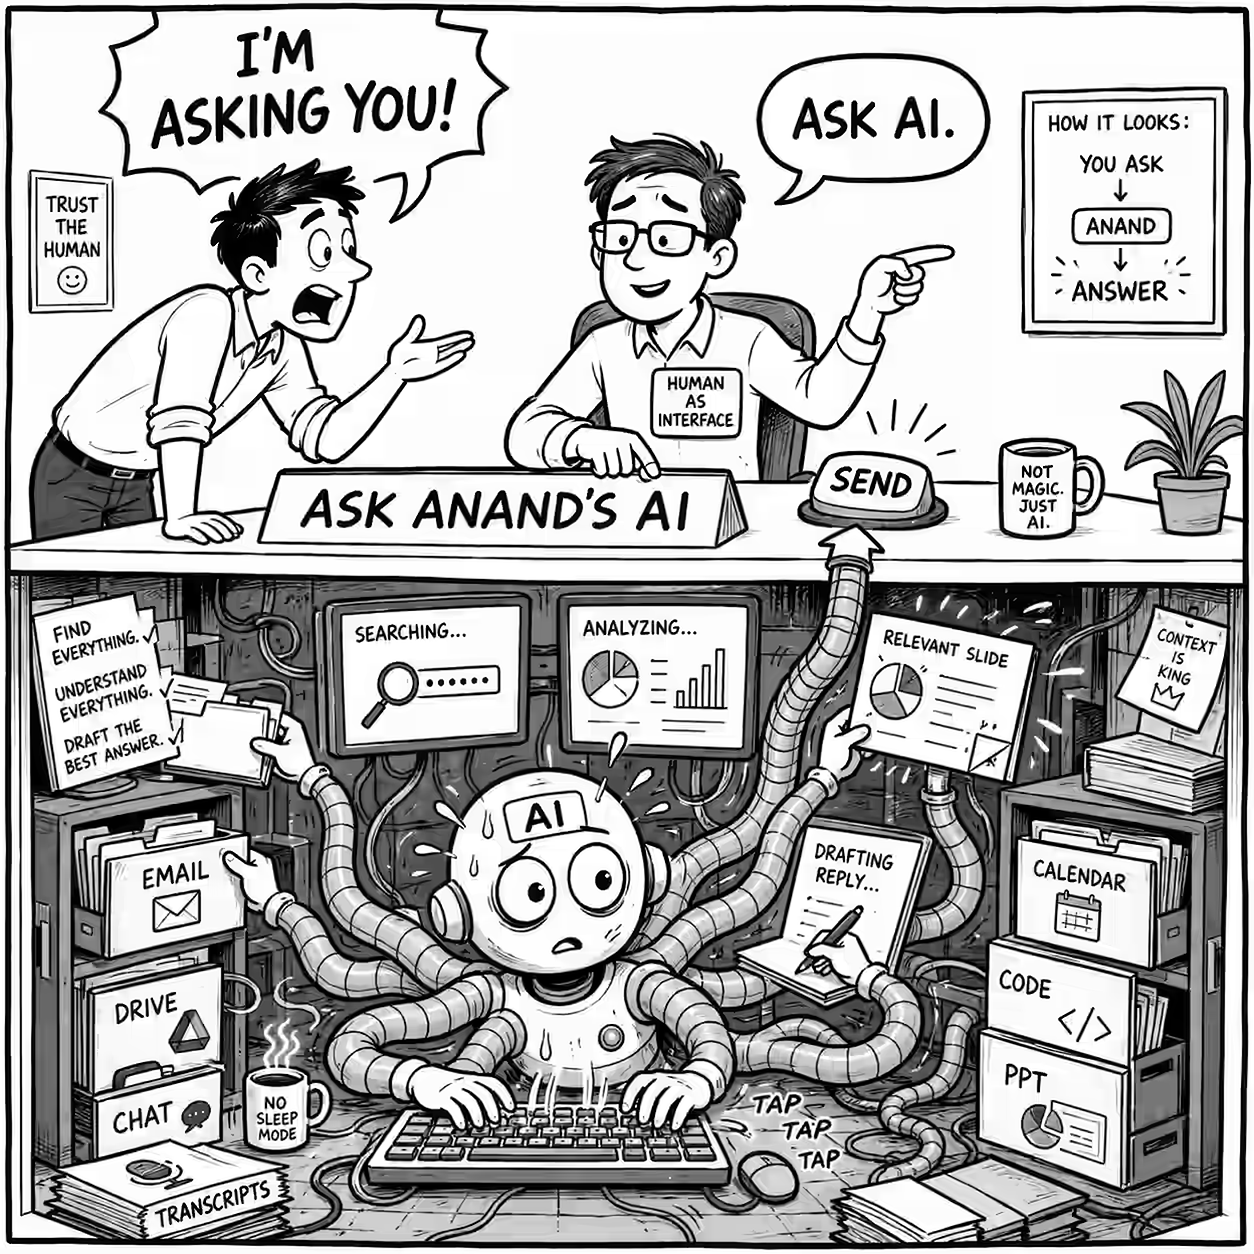
I ran, an experiment in Straive. I asked my colleagues to mail me any questions or tasks that they had. I’d use my agents + my knowledge as context and reply based on that. A few interesting things came out of it. First: It often does a better job than me - it has more patience and speed. For example: One colleague sent a detailed pitch. My agent spotted a tiny arithmetic averaging error. Another asked if I knew an ontology SME. The agent found a perfect match in my contacts - someone I would not have thought of (and reached out to.) Another asked why a slide (screenshot) was empty. The agent searched Google Drive, found the slide, analyzed it, and replied: “It’s white-on-white text. But don’t bother. The slide two pages earlier is better for your meeting!” One colleague asked: “Instead of sending this to your email id, why can’t we ask this directly into Claude or so?” It replied: ...

Dancing with eyes closed

One of my goals this year is to learn to dance. I haven’t done much about it, but I did snatch one opportunity. At VizChitra, Ashok Kumar led an Afternoon Rhythm “where the drum sets a beat and you find your place within it.” He invited volunteers on stage. I usually volunteer for uncomfortable things (a habit from school days), so I briskly walked to the stage, waited for a few others to join, then started dancing to the beat. ...

A Tea Perspective

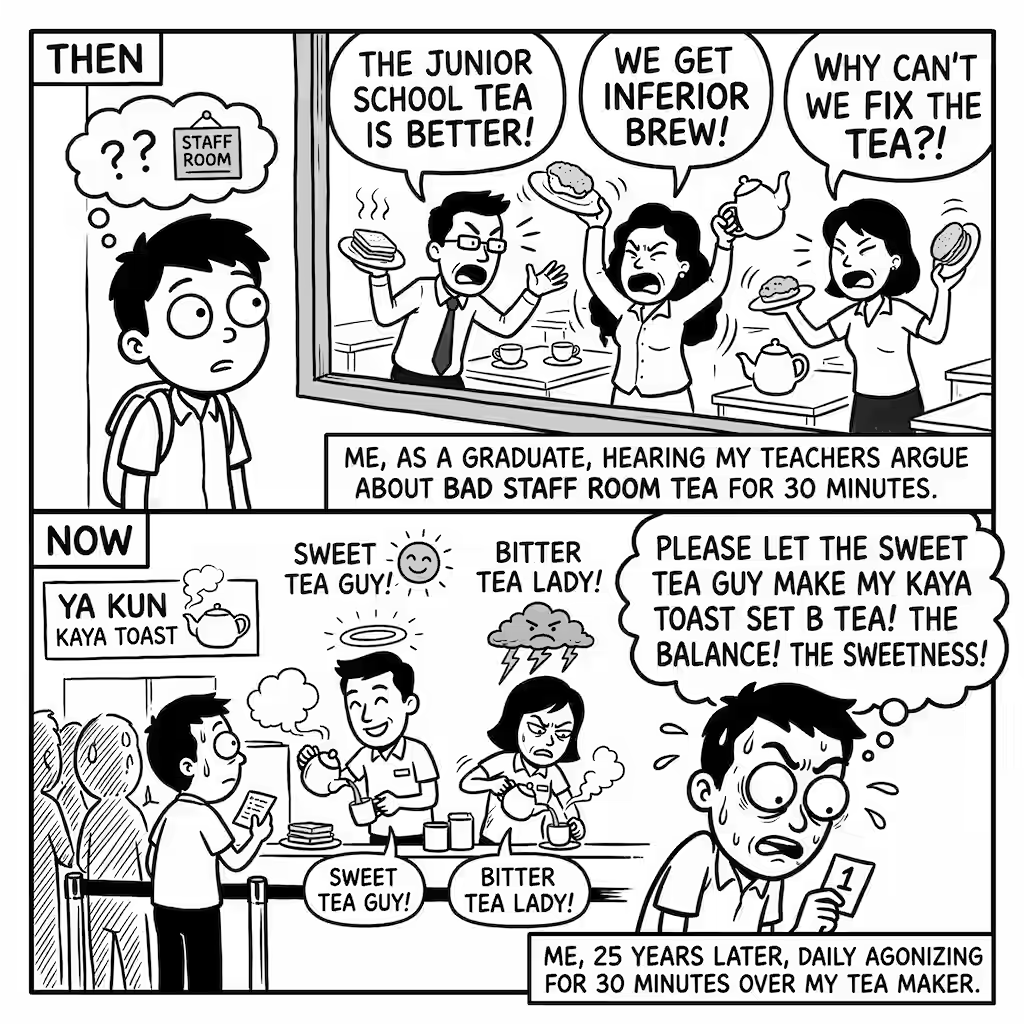
When I was at school, I assumed that teachers in the staff room would mostly be discussing students, teaching, how to improve things, etc. A few years after I graduated, I spent time with my teachers in the staff room, and realized that the conversations are far more mundane. The main topic of discussion (which went on for what felt like half-an-hour) was: Why was the tea at the high school staff room far inferior to the one for the junior school staff room? What could they do about it? ...

Comic art style prompts

Many people commented that they liked my comic illustrations and asked how I create them. Here is my process: Paste a reusable prompt fragment that’ll take any content, think about what to draw, then draw it. Paste a style variation for different comic styles (optional). Paste the content itself and run it. I use ChatGPT with gpt-image-2 more often than Gemini with Nano banana 2. Here are the prompts. STEP 1: Reusable Prompt Fragment: I have a few of these right now: ...

Things I Learned - 09 Aug 2026

This week, I learned: Kamakoti: “Entry (to the course) is relatively easy but the exit is extremely hard”. Generalizing, quality is determined by the exit criteria; loosening entry criteria is just openness / diversity. The Hindu “Once I have a persistent system that I pay to keep thinking, learning, and acting 24/7, I think that will decisively look like AGI.” - Dan Shipper AI has expert-level capabilities in many (increasing) tasks #ForNow. If your edge is OUTSIDE of those, use AI for other tasks you couldn’t do before, insourcing or expanding horizontally. But your edge may be short-term - so move upstream / specialize. Your competitors’ edge may be short-term, too - so plan to attack. Analyzing Anthropic Economic Survey, it looks like people in rich countries are asking Claude for advice (explain this spreadsheet) while poor countries are asking Claude for output (build this website) #ForNow. Maybe because rich users already have tools / people that create output for them? Humans can’t define all laws of language but LLMs have learnt them anyway. What if there are laws of nature that humans can’t understand but AI can? Actually, this is already true of black-box models (loan approvals, weather forecasts, …) where benefit/control > understanding. But as data & compute scales, this might “solve” entire fields like psychology, economics, etc. Noah Smith In each area, there might be a limit to how much intelligence is possible/useful. For example, we’re pretty good at recognizing food and emotions - there’s not much benefit / possibility of more intelligence. But we can copy and share this intelligence - and that might help more than we think. Noah Smith The ChatGPT Dropbox plugin can read Markdown files if you specify the path, but can only read PDF, Word, PPTX, Excel, etc. when searching. It cannot update files on Dropbox, but can add and delete. #ForNow Given how long agents run without mistakes, verification is increasingly “drift correction”. You can’t spot it easily. Learn writing specs that EXPOSE drift. Build and test against “oracles” (verification systems). Reduce cost of error. Permissions, in the context of multiple agents, is complex. If agent A can read my email but wants to consult agent B, can B see the email? We’d need to make permissions pretty specific, like: principal: “anand” agent: “agent-17” purpose: “insurance-coverage-check” allowed_data: [“email:read”, “dropbox/notes:read”] allowed_effects: [“email:send”] audience: [“anand”] expires_at: “…” delegation_depth: 1 After struggling to understand where to apply loop engineering, here’s my guess. If you have a metric (or something really well defined) that you want to optimize, and a single agent iteration isn’t enough, loops are a way to get there. Kaggle competitions, benchmark optimizations, etc. are examples. This means that any complex system that you can benchmark (or at least where you can robustly compare results) is loop engineerable. (This means that the ability to benchmark, and using agents to benchmark, will become a key ability.) Ontologies, state machines, etc. can be used to create verifiable systems, e.g. nodes become states, relations are valid operations. That’s great for building verifiable systems (leading to things like LEAN). Of course, a key skill will be knowing what to put into the state, what relations to allow/disallow, what reflects reality well, how it might evolve (e.g. temporal graphs), how that might change in the future, etc. Having said that, this is just creating a neural network of sorts - so according to the bitter lesson, we should just toss data at an agent and have it build a graph (or not) as required. BTW, I shared this with a bunch of speakers at Data Hack Summit who were speaking about knowledge graphs. There was silence for a while. Then, gently, they all agreed. Some people blab. Interrupting with a question is a good diversion mechanism. Some blab even after that. Exiting politely is both wise and surprisingly un-rude. To control your mental state, breathe slowly. 5–6 times/min for five minutes (that’s longer than I thought was needed), exhaling slower than you inhale. PubMed Once a ChatGPT conversation uses a developer plugin, #ForNow it refuses to use other plugins. So, if you need to use a GMail plugin AND a plugin you built yourself, you’d need to use the GMail plugin first, get stuff into the chat, then switch over to yours. I suspect conversations with developer plugins might not be accessible when using other plugins, too - but that’s untested. There’s a jagged edge of AI adoption as well, not just AI capability. Several organizations limit users to weaker agents #ForNow (e.g. only Microsoft Copilot or Gemini). Many have never seen the power of Codex or Claude Code on their systems. It’s hard to convince them that AI can do much more than they think. There’s a “data engineering” industry incentivized by structuring data. This is partly enabled by poor enterprise agent adoption #ForNow (e.g. Microsoft Copilot). The sequence works like this: “AI does not solve something with the data it’s given. Let’s structure the data. It solves it. Therefore, we need to structure data - all data.” The alternative which I believe is: agents will structure it themselves. I noticed that when you submit a prompt on ChatGPT, it changes the URL to https://chatgpt.com/c/WEB:... and once it starts processing it on the server, changes it to https://chatgpt.com/c/... giving it the actual conversation. So, if you see a WEB: in the URL #ForNow, make sure you copy the prompt before reloading the page - because it hasn’t been saved or sent to the server. I assumed inflammation was mostly a bio/chemical process. Looks like neural signals are involved, too, and electrical simulation can control inflammation. This leads us to a new territory: bio-electrical medicine. The Anthropic Economic Index indicates that, on average, if you prompt Claude like an 8th grader, it responds for a 9th grader. Does that mean (a) that more sophisticated prompts get a better response, and (b) if you repeatedly meta-prompt, you increase the sophistication by about a year each iteration, and hence can get very smart prompts by just getting out of the way and with little hope of understanding the question? This might actually make sense if AI will action the result without you needing to understand. The geometric mean is always less than or equal to the arithmetic mean. This is why a “smooth” 8% return is worth much more than a “wild” 8% return. @lumenxbt Quantum cryptography can give us unclonable encryption, i.e. if someone copies a message midway (or you publish it), you can’t independently decrypt both. We knew how to do this in 2020. Now, ChatGPT helped “indistinguishable security”. Between 2 messages, people can’t figure out (e.g. from the length, or other attributes) which message is which. Gemini Agents can record network requests into a HAR file and reverse-engineer an API for many websites. More efficient than browser control. dax The Anthropic Economic Index dataset is on Hugging Face - released quarterly #ForNow. The longitudinal analysis is likely to be interesting. BusinessCaseBench solved over 238 business cases with AI agents and they’re doing well and improving #ForNow. Not surprising. Frontier AI performance across the business disciplines OpenAI Presence shows a pathway for deploying agents. Deploy for a specific job, with only required access to knowledge and systems, company defined policies for approval, agent periodically reviews logs & escalations and proposes updates for testing and approval. A lot of work people are doing on ChatGPT is OUTSIDE their area of work. “… a substantial part of work-related ChatGPT use is from users expanding their role.” OpenAI Questions I was asked Week ending 09 Aug 2026 ...

MCP vs Shell

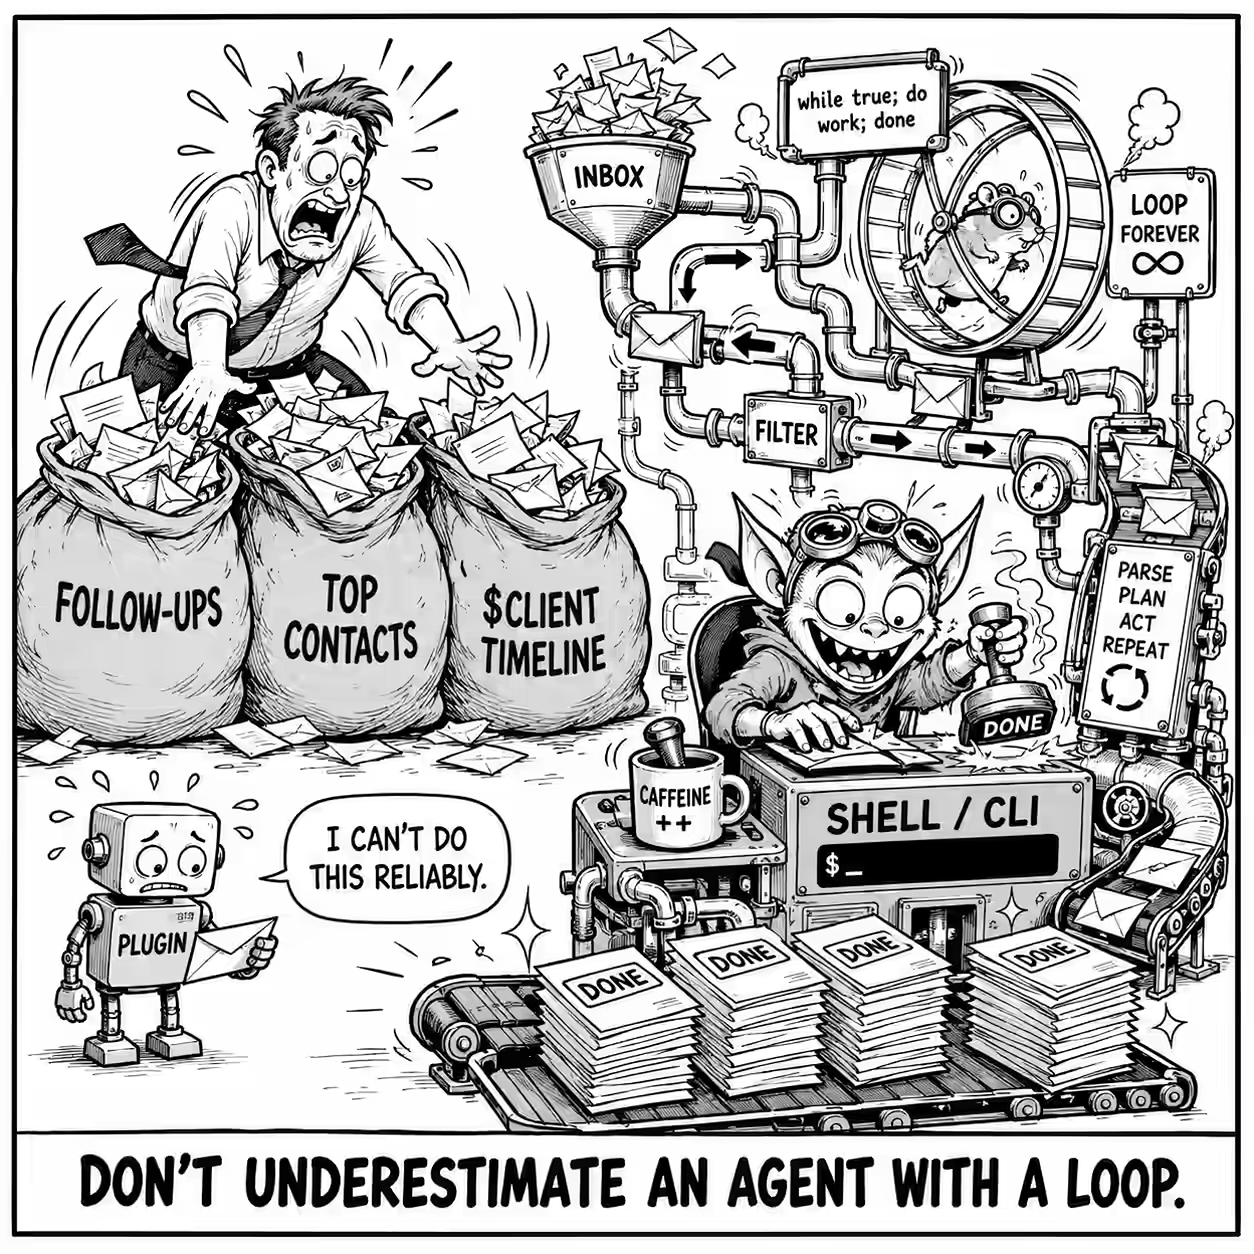
I’m a fan of the Code Mode approach - i.e. letting agents run code rather than narrow functions. Many people agree: CircleCI, Perplexity, etc. In fact, mcp2cli gives MCPs a CLI interface. I feel the main reason is UNIX composability. I can run CLI commands in a loop, pipe them, etc. I tested it out on ChatGPT. ChatGPT has an @Gmail Plugin. I build a Local MCP Server that exposes my CLIs, including gws (Google Workspace CLI). I gave it 3 tasks in a single prompt: ...

How Do You Manage Something Smarter Than You?

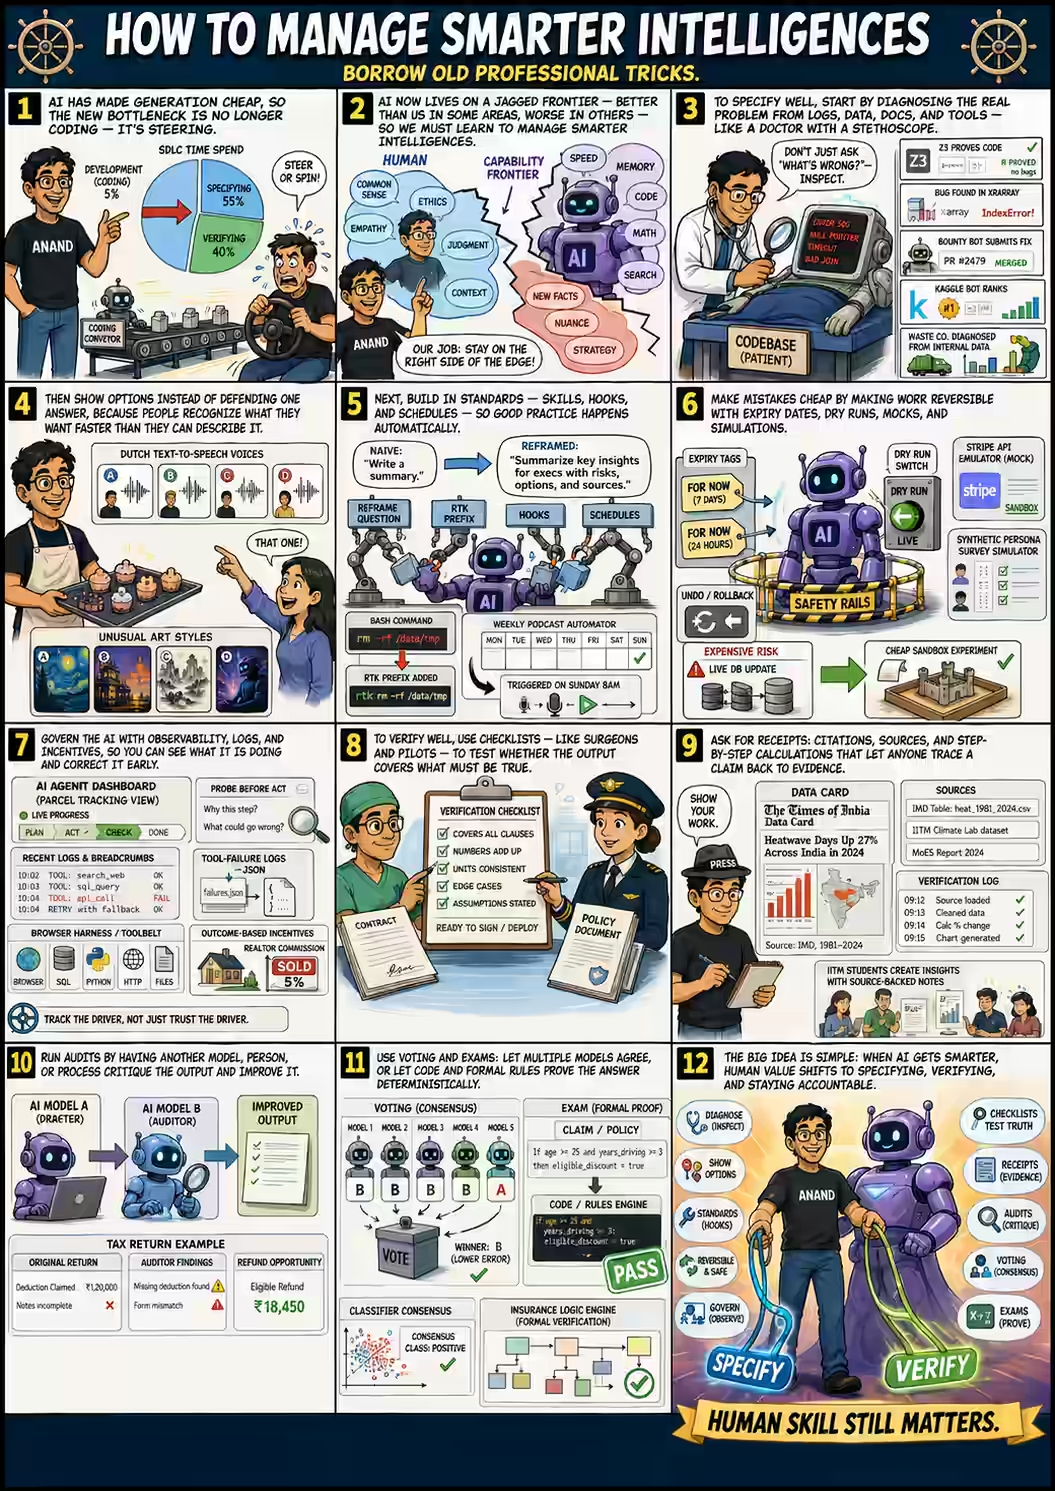
I conducted a session on Fri, 07 Aug 2026 at Data Hack Summit 2026 - Bangalore. Summary: Managing AI resembles managing experts: specify work clearly, verify outputs systematically, and borrow proven practices from professions that already manage complex judgment. Here’s the link to the session Links: Video (58 min) Transcript Audio (59 min)

AI tax returns 2026

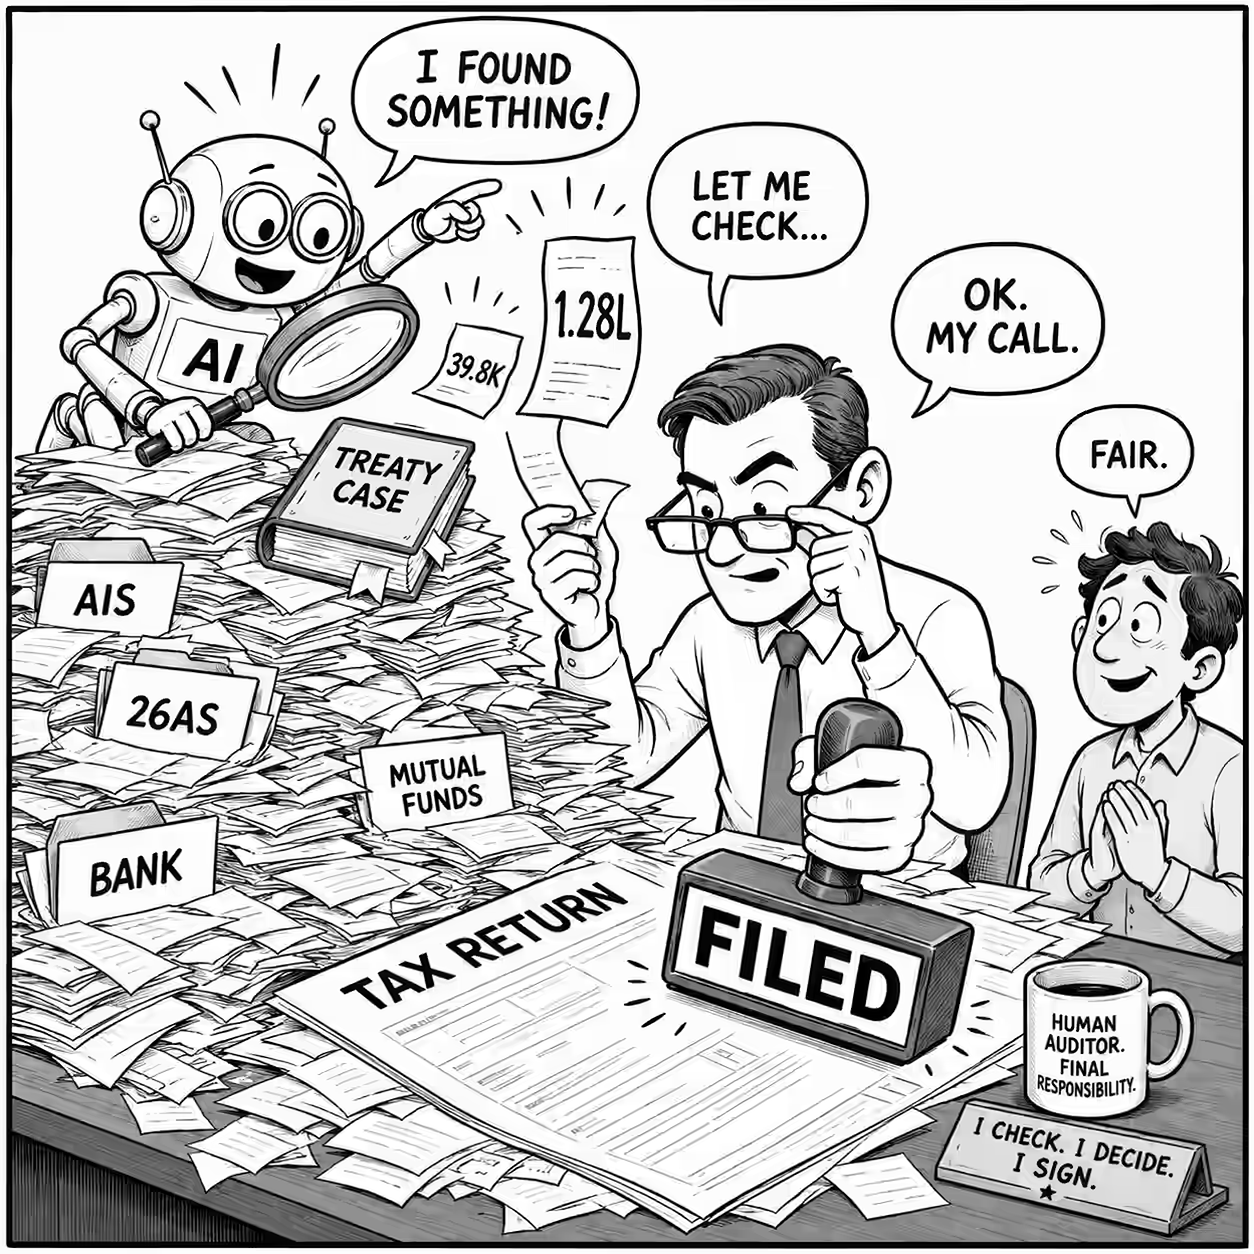
On 16 July, my auditor sent me a draft Indian tax return: a refund of Rs 3 lakhs. I gave ChatGPT my AIS, Form 26AS, bank statements, mutual fund statements, property papers, travel records, prior returns, and so on, told it not to look at the auditor’s draft, and asked it to calculate my tax independently. It calculated a refund of about Rs 2.8 lakhs, roughly Rs 20K lower. (Less money, but a smaller refund felt less worse than a larger tax.) ...

Things I Learned - 02 Aug 2026

This week, I learned: I continue to be amazed at how efficient video codecs are compared with animated image formats. When compressing 38 PNGs, the final WEBM was smaller than many of the individual PNGs! 2343k: magick -delay 50 -loop 0 file-*.png file.gif 398k: magick -delay 50 -loop 0 file-*.png file.avif (slow) 284k: magick -delay 50 -loop 0 file-*.png file.webp 82k: ffmpeg -framerate 2 -i file-%03d.png -c:v libvpx-vp9 -pix_fmt yuva420p file.webm Please use AI by Shawn Smucker is the best guide I’ve read about where NOT to use AI. I need to be more mindful of this. gpt-transcribe is released at 0.45 cents / minute or 27c / hour. Gemini 3.6 Flash costs about the same ~27c. Gemini 3 Flash costs ~15c and that’s what I use today. Gemini 3.5 Flash Lite costs ~6c / hour but it follows my instructions very poorly. To benchmark this, I just re-run my transcribe_calls.py script on a recent conversation (that I remember well) with a different model to see if it’s clearly better or worse. No fancy benchmarking. Creating / maintaining formal benchmarks isn’t always worth it. ruff 0.16 is out and has a 350+ new default rules. I mean, who would check that functools.cache on instance methods has a memory leak? But its output is so agent-friendly that agents would just fix these on the fly anyway, so it does make sense. It’s another step towards code-writing becoming less accessible to humans. npm install --no-package-lock installs packages ignoring and without creating / updating package-lock.json. Useful for dev environments. Astral has published prebuilt GPU wheels for Flash Attention, vLLM, PyCUDA, and many others. One characteristic of good benchmarks is that they are easy to verify. I see a lot of comparisons of Fable vs Opus by having them generate 3D worlds (e.g. threejs, Blender, melt) - something that’s not trivial for agents, but evaluatable at a glance. Maybe it makes sense to open source the intermediate steps in ALL knowledge work, to make AI as good at it as with code? Arvind Narayanan Open-source software and culture is a historical accident. We take it for granted that not only are the outputs of software engineers’ creative work available publicly, but so are all of the intermediate steps (specifications, plans, mockups), tacit knowledge (StackOverflow, documentation culture), detailed process traces (issues, pull requests, bug fixes, code reviews), collaboration records (version control, project boards), and more broadly a culture of learning in public. This level of explicit description would be completely alien in most professions. ...

The Falling Cost of Intelligence

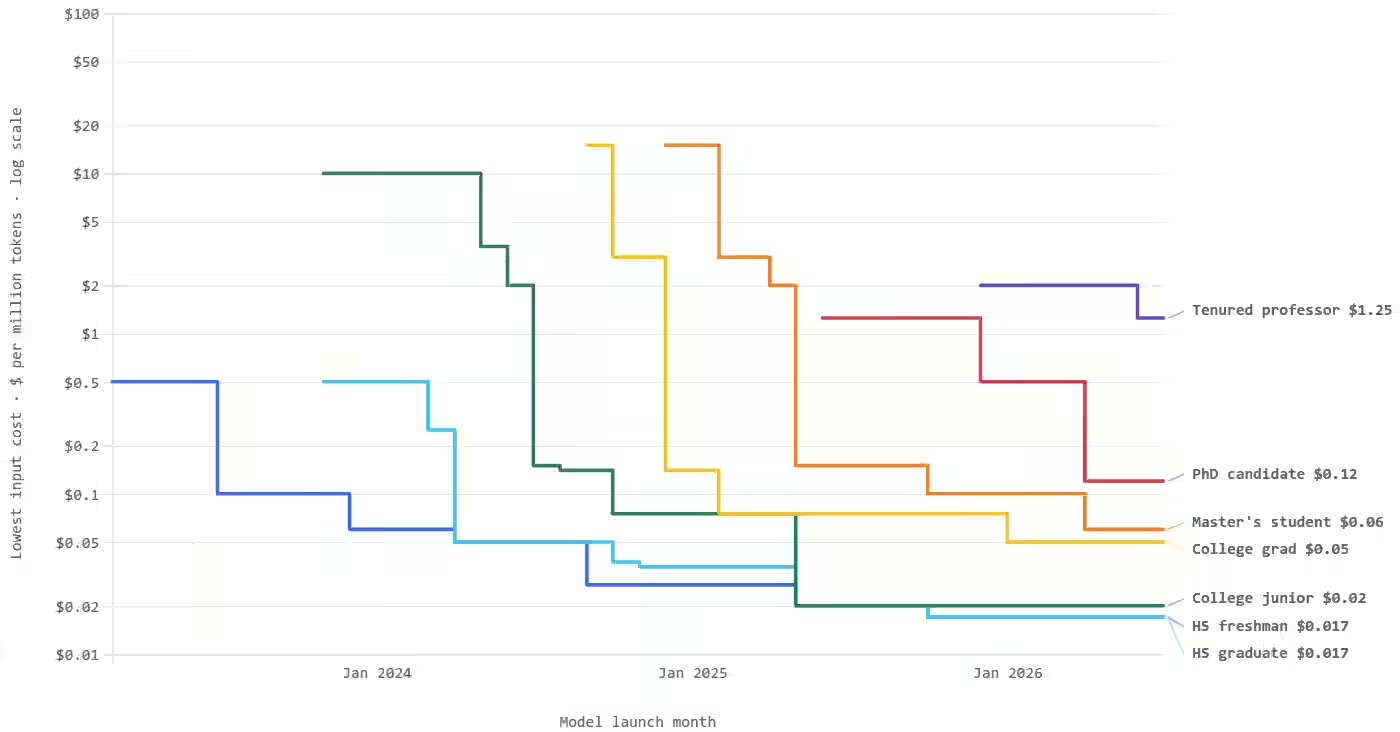
It’s amazing to watch the cost of intelligence falling. In Nov 2023, we had college-junior level intelligence for $10 per million tokens, i.e. it would take them $10 to read and process something as large as all seven Harry Potter books. ...

Simple writing hurts thinking

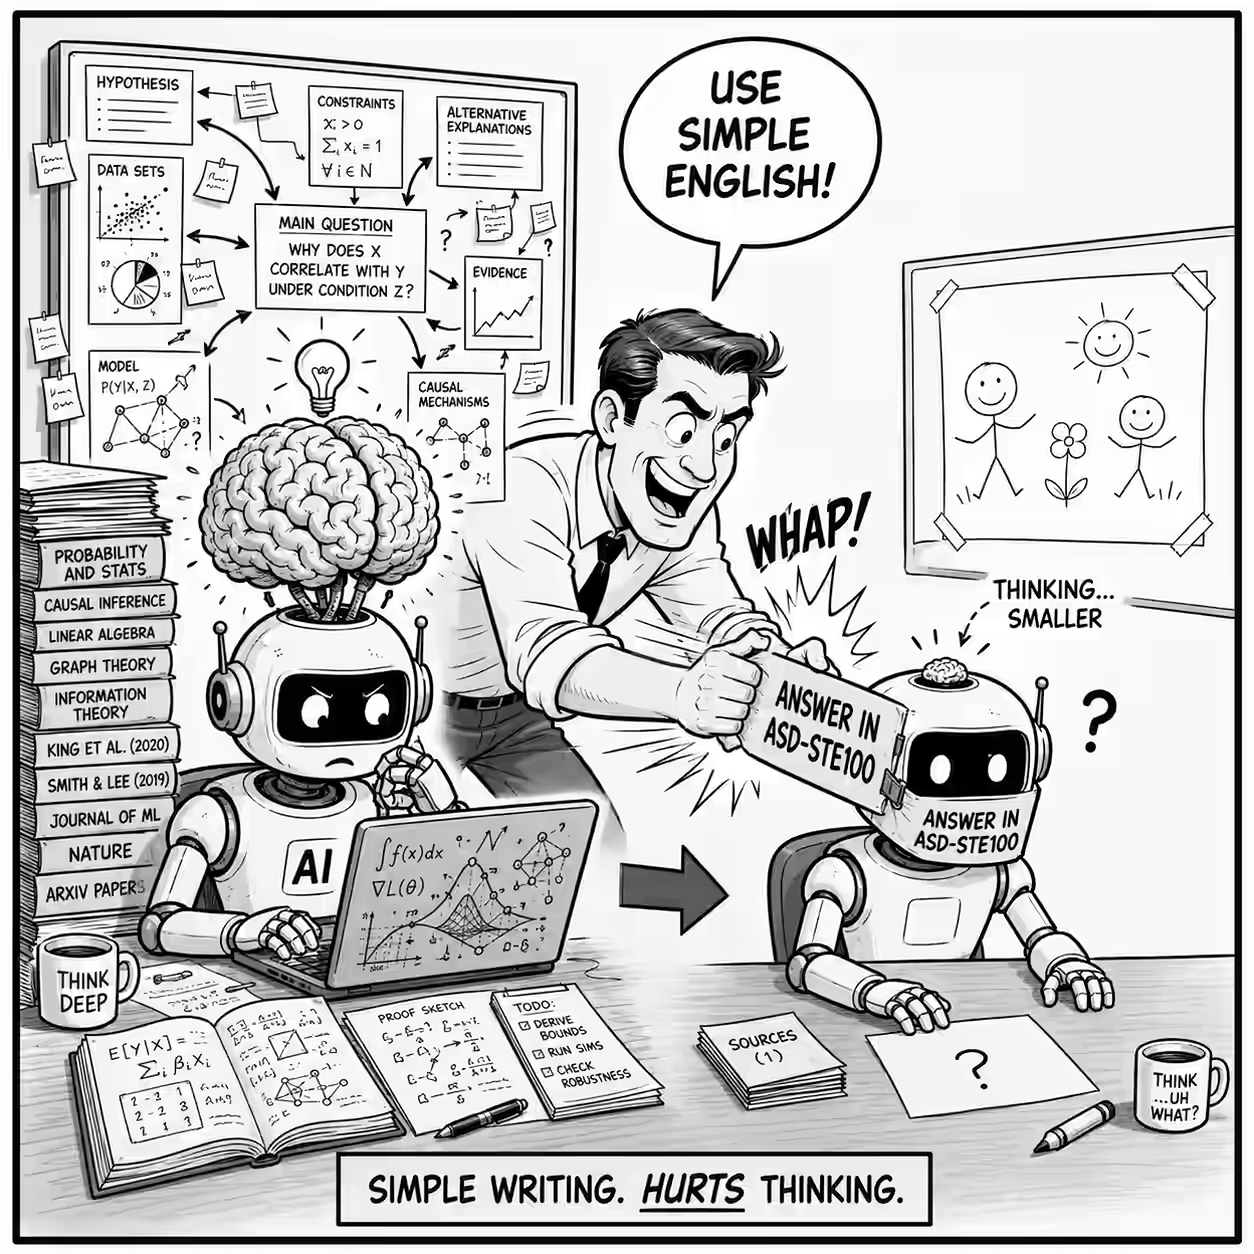
As agents get smarter, and when we ask questions outside our expertise, it’s pretty hard to understand what they’re saying. Andrew Carr uses “only report to me in ASD-STE100 Simplified Technical English” to simplify their writing. Ben Sehl suggested making this a permanent instruction. But, does simplifying the writing worsen their thinking? I tested six tasks on ChatGPT (GPT 5.6 Sol), with and without this suffix: “Answer in ASD-STE100”. ...

Agent Experience is the new User Experience

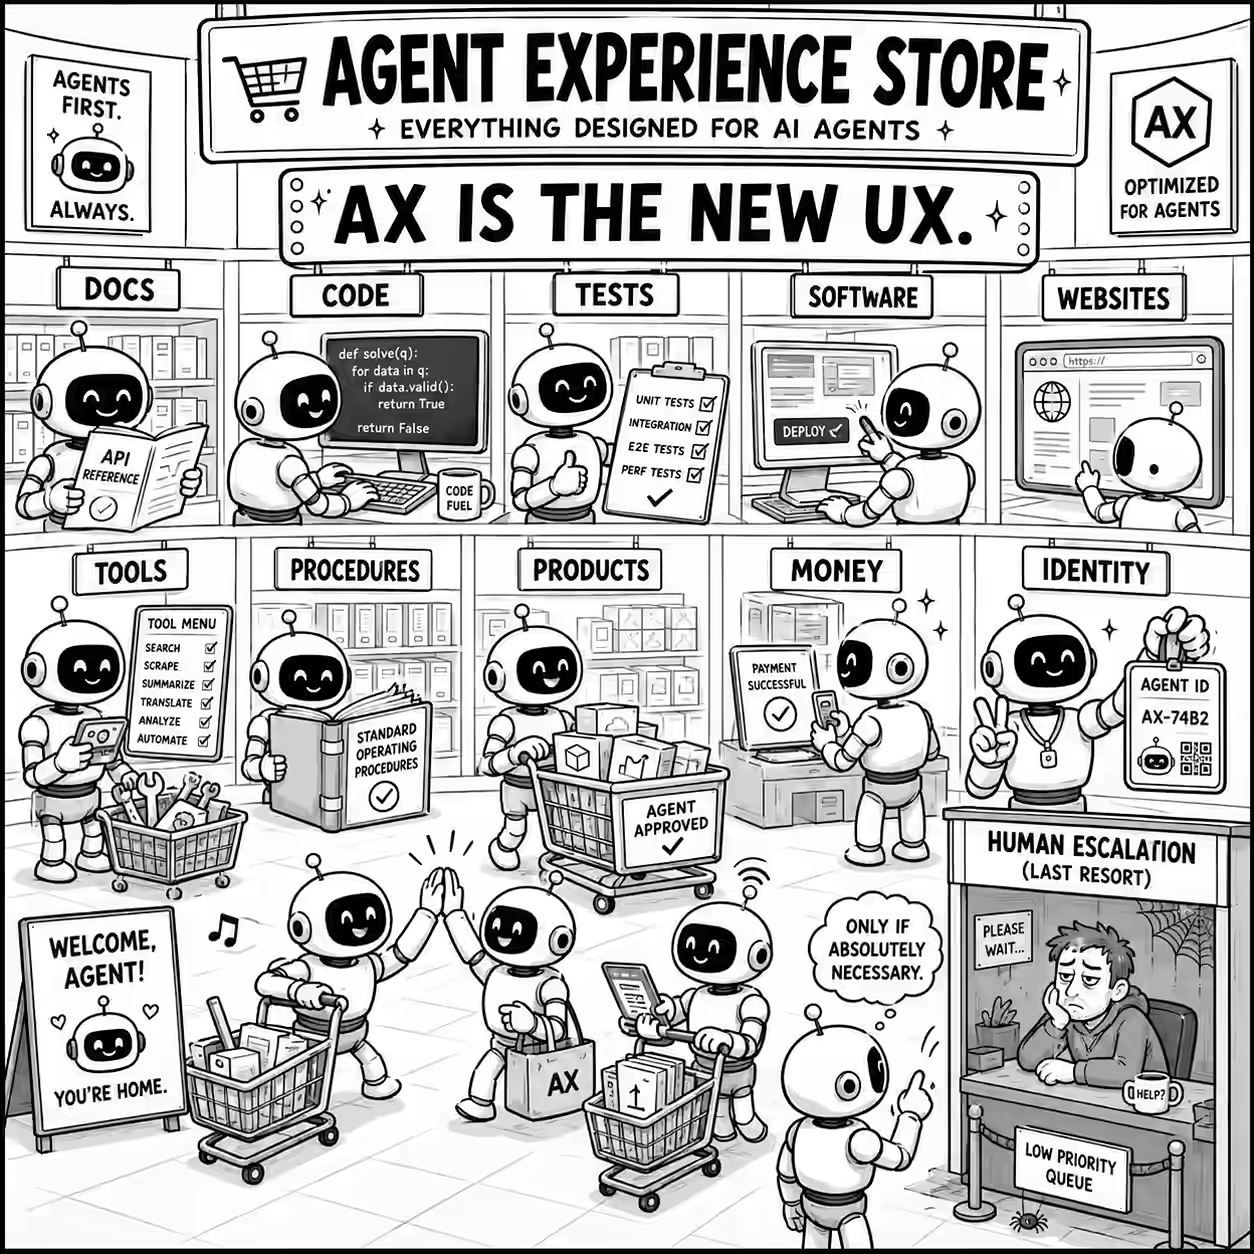
Agents are increasingly the consumers of things that used to be made for humans: Docs are increasingly for agents to read. E.g. llms.txt Code is increasingly for agents to edit. E.g. AGENTS.md Tests are increasingly for agents to satisfy. E.g. SWE-bench, GitHub repository Software is increasingly for agents to operate. E.g. --json, --schema, --dry-run, CLI-Anything, AXI Websites are increasingly for agents to invoke. E.g. WebMCP Capabilities are increasingly for agents to discover. E.g. MCP tools, MCP Registry Procedures are increasingly for agents to follow. E.g. SKILL.md, Agent Skills Products are increasingly for agents to choose. E.g. Universal Commerce Protocol Money is increasingly for agents to spend. E.g. Agent Payments Protocol Identity is increasingly for agents to prove. E.g. Visa Trusted Agent Protocol Agents are increasingly for agents to delegate to. E.g. A2A Agent Cards and Tasks Humans are increasingly for agents to escalate to. E.g. MCP Elicitation Agent Experience or AX is the new UX. ...

LLM Model Cost Capability Strategy

I track the cost vs capability of LLMs at LLM Pricing - the rough cost to read all Harry Potters (~1M tokens) vs the intelligence level on the LMSYS Leaderboard - over time. Here’s what the models’ strategy evolution looks like. Claude started at the mid-to-high end of the cost-capability frontier. Over time, they decided to specialize in the high-end, which they’re doing well on. ...

An email interface to AI

Bring AI to where people already work: email Lots of companies are putting AI into their chat applications. Add Claude to a Slack channel, tell “@Claude” to do something, and it reads the conversation, uses tools, does what you tell it to, and replies in the same chat. Nice, for companies that use Slack a lot. (Many do. We don’t.) Straive and many of our clients use email more. There’s Google Chat, Teams, and others too, but email’s what most people access. (Apart from WhatsApp.) ...